API Load Testing: 7 Checks for Trustworthy Results

API Load Testing: 7 Checks for Trustworthy Results

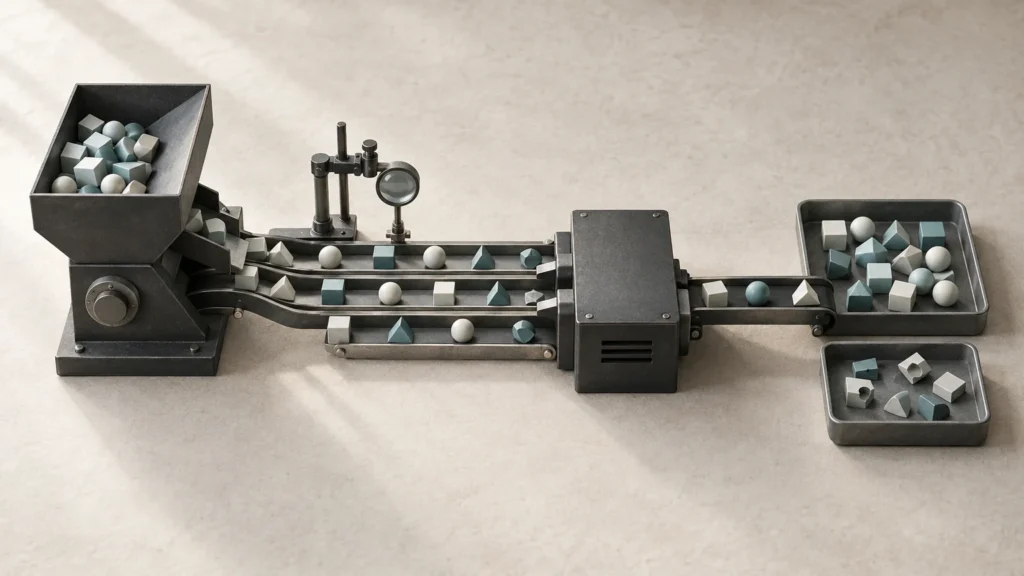
API load testing illustrated by request tokens moving through a server test bench into separate outcome trays.
A passing load test does not automatically prove release readiness. Use seven practical checks to validate API traffic, correctness, measurements, and limitations—and turn the results into an engineering decision your team can defend.
Share the Post:

The load test is green. Average response time looks healthy. Then the release reaches customers, a busy endpoint slows down, and someone asks the question the report never answered: did the test actually deliver the workload the system was expected to handle?

API load testing is not just a way to generate requests. It is a way to evaluate a specific performance claim under stated conditions. A successful tool run is evidence only if the workload, test data, measurements, environment, and acceptance criteria support that claim.

For a QA lead or backend engineer, the useful deliverable is therefore not a screenshot of a passing dashboard. It is a defensible answer: what did we test, what did we observe, and what decision can we make without overstating the result?

The following seven checks turn an API performance testing exercise into a repeatable engineering decision. They apply whether your team uses k6, an existing collection-based workflow, or another suitable tool.

1. Define the decision before configuring API load testing

Start with the decision the test must support. “Find out whether the API is fast” is too broad to guide a workload. “Evaluate whether the order-creation endpoint can sustain the forecast launch traffic while meeting our agreed response-time and correctness criteria” is actionable.

Name the operation, business consequence, expected traffic pattern, and owner of the decision. A customer-facing checkout request and an overnight synchronization job may need different latency criteria, test durations, and failure tolerances. Reusing one organization-wide latency number can hide these differences.

Write a short test charter before writing or changing the script:

  • Decision: the release, capacity change, or remediation question this run will inform.
  • Workload: named operations, request mix, arrival pattern, payload ranges, and user or tenant distribution.
  • Acceptance: route-level latency, correctness, errors, and any resource or recovery limits that matter.
  • Boundaries: environment differences, excluded dependencies, authorization, budget, and stop conditions.
  • Accountability: who executes the test, interprets exceptions, and accepts the remaining release risk.

Keep acceptance criteria separate from safety controls. A test can exceed a performance objective without creating an immediate operational emergency. Conversely, a database alarm or an unexpected effect on a shared service may require stopping a run before its planned measurement window ends.

Microsoft’s load-test criteria documentation treats pass/fail conditions and automatic stopping as distinct controls. Your own limits should reflect the environment and risk, not a copied product default.

Run only against systems and environments you are authorized to test. Agree on permitted traffic, test accounts, third-party dependencies, notification contacts, and cleanup before generating load. A technically useful experiment is still an invalid plan if it puts an unrelated service at risk.

2. Match the traffic model to the question

In API load testing, a virtual-user count does not, by itself, describe a request rate. Each simulated user may wait for a response, perform several operations, pause between actions, or retry. Those choices determine what pressure reaches the API.

In a closed model, an iteration’s completion affects when that virtual user can start another iteration. If responses slow, the resulting request rate may fall. That can be appropriate when modeling a fixed population of active users, but it does not prove that the system can absorb an independently arriving stream of work.

An open arrival model schedules new iterations independently of earlier completion. Grafana’s explanation of open and closed models describes this distinction. Choose based on the question: concurrent user behavior and externally arriving demand are different experiments.

For REST API load testing, write down the relationship between an iteration and a request. If an iteration calls three endpoints, a rate of 100 iterations per second is not automatically 100 requests per second. Branches, authentication calls, retries, and failed prerequisites can change the actual mix.

Document which traffic assumptions come from production observations and which are estimates. If you lack reliable observations, test a small set of clearly labeled scenarios rather than presenting one guess as a forecast.

For example, evaluate a read-heavy normal mix and a write-heavy launch mix separately. Keep the endpoint proportions visible in the report. An aggregate success rate dominated by inexpensive reads should not be used to approve a release whose critical operation is a write.

Finally, distinguish workload realism from maximum pressure. Removing all pauses and issuing repeated identical calls might help investigate an isolated bottleneck. It is not necessarily a model of customer behavior, and its results should be labeled accordingly.

3. Reconcile planned, started, and completed work

A trustworthy API load testing report must show whether the intended workload actually happened. Do not jump from configured traffic to a latency percentile without checking the quantities in between.

Track planned iteration starts, actual starts, requests issued, successful responses, business-level successes, errors, and unfinished work. These are different counts. Record their definitions and measurement windows so the team does not compare unlike numbers.

Consider an illustrative experiment with exactly one request per iteration, no retries, and a target of 100 starts per second for 20 minutes. That schedule implies 120,000 planned starts. If only 105,000 iterations start, the missing 15,000 are a workload shortfall. They are not 15,000 successful requests, nor automatically 15,000 server errors.

A low response-time percentile among the requests that did run cannot establish that the API met the full target workload. First explain the shortfall. Then decide whether the run answers a narrower question or must be repeated.

For API load testing with k6, the dropped-iterations documentation explains that arrival-rate executors can fail to start scheduled iterations when no virtual users are available. Too little allocated concurrency can cause this; slower system responses can also keep available users occupied. The counter alone does not identify the root cause.

Inspect load-generator resources, configured concurrency, request timing, and service telemetry together. Adding generator capacity is appropriate only when evidence shows the test harness cannot produce the intended workload. It should not become a way to ignore the service slowdown that created the backlog.

Also reserve a clearly identified completion or observation window when the scenario needs one. Otherwise, work still in flight at the end may be confused with completed work. Explain how requests that cross the measurement boundary are counted.

4. Make successful responses mean successful work

In API load testing, an HTTP response and a correct business result are not interchangeable. A fast error response, an empty result, an expired-session redirect, or a duplicate operation may look different in aggregate metrics than it does to the user trying to complete a task.

Choose assertions that match the operation. For a read, verify the expected resource and relevant response fields. For a write, validate the acknowledged result and, where practical, confirm the expected state change through an independent check. Keep the validation itself proportionate so it does not unintentionally dominate the workload.

Postman’s performance-testing documentation describes running assertions and supplying virtual users with data from a dataset. Those capabilities illustrate an important principle: reuse useful functional validation, then make identities and data realistic enough for the performance question.

A single shared account can create accidental contention. A single repeated identifier can produce unusually favorable cache behavior. A write test that continually grows a table can change conditions halfway through a run. None of these effects is automatically wrong, but each needs to be intentional.

Build a small data contract

For API load testing, record where test data comes from, how it varies, and how it is reset. Identify tenant sizes, payload sizes, key distributions, credentials, and any required token refresh behavior. Use approved synthetic or appropriately protected data rather than copying sensitive records for convenience.

Treat authentication as part of the model. Reusing a token may suit one workload; modeling login or refresh may suit another. State which behavior is included so authentication-service capacity is not silently assumed or accidentally overwhelmed.

Separate warm-cache and cold-start questions when both matter. A continuously warmed test may be valid for steady-state behavior but insufficient for a deployment that restarts instances. Keep the resulting claims separate instead of averaging incompatible conditions.

Before the full run, execute a small validation run and inspect representative results manually. Confirm that the script reaches the intended routes, assertions detect a deliberately invalid test case, and cleanup removes only the run’s own records.

5. Measure the critical route, not just the average

A single average response time can hide the endpoint, tenant, or request size that determines whether the release is acceptable. API load testing should preserve the breakdowns needed to make the actual decision.

Google’s SRE guidance organizes monitoring around latency, traffic, errors, and saturation. It also distinguishes the latency of successful and failed requests. That distinction matters when a quickly failing operation makes a combined latency measure look better.

For each critical route, review latency percentiles alongside request count, throughput, error categories, and business-level correctness. A percentile based on very few observations deserves less confidence than one supported by an adequate sample. State the sample size and duration rather than letting a precise-looking number imply certainty.

Correlate client-side observations with server-side evidence. Depending on the architecture, that might include CPU, memory, connection pools, database waits, queue depth, cache behavior, or downstream timeouts. A symptom is more actionable when the team can locate the constraint associated with it.

Do not interpret every correlation as causation. If latency and CPU rise together, that is a useful lead, not proof that adding CPU will fix the problem. Change one relevant condition, repeat the experiment, and compare evidence before declaring the bottleneck resolved.

Establish route-specific thresholds where the business requires them. Grafana’s threshold documentation shows how metric conditions can determine pass/fail and produce a nonzero exit code when a threshold fails. The useful engineering work is choosing conditions that represent your system’s obligations.

A broad threshold that averages unrelated endpoints may be convenient for a dashboard and inadequate for a release gate. Prefer a smaller number of meaningful checks over a large set of arbitrary limits that nobody can explain.

6. State what the environment and duration do not prove

A staging result is a result about the tested staging configuration. It is not a production capacity certificate. Differences in instance sizes, database volume, connection limits, network paths, autoscaling, observability overhead, and dependencies can materially change the conclusion.

Keep an environment record with the application version, relevant configuration, deployment topology, generator location, dataset characteristics, and known deviations. Use it to bound the claim, not to create a false impression that every variable was controlled.

If a downstream service is stubbed, say so. The experiment may still be useful for evaluating your application’s behavior against the stub’s configured responses. It does not establish that the real dependency will sustain the same load or exhibit the same failure behavior.

API load testing also needs a duration that suits the question. A short run can detect an immediate regression without evaluating long-running accumulation, scheduled background jobs, or recovery after an extended busy period. Longer is not inherently better; the duration must expose the behavior you need to observe.

Separate warm-up, steady measurement, stress, and recovery when those phases are relevant. Label them in charts and comparisons. Mixing warm-up into one run but excluding it from another makes an apparent improvement hard to interpret.

Plan stopping rules around concrete warning conditions and authorized limits. Do not disable safeguards simply to discover a breaking point. Where a production test is justified, it needs explicit operational approval, a bounded plan, and people able to respond.

End the run with a limitation statement: what was demonstrated, what remains uncertain, and which follow-up would reduce that uncertainty. For example, a steady-state staging test may support a regression decision while leaving production autoscaling behavior unproven.

7. Package the result as an owned release decision

The final API load testing deliverable should let another engineer understand and reproduce the decision without interviewing the person who ran the tool. Preserve the script version, configuration, dataset recipe, timestamps, relevant telemetry, and interpretation together.

Use a compact evidence record with these fields:

  • Claim tested: the operation, workload, environment, and performance conditions under evaluation.
  • Run identity: application version, test-script revision, configuration, data recipe, and measurement window.
  • Workload reconciliation: planned starts, actual starts, issued requests, completed work, and any shortfall.
  • Observed outcome: route-level latency, correctness, error categories, resource signals, and recovery behavior.
  • Validity and limitations: whether the workload was delivered, what differed from the intended environment, and what remains untested.
  • Decision and owner: proceed within stated limits, investigate a failure, or repeat an inconclusive experiment.

Keep validity separate from outcome. A valid experiment can demonstrate that the system fails its requirement. An invalid or incomplete experiment cannot demonstrate success merely because the available measurements look good.

Return to the illustrative 120,000-start schedule. If only 105,000 starts occurred, classify the full-rate conclusion as unproven until the shortfall is understood. If all scheduled work was delivered but the critical route exceeded its agreed latency limit, the result is a failed performance requirement, not a defective test by default.

This distinction prevents two expensive mistakes: tuning the application to compensate for a broken harness, and tuning the harness to make a real application constraint disappear from the report.

Make CI useful without making it misleading

For repeatable API load testing in CI, separate a short, stable regression check from larger scheduled capacity experiments. A pull-request check should have a controlled workload and a clear interpretation. It should not claim to validate every production peak simply because it runs automatically.

Define who investigates a failed gate, when a rerun is legitimate, and how exceptions are recorded. Repeatedly rerunning a noisy test until it turns green conceals uncertainty. Establish the cause of variability and adjust the test design or acceptance process transparently.

Retain comparable baselines, but do not treat an old baseline as permanent truth. Revisit it when the workload, architecture, dataset, or customer requirement changes.

Choose a delivery model that leaves the evidence with your team

The work is bounded enough to scope when you can name the critical APIs, provide an authorized environment, agree on traffic assumptions, and define the evidence required for acceptance. In that situation, a managed performance-testing project can be a sensible way to address a specific release or capacity question.

The handoff should include maintainable scripts, configuration, data-generation guidance, run instructions, findings, and a record of limitations. Your team should be able to reproduce the useful parts of the experiment after the engagement ends. Avoid a scope that promises only a load-test execution and a presentation.

When performance work is continuous and your managers will direct the priorities, an embedded specialist through nearshore staff augmentation may fit better. The distinction is who manages the work and whether you are buying ongoing capacity or a defined outcome—not which option sounds more technical.

TechAID lists performance testing among its project-outsourcing capabilities. To discuss a scoped engagement, bring your critical API workflow, expected traffic profile, and release criteria to TechAID’s project outsourcing team. The first useful conversation is about the decision you need the evidence to support.

Good API load testing ends with a bounded claim someone is willing to own. The seven checks above make that claim inspectable: realistic workload, delivered load, correct behavior, meaningful measurements, explicit limitations, and evidence your team can use again.
Key Takeaways
  • Define the release or capacity decision, workload, acceptance criteria, boundaries, and owners before configuring the test.

  • Choose an open or closed traffic model that matches the question, and make request mix and assumptions explicit.

  • Reconcile scheduled work with started iterations, issued requests, successful outcomes, errors, and unfinished work before trusting latency results.

  • Validate business-level correctness and use representative, approved test data with intentional authentication and cache behavior.

  • Interpret results alongside generator capacity, service telemetry, environment limits, and measurement boundaries; report limitations clearly.

  • The load test is green. Average response time looks healthy. Then the release reaches customers, a busy endpoint slows down, and someone asks the question the report never answered: did the test actually deliver the workload the system was expected to handle?

    API load testing is not just a way to generate requests. It is a way to evaluate a specific performance claim under stated conditions. A successful tool run is evidence only if the workload, test data, measurements, environment, and acceptance criteria support that claim.

    For a QA lead or backend engineer, the useful deliverable is therefore not a screenshot of a passing dashboard. It is a defensible answer: what did we test, what did we observe, and what decision can we make without overstating the result?

    The following seven checks turn an API performance testing exercise into a repeatable engineering decision. They apply whether your team uses k6, an existing collection-based workflow, or another suitable tool.

    1. Define the decision before configuring API load testing

    Start with the decision the test must support. “Find out whether the API is fast” is too broad to guide a workload. “Evaluate whether the order-creation endpoint can sustain the forecast launch traffic while meeting our agreed response-time and correctness criteria” is actionable.

    Name the operation, business consequence, expected traffic pattern, and owner of the decision. A customer-facing checkout request and an overnight synchronization job may need different latency criteria, test durations, and failure tolerances. Reusing one organization-wide latency number can hide these differences.

    Write a short test charter before writing or changing the script:

    • Decision: the release, capacity change, or remediation question this run will inform.
    • Workload: named operations, request mix, arrival pattern, payload ranges, and user or tenant distribution.
    • Acceptance: route-level latency, correctness, errors, and any resource or recovery limits that matter.
    • Boundaries: environment differences, excluded dependencies, authorization, budget, and stop conditions.
    • Accountability: who executes the test, interprets exceptions, and accepts the remaining release risk.

    Keep acceptance criteria separate from safety controls. A test can exceed a performance objective without creating an immediate operational emergency. Conversely, a database alarm or an unexpected effect on a shared service may require stopping a run before its planned measurement window ends.

    Microsoft’s load-test criteria documentation treats pass/fail conditions and automatic stopping as distinct controls. Your own limits should reflect the environment and risk, not a copied product default.

    Run only against systems and environments you are authorized to test. Agree on permitted traffic, test accounts, third-party dependencies, notification contacts, and cleanup before generating load. A technically useful experiment is still an invalid plan if it puts an unrelated service at risk.

    2. Match the traffic model to the question

    In API load testing, a virtual-user count does not, by itself, describe a request rate. Each simulated user may wait for a response, perform several operations, pause between actions, or retry. Those choices determine what pressure reaches the API.

    In a closed model, an iteration’s completion affects when that virtual user can start another iteration. If responses slow, the resulting request rate may fall. That can be appropriate when modeling a fixed population of active users, but it does not prove that the system can absorb an independently arriving stream of work.

    An open arrival model schedules new iterations independently of earlier completion. Grafana’s explanation of open and closed models describes this distinction. Choose based on the question: concurrent user behavior and externally arriving demand are different experiments.

    For REST API load testing, write down the relationship between an iteration and a request. If an iteration calls three endpoints, a rate of 100 iterations per second is not automatically 100 requests per second. Branches, authentication calls, retries, and failed prerequisites can change the actual mix.

    Document which traffic assumptions come from production observations and which are estimates. If you lack reliable observations, test a small set of clearly labeled scenarios rather than presenting one guess as a forecast.

    For example, evaluate a read-heavy normal mix and a write-heavy launch mix separately. Keep the endpoint proportions visible in the report. An aggregate success rate dominated by inexpensive reads should not be used to approve a release whose critical operation is a write.

    Finally, distinguish workload realism from maximum pressure. Removing all pauses and issuing repeated identical calls might help investigate an isolated bottleneck. It is not necessarily a model of customer behavior, and its results should be labeled accordingly.

    3. Reconcile planned, started, and completed work

    A trustworthy API load testing report must show whether the intended workload actually happened. Do not jump from configured traffic to a latency percentile without checking the quantities in between.

    Track planned iteration starts, actual starts, requests issued, successful responses, business-level successes, errors, and unfinished work. These are different counts. Record their definitions and measurement windows so the team does not compare unlike numbers.

    Consider an illustrative experiment with exactly one request per iteration, no retries, and a target of 100 starts per second for 20 minutes. That schedule implies 120,000 planned starts. If only 105,000 iterations start, the missing 15,000 are a workload shortfall. They are not 15,000 successful requests, nor automatically 15,000 server errors.

    A low response-time percentile among the requests that did run cannot establish that the API met the full target workload. First explain the shortfall. Then decide whether the run answers a narrower question or must be repeated.

    For API load testing with k6, the dropped-iterations documentation explains that arrival-rate executors can fail to start scheduled iterations when no virtual users are available. Too little allocated concurrency can cause this; slower system responses can also keep available users occupied. The counter alone does not identify the root cause.

    Inspect load-generator resources, configured concurrency, request timing, and service telemetry together. Adding generator capacity is appropriate only when evidence shows the test harness cannot produce the intended workload. It should not become a way to ignore the service slowdown that created the backlog.

    Also reserve a clearly identified completion or observation window when the scenario needs one. Otherwise, work still in flight at the end may be confused with completed work. Explain how requests that cross the measurement boundary are counted.

    4. Make successful responses mean successful work

    In API load testing, an HTTP response and a correct business result are not interchangeable. A fast error response, an empty result, an expired-session redirect, or a duplicate operation may look different in aggregate metrics than it does to the user trying to complete a task.

    Choose assertions that match the operation. For a read, verify the expected resource and relevant response fields. For a write, validate the acknowledged result and, where practical, confirm the expected state change through an independent check. Keep the validation itself proportionate so it does not unintentionally dominate the workload.

    Postman’s performance-testing documentation describes running assertions and supplying virtual users with data from a dataset. Those capabilities illustrate an important principle: reuse useful functional validation, then make identities and data realistic enough for the performance question.

    A single shared account can create accidental contention. A single repeated identifier can produce unusually favorable cache behavior. A write test that continually grows a table can change conditions halfway through a run. None of these effects is automatically wrong, but each needs to be intentional.

    Build a small data contract

    For API load testing, record where test data comes from, how it varies, and how it is reset. Identify tenant sizes, payload sizes, key distributions, credentials, and any required token refresh behavior. Use approved synthetic or appropriately protected data rather than copying sensitive records for convenience.

    Treat authentication as part of the model. Reusing a token may suit one workload; modeling login or refresh may suit another. State which behavior is included so authentication-service capacity is not silently assumed or accidentally overwhelmed.

    Separate warm-cache and cold-start questions when both matter. A continuously warmed test may be valid for steady-state behavior but insufficient for a deployment that restarts instances. Keep the resulting claims separate instead of averaging incompatible conditions.

    Before the full run, execute a small validation run and inspect representative results manually. Confirm that the script reaches the intended routes, assertions detect a deliberately invalid test case, and cleanup removes only the run’s own records.

    5. Measure the critical route, not just the average

    A single average response time can hide the endpoint, tenant, or request size that determines whether the release is acceptable. API load testing should preserve the breakdowns needed to make the actual decision.

    Google’s SRE guidance organizes monitoring around latency, traffic, errors, and saturation. It also distinguishes the latency of successful and failed requests. That distinction matters when a quickly failing operation makes a combined latency measure look better.

    For each critical route, review latency percentiles alongside request count, throughput, error categories, and business-level correctness. A percentile based on very few observations deserves less confidence than one supported by an adequate sample. State the sample size and duration rather than letting a precise-looking number imply certainty.

    Correlate client-side observations with server-side evidence. Depending on the architecture, that might include CPU, memory, connection pools, database waits, queue depth, cache behavior, or downstream timeouts. A symptom is more actionable when the team can locate the constraint associated with it.

    Do not interpret every correlation as causation. If latency and CPU rise together, that is a useful lead, not proof that adding CPU will fix the problem. Change one relevant condition, repeat the experiment, and compare evidence before declaring the bottleneck resolved.

    Establish route-specific thresholds where the business requires them. Grafana’s threshold documentation shows how metric conditions can determine pass/fail and produce a nonzero exit code when a threshold fails. The useful engineering work is choosing conditions that represent your system’s obligations.

    A broad threshold that averages unrelated endpoints may be convenient for a dashboard and inadequate for a release gate. Prefer a smaller number of meaningful checks over a large set of arbitrary limits that nobody can explain.

    6. State what the environment and duration do not prove

    A staging result is a result about the tested staging configuration. It is not a production capacity certificate. Differences in instance sizes, database volume, connection limits, network paths, autoscaling, observability overhead, and dependencies can materially change the conclusion.

    Keep an environment record with the application version, relevant configuration, deployment topology, generator location, dataset characteristics, and known deviations. Use it to bound the claim, not to create a false impression that every variable was controlled.

    If a downstream service is stubbed, say so. The experiment may still be useful for evaluating your application’s behavior against the stub’s configured responses. It does not establish that the real dependency will sustain the same load or exhibit the same failure behavior.

    API load testing also needs a duration that suits the question. A short run can detect an immediate regression without evaluating long-running accumulation, scheduled background jobs, or recovery after an extended busy period. Longer is not inherently better; the duration must expose the behavior you need to observe.

    Separate warm-up, steady measurement, stress, and recovery when those phases are relevant. Label them in charts and comparisons. Mixing warm-up into one run but excluding it from another makes an apparent improvement hard to interpret.

    Plan stopping rules around concrete warning conditions and authorized limits. Do not disable safeguards simply to discover a breaking point. Where a production test is justified, it needs explicit operational approval, a bounded plan, and people able to respond.

    End the run with a limitation statement: what was demonstrated, what remains uncertain, and which follow-up would reduce that uncertainty. For example, a steady-state staging test may support a regression decision while leaving production autoscaling behavior unproven.

    7. Package the result as an owned release decision

    The final API load testing deliverable should let another engineer understand and reproduce the decision without interviewing the person who ran the tool. Preserve the script version, configuration, dataset recipe, timestamps, relevant telemetry, and interpretation together.

    Use a compact evidence record with these fields:

    • Claim tested: the operation, workload, environment, and performance conditions under evaluation.
    • Run identity: application version, test-script revision, configuration, data recipe, and measurement window.
    • Workload reconciliation: planned starts, actual starts, issued requests, completed work, and any shortfall.
    • Observed outcome: route-level latency, correctness, error categories, resource signals, and recovery behavior.
    • Validity and limitations: whether the workload was delivered, what differed from the intended environment, and what remains untested.
    • Decision and owner: proceed within stated limits, investigate a failure, or repeat an inconclusive experiment.

    Keep validity separate from outcome. A valid experiment can demonstrate that the system fails its requirement. An invalid or incomplete experiment cannot demonstrate success merely because the available measurements look good.

    Return to the illustrative 120,000-start schedule. If only 105,000 starts occurred, classify the full-rate conclusion as unproven until the shortfall is understood. If all scheduled work was delivered but the critical route exceeded its agreed latency limit, the result is a failed performance requirement, not a defective test by default.

    This distinction prevents two expensive mistakes: tuning the application to compensate for a broken harness, and tuning the harness to make a real application constraint disappear from the report.

    Make CI useful without making it misleading

    For repeatable API load testing in CI, separate a short, stable regression check from larger scheduled capacity experiments. A pull-request check should have a controlled workload and a clear interpretation. It should not claim to validate every production peak simply because it runs automatically.

    Define who investigates a failed gate, when a rerun is legitimate, and how exceptions are recorded. Repeatedly rerunning a noisy test until it turns green conceals uncertainty. Establish the cause of variability and adjust the test design or acceptance process transparently.

    Retain comparable baselines, but do not treat an old baseline as permanent truth. Revisit it when the workload, architecture, dataset, or customer requirement changes.

    Choose a delivery model that leaves the evidence with your team

    The work is bounded enough to scope when you can name the critical APIs, provide an authorized environment, agree on traffic assumptions, and define the evidence required for acceptance. In that situation, a managed performance-testing project can be a sensible way to address a specific release or capacity question.

    The handoff should include maintainable scripts, configuration, data-generation guidance, run instructions, findings, and a record of limitations. Your team should be able to reproduce the useful parts of the experiment after the engagement ends. Avoid a scope that promises only a load-test execution and a presentation.

    When performance work is continuous and your managers will direct the priorities, an embedded specialist through nearshore staff augmentation may fit better. The distinction is who manages the work and whether you are buying ongoing capacity or a defined outcome—not which option sounds more technical.

    TechAID lists performance testing among its project-outsourcing capabilities. To discuss a scoped engagement, bring your critical API workflow, expected traffic profile, and release criteria to TechAID’s project outsourcing team. The first useful conversation is about the decision you need the evidence to support.

    Good API load testing ends with a bounded claim someone is willing to own. The seven checks above make that claim inspectable: realistic workload, delivered load, correct behavior, meaningful measurements, explicit limitations, and evidence your team can use again.
    Related Posts