How to Identify Engineering Bottlenecks Before Hiring More Developers

How to Identify Engineering Bottlenecks Before Hiring More Developers

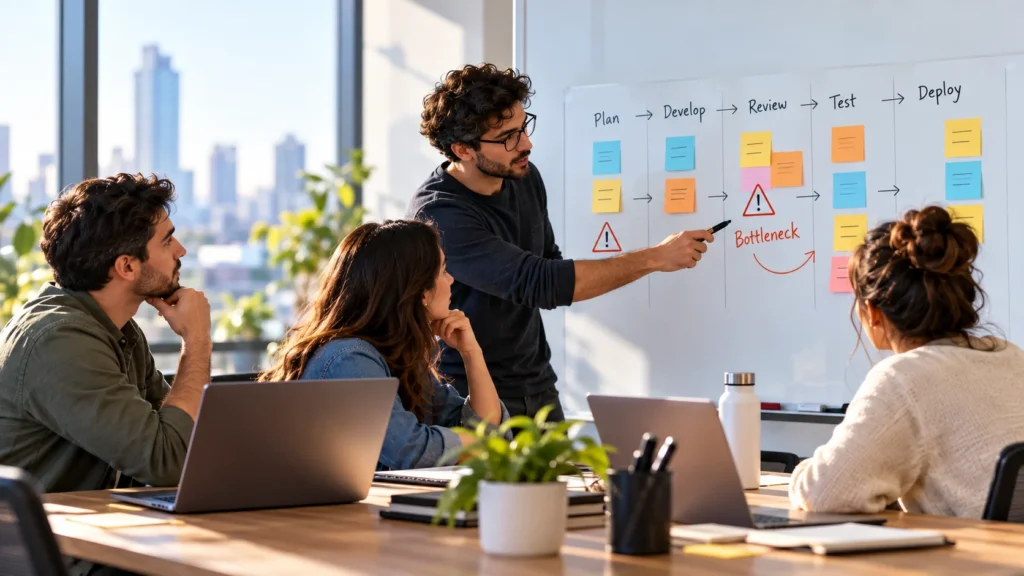
Engineering team reviewing a software delivery workflow to identify bottlenecks across planning, development, review, testing, and deployment.
A slower engineering team does not automatically need more developers. Learn how to identify bottlenecks across planning, development, review, QA, deployment, operations, and specialized expertise before adding headcount.
Share the Post:

Engineering bottlenecks can make a software team look understaffed even when the real problem is how work moves through the delivery system.

A roadmap slips. Pull requests wait longer. Releases become harder to schedule. Senior engineers seem permanently overloaded.

The immediate reaction is often:

“We need more developers.”

Sometimes that is correct.

But adding developers before identifying the constraint can create more work upstream while the same bottleneck continues limiting delivery.

If ten developers are already waiting for one reviewer, adding five more developers may increase the review queue rather than increase software delivery speed.

That is why engineering leaders should identify where work is slowing down before making a headcount decision.

This also complements a broader engineering team capacity assessment. Capacity asks whether the organization has enough resources for its priorities. Bottleneck analysis asks where the available capacity is being constrained.

The two questions are related, but they are not the same.

What an Engineering Bottleneck Actually Looks Like

An engineering bottleneck is a stage, dependency, role, or decision that consistently limits how quickly work can move through the development system.

The important word is consistently.

A pull request waiting two hours for review is not necessarily a bottleneck.

A team where dozens of changes repeatedly wait days for the same reviewer probably has one.

Likewise:

  • One failed test does not prove QA is a bottleneck.
  • One delayed deployment does not prove DevOps capacity is insufficient.
  • One difficult sprint does not prove the team is understaffed.

Look for repeated accumulation.

A bottleneck usually produces a queue.

Work arrives faster than one stage can process it, so unfinished work begins to collect in front of that constraint.

For example:

Planning → Development → Code Review → QA → Deployment
                               ↑
                         Work accumulates

Developers may continue producing code quickly, but overall delivery cannot move faster than the review stage.

That distinction is important because individual productivity and system throughput are different things.

Microsoft Research’s SPACE framework for developer productivity specifically warns against reducing developer productivity to a single activity metric. Productivity includes dimensions such as performance, activity, collaboration, efficiency, and flow.

An engineer can therefore appear highly productive while the overall engineering workflow remains slow.

Busy Teams Are Not Necessarily Bottlenecked Teams

Engineering organizations often confuse utilization with efficiency.

If every developer is busy all day, leadership may assume the team is operating at maximum productivity.

But a fully utilized system can still deliver slowly.

Imagine:

  • Developers continually start new work.
  • Pull requests accumulate.
  • QA receives large batches.
  • Releases are delayed.
  • Engineers switch between several unfinished tasks.

Everyone is active.

Very little is reaching production.

The better question is not:

“How busy is the team?”

It is:

“How smoothly does important work move from idea to production?”

That shift helps leaders focus on system throughput rather than activity.

Start With Where Work Waits

The simplest way to begin identifying engineering bottlenecks is to look for waiting.

Map the major stages of the delivery workflow.

For example:

Requirements
   ↓
Development
   ↓
Code Review
   ↓
Testing
   ↓
Security / Approval
   ↓
Deployment
   ↓
Production Verification

Then ask where work regularly stops.

Common queues include:

  • Tickets waiting for requirements
  • Developers waiting for technical decisions
  • Pull requests waiting for review
  • Features waiting for QA
  • Deployments waiting for security approval
  • Infrastructure changes waiting for DevOps
  • Releases waiting for a specific senior engineer
  • Incidents waiting for a domain expert

Those waiting periods are often more revealing than counting how many tickets each developer closes.

Measure Waiting Time, Not Just Work Time

Teams naturally pay attention to how long a task takes while someone is actively working on it.

But delivery delays often occur between activities.

A developer may spend four hours implementing a change that then waits:

  • Two days for review
  • One day for QA
  • Another day for deployment approval

The coding itself took four hours.

The delivery took nearly a week.

If leadership responds by asking developers to code faster, it is optimizing the wrong part of the system.

Instead, measure both:

  • Active work time
  • Waiting time

The difference can reveal where software delivery bottlenecks actually exist.

Look for Repeated Queues Around Specific People

Many engineering workflow bottlenecks are not stages.

They are people.

For example:

  • One architect approves every significant design decision.
  • One senior engineer reviews every backend pull request.
  • One DevOps specialist handles all production infrastructure.
  • One QA engineer approves every release.
  • One security engineer reviews every sensitive change.

These employees may be highly effective.

That is exactly why more work reaches them.

But once their workload becomes a shared dependency for several teams, they become a constraint on the system.

The solution may involve:

  • Additional specialized capacity
  • Training more reviewers
  • Distributing ownership
  • Automating routine checks
  • Documenting common decisions
  • Defining when senior approval is actually necessary

The correct response depends on why the queue exists.

Simply adding generalist developers rarely removes a specialized approval bottleneck.

Check Whether Too Much Work Is Entering the System

Not every engineering bottleneck occurs because one team lacks capacity.

Sometimes the organization is pushing too much work into development at once.

Imagine an engineering organization with capacity for three major initiatives.

Leadership starts six.

Each initiative receives some attention, but engineers continually switch between:

  • Product features
  • Customer escalations
  • Technical debt
  • Infrastructure improvements
  • Security requests
  • Production issues

Every project moves.

Few projects finish.

This can look like poor engineering velocity when the actual problem is excessive work in progress.

Too Many Priorities Create Artificial Capacity Problems

If every initiative is urgent, teams lose the ability to sequence work effectively.

Developers may spend increasing amounts of time:

  • Switching context
  • Relearning project state
  • Attending coordination meetings
  • Waiting for dependent work
  • Responding to changing priorities

The result is lower engineering efficiency even though everyone remains busy.

Before concluding that the team needs more developers, ask:

  • How many initiatives are active simultaneously?
  • How often do priorities change?
  • How frequently are engineers moved between projects?
  • How much unfinished work exists?
  • Are teams allowed to finish work before starting something new?

Reducing work in progress can sometimes improve delivery without changing headcount.

Compare Demand With the Actual Constraint

Suppose a company has a growing roadmap and releases are slowing.

There are at least two very different possibilities.

Scenario A: Genuine Capacity Constraint

The team has:

  • Stable priorities
  • Efficient workflows
  • Reasonable review times
  • Reliable automation
  • Clear ownership

But prioritized demand still consistently exceeds what the engineers can complete.

That is evidence of a real capacity gap.

Scenario B: Workflow Constraint

The team has:

  • Constantly changing priorities
  • Pull requests waiting days for review
  • Manual deployment steps
  • Repeated production interruptions
  • Unclear ownership

Adding developers may increase activity while leaving the actual delivery constraint unchanged.

That is why the first step in improving software delivery speed should be identifying the limiting part of the system.

Not increasing the number of people feeding work into it.

Look for Review and Approval Bottlenecks

A common engineering bottleneck appears after development work is technically complete.

The code exists.

The feature may even be ready for testing.

But progress stops because the work still needs:

  • Code review
  • Architecture approval
  • Security review
  • QA validation
  • Infrastructure approval
  • Release authorization

These controls can be necessary.

The problem appears when one approval stage consistently processes work more slowly than the rest of the system produces it.

Code Review Can Become a Capacity Constraint

Code review is especially vulnerable to this problem.

A team may have several developers producing changes while only one or two senior engineers are trusted to review complex work.

Over time:

  • Pull requests accumulate.
  • Developers wait for feedback.
  • Reviewers become overloaded.
  • Reviews become rushed.
  • Developers start additional tasks while waiting.
  • Work in progress increases.

The team may appear to need more developers when the actual constraint is qualified review capacity.

Before increasing headcount, ask:

  • How long do pull requests wait before the first review?
  • Which reviewers receive most of the complex work?
  • Are review responsibilities distributed?
  • Are senior engineers reviewing changes that could be handled elsewhere?
  • Can automated checks remove repetitive review work?

The goal is not to remove human review.

It is to reserve human judgment for the decisions that actually need it.

Approval Should Match Risk

Another source of delay is sending every change through the same approval process.

A low-risk documentation update should not necessarily require the same path as a production database migration.

When all changes receive maximum scrutiny, senior reviewers become bottlenecks.

Teams can often improve flow by defining different approval paths based on risk.

For example:

Lower-Risk Changes

May rely on:

  • Automated testing
  • Standard code review
  • Existing deployment controls

Higher-Risk Changes

May require:

  • Senior technical review
  • Security approval
  • Explicit deployment authorization
  • Recovery planning

The objective is proportional control.

If every decision requires the same expert, the process eventually becomes dependent on that person’s availability.

Measure Rework and Failed Handoffs

Not all engineering bottlenecks look like waiting.

Some appear as work repeatedly moving backward.

For example:

Development → QA → Development → QA → Development

Or:

Requirements → Development → Product clarification → Development

This rework consumes capacity without increasing completed delivery.

The team may be extremely active while the same work moves between stages several times.

Look for Work That Comes Back

Common examples include:

  • QA repeatedly returning features because acceptance criteria were unclear.
  • Developers rebuilding work after late product clarification.
  • Security findings appearing only before release.
  • Infrastructure requirements discovered after development is complete.
  • Code reviews identifying architectural problems that should have been discussed earlier.

The problem may not be insufficient engineering capacity.

It may be that important information arrives too late.

Ask Why the Work Was Reopened

When work returns to an earlier stage, identify the cause.

Was it:

  • Missing requirements?
  • Poor communication?
  • Insufficient testing?
  • Unclear ownership?
  • Late security involvement?
  • A technical skill gap?
  • An unstable environment?
  • A defect that should have been caught earlier?

Repeated rework is often one of the clearest software development bottlenecks because it consumes the same capacity multiple times.

Improve the Handoff, Not Just the Person

A common management reaction is to focus on who made the mistake.

But repeated handoff failures are usually better investigated as a system problem.

For example:

If QA repeatedly finds missing acceptance behavior, the question should not only be:

“Why did the developer miss this?”

Also ask:

“Was the expected behavior clear before implementation began?”

Likewise, if security repeatedly blocks releases at the final stage, the organization should ask whether security requirements can appear earlier in the development workflow.

Better handoffs reduce the amount of work that needs to travel backward.

Identify Operational Toil

Some engineering bottlenecks exist because product engineers spend too much time performing repetitive operational work.

Examples include:

  • Manual deployments
  • Repeated environment setup
  • Access requests
  • Recurring production fixes
  • Data corrections
  • Manual scaling
  • Repetitive support requests
  • Routine recovery procedures

Google SRE describes this kind of repetitive, manual operational work as toil and recommends identifying and reducing it because it can expand as systems grow.

Toil is especially dangerous because it can look like necessary work.

The tasks are real.

Someone has to do them.

But if the same operational activity happens repeatedly, the better question is whether engineering should continue performing it manually.

Toil Creates a Hidden Capacity Tax

Imagine a team of eight engineers.

If each developer loses several hours every week to recurring manual operations, the organization may effectively lose the capacity of an entire engineer without realizing it.

The instinct may be to hire a ninth developer.

But if the repetitive work remains unchanged, the new engineer will eventually inherit some of the same operational burden.

That means the underlying capacity problem continues growing with the team.

Before adding headcount, ask:

  • Which manual activities happen repeatedly?
  • Which production issues recur?
  • Which internal requests could become self-service?
  • Which deployment steps could be automated?
  • Which support tasks could be eliminated through better tooling?
  • Which recurring incidents indicate a deeper reliability problem?

Removing repeated work creates capacity for everyone already on the team.

Not All Operational Work Is Toil

Some operational responsibilities require real engineering judgment.

For example:

  • Investigating a new production failure
  • Designing a recovery strategy
  • Improving system reliability
  • Making an architectural decision

Those activities are different from repeating the same known procedure every week.

The goal is not to eliminate operations.

It is to reduce low-value repetition so engineers can spend more time on work that requires technical judgment.

Find Skill-Specific Constraints

Another common mistake is treating engineering capacity as one interchangeable pool.

It is not.

Ten software engineers do not automatically provide enough capacity if all ten depend on one specialist for a critical part of the workflow.

Engineering bottlenecks often form around skills such as:

  • DevOps
  • QA automation
  • Security
  • Cloud infrastructure
  • Data engineering
  • Backend architecture
  • Mobile development
  • Domain-specific knowledge

A company can therefore have enough total headcount and still lack the capacity required to move specific work forward.

Look for Queues Around Capabilities

Ask where several teams depend on the same expertise.

Examples:

  • All infrastructure changes wait for one DevOps engineer.
  • All automated testing improvements depend on one QA engineer.
  • All complex backend decisions require one senior architect.
  • Every security-sensitive feature depends on one specialist.
  • Several teams depend on the same data engineer.

These are more useful signals than simply comparing developer headcount with roadmap size.

General Capacity and Specialized Capacity Are Different

Suppose the bottleneck is cloud infrastructure.

Adding three frontend developers will not remove it.

Likewise, if the constraint is automated testing, increasing backend capacity may produce more work for the already constrained QA stage.

The new capacity should be added as close as possible to the actual constraint.

That may mean:

  • Hiring a specialist
  • Adding temporary specialized capacity
  • Training existing engineers
  • Redistributing ownership
  • Automating part of the work

Determine Whether the Specialist Is Doing Specialist Work

Before adding another expert, examine how the current specialist spends time.

A DevOps engineer might be overloaded because every developer needs them to create routine environments manually.

A senior engineer may be overloaded because all code reviews are routed to them regardless of complexity.

A security engineer may be overloaded because basic policy checks are not automated.

In those situations, the solution may involve freeing specialized capacity rather than immediately duplicating the role.

Ask:

  • Which tasks truly require this person’s expertise?
  • Which tasks could be automated?
  • Which decisions could be delegated?
  • Which knowledge could be documented?
  • Which responsibilities could other engineers learn?

The objective is to preserve specialist attention for specialist problems.

Treat Single Points of Expertise as a Delivery Risk

When one person becomes essential to multiple delivery paths, the issue is larger than productivity.

It creates operational risk.

Vacations, incidents, turnover, and competing priorities can all stop delivery.

Teams should therefore treat concentrated expertise as something to reduce deliberately.

Possible responses include:

  • Pairing engineers
  • Rotating reviewers
  • Documenting decisions
  • Creating runbooks
  • Cross-training
  • Standardizing common workflows
  • Adding specialized capacity where demand remains high

If the demand still exceeds available expertise after those improvements, then the organization has much stronger evidence that additional capacity is needed.

Check the Delivery Infrastructure

Some engineering bottlenecks are not caused by people or approvals.

They come from the systems teams use to build, test, and release software.

Common examples include:

  • Slow CI pipelines
  • Flaky automated tests
  • Unreliable development environments
  • Long deployment windows
  • Manual release steps
  • Infrastructure provisioning delays
  • Poor test environments
  • Frequent build failures

These problems can reduce engineering efficiency even when developers themselves are working effectively.

Slow CI/CD Creates Waiting Everywhere

A pipeline that takes too long to provide feedback can slow several parts of the development workflow.

Developers may:

  • Wait for tests before continuing
  • Delay reviews until checks finish
  • Batch changes together
  • Avoid running expensive pipelines frequently
  • Start unrelated work while waiting

That increases work in progress and context switching.

The problem is not necessarily developer productivity.

The delivery system itself is consuming time.

Flaky Tests Create False Bottlenecks

Unreliable automated tests create another form of delay.

If engineers regularly rerun pipelines because tests fail unpredictably, the team loses time investigating results that may not represent real defects.

Over time:

  • Developers stop trusting automation.
  • Reviews take longer.
  • Releases require manual verification.
  • Failed builds become routine.

The organization may respond by adding QA or development capacity while the actual constraint is test reliability.

Environment Delays Matter Too

Developers cannot deliver effectively if they regularly wait for:

  • Development environments
  • Test data
  • Cloud resources
  • Access permissions
  • Staging availability

These delays may be less visible than a code-review queue, but they still reduce software delivery speed.

A useful bottleneck assessment should therefore include the technical systems surrounding development, not only the engineers themselves.

Separate Local Productivity From System Throughput

One of the hardest engineering bottlenecks to diagnose appears when individual developers seem productive but delivery remains slow.

For example:

A developer may:

  • Complete several tickets
  • Write code quickly
  • Submit multiple pull requests

while those changes wait days for review, QA, or deployment.

From the individual’s perspective, productivity looks high.

From the customer’s perspective, nothing has shipped.

That is why optimizing local productivity can sometimes make system bottlenecks worse.

If developers produce work faster than downstream stages can process it, unfinished work accumulates.

The result is more:

  • Queues
  • Context switching
  • Merge conflicts
  • Coordination
  • Work in progress

Improving software delivery requires looking at the entire workflow.

Engineering Bottleneck or Capacity Problem?

The distinction becomes easier when common symptoms are compared directly.

What You ObservePossible Engineering BottleneckPossible Capacity Problem
Pull requests wait for daysReview ownership or approval processToo few qualified reviewers
Roadmap keeps slippingToo many priorities or delivery frictionSustained demand exceeds available team capacity
QA queue growsLate testing or unstable automationToo little QA capacity
Senior engineers are overloadedKnowledge and approval concentrated in a few peopleGenuine shortage of senior expertise
Production support consumes the weekRecurring toil or weak reliabilityOperational demand genuinely requires more people
Releases are slowCI/CD, approvals, or environment problemsToo little release/DevOps capacity
Developers are constantly switching workPoor prioritizationMore prioritized work than the team can sustainably handle

The same symptom can point to different causes.

That is why hiring should follow diagnosis rather than precede it.

How to Run a Simple Engineering Bottleneck Assessment

A bottleneck assessment does not need to become a large transformation project.

Start with a representative piece of work and follow it through the delivery process.

Step 1: Map the Workflow

Write down the major stages from request to production.

For example:

Idea
  ↓
Requirements
  ↓
Development
  ↓
Code Review
  ↓
QA
  ↓
Approval
  ↓
Deployment
  ↓
Verification

Adapt the workflow to your actual organization.

The objective is to make waiting visible.

Step 2: Identify Where Work Accumulates

Ask:

  • Where are the largest queues?
  • Which tasks wait the longest?
  • Which stages regularly send work backward?
  • Which people or skills are shared across several teams?
  • Which manual steps happen repeatedly?

Do not assume the slowest-looking team is automatically the constraint.

Look at where unfinished work accumulates.

Step 3: Separate Work Time From Wait Time

For a few representative changes, compare:

  • Time actively being worked
  • Time waiting for the next stage

This often reveals problems that ticket completion metrics hide.

A task might require eight hours of engineering work but spend five days moving through the delivery system.

Improving those eight hours will not solve most of the delay.

Step 4: Identify the Constraint Type

Classify the bottleneck.

Is it primarily:

  • Demand
  • Process
  • Approval
  • Skill
  • Automation
  • Infrastructure
  • Operational toil
  • Actual headcount

This matters because each constraint has a different solution.

Step 5: Test One Improvement

Do not immediately redesign the entire engineering organization.

Change the constraint first.

Examples:

  • Add automated review checks.
  • Train another reviewer.
  • Reduce active initiatives.
  • Automate one recurring operational task.
  • Improve flaky tests.
  • Clarify ownership.
  • Remove an unnecessary approval.

Then observe whether overall delivery improves.

If the queue simply moves to another stage, you have identified the next constraint.

Step 6: Reassess Capacity

After obvious bottlenecks are reduced, compare prioritized demand with sustainable engineering capacity again.

This is where the decision becomes clearer.

If important work still consistently exceeds what the team can deliver, the case for adding capacity becomes much stronger.

When Hiring More Developers Actually Helps

Hiring is the right response when the constraint is genuinely available engineering capacity.

That may be the case when:

  • Prioritized demand consistently exceeds sustainable capacity.
  • Workflows are reasonably efficient.
  • Major queues are not primarily caused by process problems.
  • The team has already reduced avoidable toil.
  • Required work cannot simply be automated.
  • Important skills remain overloaded.
  • The demand is expected to continue.

At that point, additional developers can increase throughput because the system has room to absorb their work.

Hire for the Constraint, Not the Average Team Profile

If the bottleneck is backend architecture, hire or add backend expertise.

If it is DevOps, adding general application developers may not help.

If QA automation is the constraint, target that capability.

The goal is not to increase headcount as evenly as possible.

It is to add capacity where it changes the delivery system.

If the team has confirmed a real gap, comparing staff augmentation vs direct hiring can help determine whether the organization needs flexible engineering capacity or long-term ownership.

Do Not Expect Instant Productivity From New Hires

Additional developers also create short-term load.

Existing engineers may need to spend time on:

  • Interviews
  • Onboarding
  • Documentation
  • Pairing
  • Code reviews
  • Knowledge transfer

That means hiring can temporarily increase pressure on the same specialists who are already constrained.

Plan for that cost.

A team should not expect a new hire to create full additional capacity immediately.

Measure Whether the Bottleneck Actually Improves

After changing the process or adding capacity, return to the original queue.

Ask:

  • Did waiting time decrease?
  • Is more work reaching production?
  • Are specialists less overloaded?
  • Is rework lower?
  • Are fewer tasks blocked?
  • Is delivery more predictable?

The objective is not simply to show that the team became larger.

It is to show that the delivery constraint improved.

The Executive Takeaway

Engineering bottlenecks are often mistaken for headcount problems because both produce the same visible result: work moves more slowly than the business expects.

But the solution depends on what is actually limiting delivery.

Before hiring more developers:

  • Map how work moves.
  • Find where it waits.
  • Measure rework.
  • Identify operational toil.
  • Look for concentrated skills.
  • Examine CI/CD and development infrastructure.
  • Reduce unnecessary work in progress.

Then reassess demand.

If the organization has improved the system and prioritized work still exceeds sustainable capacity, adding engineers becomes a much more defensible decision.

Scaling an engineering team works best when new capacity is added to a system that can use it.

If your team has identified a real delivery constraint and needs help adding the right technical capacity, start a conversation with TechAID.
Key Takeaways
  • Engineering bottlenecks can make a team look understaffed even when the real constraint is review, QA, approvals, infrastructure, operational toil, or specialized expertise.

  • Leaders should look at where work waits, how often it returns to earlier stages, and which skills or people repeatedly become shared dependencies.

  • Developer activity is not the same as software delivery throughput. Improving one part of the workflow does little if another stage remains constrained.

  • Hiring more developers makes sense after the organization has identified the bottleneck, reduced avoidable friction, and confirmed that prioritized demand still exceeds sustainable capacity.

  • Engineering bottlenecks can make a software team look understaffed even when the real problem is how work moves through the delivery system.

    A roadmap slips. Pull requests wait longer. Releases become harder to schedule. Senior engineers seem permanently overloaded.

    The immediate reaction is often:

    “We need more developers.”

    Sometimes that is correct.

    But adding developers before identifying the constraint can create more work upstream while the same bottleneck continues limiting delivery.

    If ten developers are already waiting for one reviewer, adding five more developers may increase the review queue rather than increase software delivery speed.

    That is why engineering leaders should identify where work is slowing down before making a headcount decision.

    This also complements a broader engineering team capacity assessment. Capacity asks whether the organization has enough resources for its priorities. Bottleneck analysis asks where the available capacity is being constrained.

    The two questions are related, but they are not the same.

    What an Engineering Bottleneck Actually Looks Like

    An engineering bottleneck is a stage, dependency, role, or decision that consistently limits how quickly work can move through the development system.

    The important word is consistently.

    A pull request waiting two hours for review is not necessarily a bottleneck.

    A team where dozens of changes repeatedly wait days for the same reviewer probably has one.

    Likewise:

    • One failed test does not prove QA is a bottleneck.
    • One delayed deployment does not prove DevOps capacity is insufficient.
    • One difficult sprint does not prove the team is understaffed.

    Look for repeated accumulation.

    A bottleneck usually produces a queue.

    Work arrives faster than one stage can process it, so unfinished work begins to collect in front of that constraint.

    For example:

    Planning → Development → Code Review → QA → Deployment
                                   ↑
                             Work accumulates

    Developers may continue producing code quickly, but overall delivery cannot move faster than the review stage.

    That distinction is important because individual productivity and system throughput are different things.

    Microsoft Research’s SPACE framework for developer productivity specifically warns against reducing developer productivity to a single activity metric. Productivity includes dimensions such as performance, activity, collaboration, efficiency, and flow.

    An engineer can therefore appear highly productive while the overall engineering workflow remains slow.

    Busy Teams Are Not Necessarily Bottlenecked Teams

    Engineering organizations often confuse utilization with efficiency.

    If every developer is busy all day, leadership may assume the team is operating at maximum productivity.

    But a fully utilized system can still deliver slowly.

    Imagine:

    • Developers continually start new work.
    • Pull requests accumulate.
    • QA receives large batches.
    • Releases are delayed.
    • Engineers switch between several unfinished tasks.

    Everyone is active.

    Very little is reaching production.

    The better question is not:

    “How busy is the team?”

    It is:

    “How smoothly does important work move from idea to production?”

    That shift helps leaders focus on system throughput rather than activity.

    Start With Where Work Waits

    The simplest way to begin identifying engineering bottlenecks is to look for waiting.

    Map the major stages of the delivery workflow.

    For example:

    Requirements
       ↓
    Development
       ↓
    Code Review
       ↓
    Testing
       ↓
    Security / Approval
       ↓
    Deployment
       ↓
    Production Verification

    Then ask where work regularly stops.

    Common queues include:

    • Tickets waiting for requirements
    • Developers waiting for technical decisions
    • Pull requests waiting for review
    • Features waiting for QA
    • Deployments waiting for security approval
    • Infrastructure changes waiting for DevOps
    • Releases waiting for a specific senior engineer
    • Incidents waiting for a domain expert

    Those waiting periods are often more revealing than counting how many tickets each developer closes.

    Measure Waiting Time, Not Just Work Time

    Teams naturally pay attention to how long a task takes while someone is actively working on it.

    But delivery delays often occur between activities.

    A developer may spend four hours implementing a change that then waits:

    • Two days for review
    • One day for QA
    • Another day for deployment approval

    The coding itself took four hours.

    The delivery took nearly a week.

    If leadership responds by asking developers to code faster, it is optimizing the wrong part of the system.

    Instead, measure both:

    • Active work time
    • Waiting time

    The difference can reveal where software delivery bottlenecks actually exist.

    Look for Repeated Queues Around Specific People

    Many engineering workflow bottlenecks are not stages.

    They are people.

    For example:

    • One architect approves every significant design decision.
    • One senior engineer reviews every backend pull request.
    • One DevOps specialist handles all production infrastructure.
    • One QA engineer approves every release.
    • One security engineer reviews every sensitive change.

    These employees may be highly effective.

    That is exactly why more work reaches them.

    But once their workload becomes a shared dependency for several teams, they become a constraint on the system.

    The solution may involve:

    • Additional specialized capacity
    • Training more reviewers
    • Distributing ownership
    • Automating routine checks
    • Documenting common decisions
    • Defining when senior approval is actually necessary

    The correct response depends on why the queue exists.

    Simply adding generalist developers rarely removes a specialized approval bottleneck.

    Check Whether Too Much Work Is Entering the System

    Not every engineering bottleneck occurs because one team lacks capacity.

    Sometimes the organization is pushing too much work into development at once.

    Imagine an engineering organization with capacity for three major initiatives.

    Leadership starts six.

    Each initiative receives some attention, but engineers continually switch between:

    • Product features
    • Customer escalations
    • Technical debt
    • Infrastructure improvements
    • Security requests
    • Production issues

    Every project moves.

    Few projects finish.

    This can look like poor engineering velocity when the actual problem is excessive work in progress.

    Too Many Priorities Create Artificial Capacity Problems

    If every initiative is urgent, teams lose the ability to sequence work effectively.

    Developers may spend increasing amounts of time:

    • Switching context
    • Relearning project state
    • Attending coordination meetings
    • Waiting for dependent work
    • Responding to changing priorities

    The result is lower engineering efficiency even though everyone remains busy.

    Before concluding that the team needs more developers, ask:

    • How many initiatives are active simultaneously?
    • How often do priorities change?
    • How frequently are engineers moved between projects?
    • How much unfinished work exists?
    • Are teams allowed to finish work before starting something new?

    Reducing work in progress can sometimes improve delivery without changing headcount.

    Compare Demand With the Actual Constraint

    Suppose a company has a growing roadmap and releases are slowing.

    There are at least two very different possibilities.

    Scenario A: Genuine Capacity Constraint

    The team has:

    • Stable priorities
    • Efficient workflows
    • Reasonable review times
    • Reliable automation
    • Clear ownership

    But prioritized demand still consistently exceeds what the engineers can complete.

    That is evidence of a real capacity gap.

    Scenario B: Workflow Constraint

    The team has:

    • Constantly changing priorities
    • Pull requests waiting days for review
    • Manual deployment steps
    • Repeated production interruptions
    • Unclear ownership

    Adding developers may increase activity while leaving the actual delivery constraint unchanged.

    That is why the first step in improving software delivery speed should be identifying the limiting part of the system.

    Not increasing the number of people feeding work into it.

    Look for Review and Approval Bottlenecks

    A common engineering bottleneck appears after development work is technically complete.

    The code exists.

    The feature may even be ready for testing.

    But progress stops because the work still needs:

    • Code review
    • Architecture approval
    • Security review
    • QA validation
    • Infrastructure approval
    • Release authorization

    These controls can be necessary.

    The problem appears when one approval stage consistently processes work more slowly than the rest of the system produces it.

    Code Review Can Become a Capacity Constraint

    Code review is especially vulnerable to this problem.

    A team may have several developers producing changes while only one or two senior engineers are trusted to review complex work.

    Over time:

    • Pull requests accumulate.
    • Developers wait for feedback.
    • Reviewers become overloaded.
    • Reviews become rushed.
    • Developers start additional tasks while waiting.
    • Work in progress increases.

    The team may appear to need more developers when the actual constraint is qualified review capacity.

    Before increasing headcount, ask:

    • How long do pull requests wait before the first review?
    • Which reviewers receive most of the complex work?
    • Are review responsibilities distributed?
    • Are senior engineers reviewing changes that could be handled elsewhere?
    • Can automated checks remove repetitive review work?

    The goal is not to remove human review.

    It is to reserve human judgment for the decisions that actually need it.

    Approval Should Match Risk

    Another source of delay is sending every change through the same approval process.

    A low-risk documentation update should not necessarily require the same path as a production database migration.

    When all changes receive maximum scrutiny, senior reviewers become bottlenecks.

    Teams can often improve flow by defining different approval paths based on risk.

    For example:

    Lower-Risk Changes

    May rely on:

    • Automated testing
    • Standard code review
    • Existing deployment controls

    Higher-Risk Changes

    May require:

    • Senior technical review
    • Security approval
    • Explicit deployment authorization
    • Recovery planning

    The objective is proportional control.

    If every decision requires the same expert, the process eventually becomes dependent on that person’s availability.

    Measure Rework and Failed Handoffs

    Not all engineering bottlenecks look like waiting.

    Some appear as work repeatedly moving backward.

    For example:

    Development → QA → Development → QA → Development

    Or:

    Requirements → Development → Product clarification → Development

    This rework consumes capacity without increasing completed delivery.

    The team may be extremely active while the same work moves between stages several times.

    Look for Work That Comes Back

    Common examples include:

    • QA repeatedly returning features because acceptance criteria were unclear.
    • Developers rebuilding work after late product clarification.
    • Security findings appearing only before release.
    • Infrastructure requirements discovered after development is complete.
    • Code reviews identifying architectural problems that should have been discussed earlier.

    The problem may not be insufficient engineering capacity.

    It may be that important information arrives too late.

    Ask Why the Work Was Reopened

    When work returns to an earlier stage, identify the cause.

    Was it:

    • Missing requirements?
    • Poor communication?
    • Insufficient testing?
    • Unclear ownership?
    • Late security involvement?
    • A technical skill gap?
    • An unstable environment?
    • A defect that should have been caught earlier?

    Repeated rework is often one of the clearest software development bottlenecks because it consumes the same capacity multiple times.

    Improve the Handoff, Not Just the Person

    A common management reaction is to focus on who made the mistake.

    But repeated handoff failures are usually better investigated as a system problem.

    For example:

    If QA repeatedly finds missing acceptance behavior, the question should not only be:

    “Why did the developer miss this?”

    Also ask:

    “Was the expected behavior clear before implementation began?”

    Likewise, if security repeatedly blocks releases at the final stage, the organization should ask whether security requirements can appear earlier in the development workflow.

    Better handoffs reduce the amount of work that needs to travel backward.

    Identify Operational Toil

    Some engineering bottlenecks exist because product engineers spend too much time performing repetitive operational work.

    Examples include:

    • Manual deployments
    • Repeated environment setup
    • Access requests
    • Recurring production fixes
    • Data corrections
    • Manual scaling
    • Repetitive support requests
    • Routine recovery procedures

    Google SRE describes this kind of repetitive, manual operational work as toil and recommends identifying and reducing it because it can expand as systems grow.

    Toil is especially dangerous because it can look like necessary work.

    The tasks are real.

    Someone has to do them.

    But if the same operational activity happens repeatedly, the better question is whether engineering should continue performing it manually.

    Toil Creates a Hidden Capacity Tax

    Imagine a team of eight engineers.

    If each developer loses several hours every week to recurring manual operations, the organization may effectively lose the capacity of an entire engineer without realizing it.

    The instinct may be to hire a ninth developer.

    But if the repetitive work remains unchanged, the new engineer will eventually inherit some of the same operational burden.

    That means the underlying capacity problem continues growing with the team.

    Before adding headcount, ask:

    • Which manual activities happen repeatedly?
    • Which production issues recur?
    • Which internal requests could become self-service?
    • Which deployment steps could be automated?
    • Which support tasks could be eliminated through better tooling?
    • Which recurring incidents indicate a deeper reliability problem?

    Removing repeated work creates capacity for everyone already on the team.

    Not All Operational Work Is Toil

    Some operational responsibilities require real engineering judgment.

    For example:

    • Investigating a new production failure
    • Designing a recovery strategy
    • Improving system reliability
    • Making an architectural decision

    Those activities are different from repeating the same known procedure every week.

    The goal is not to eliminate operations.

    It is to reduce low-value repetition so engineers can spend more time on work that requires technical judgment.

    Find Skill-Specific Constraints

    Another common mistake is treating engineering capacity as one interchangeable pool.

    It is not.

    Ten software engineers do not automatically provide enough capacity if all ten depend on one specialist for a critical part of the workflow.

    Engineering bottlenecks often form around skills such as:

    • DevOps
    • QA automation
    • Security
    • Cloud infrastructure
    • Data engineering
    • Backend architecture
    • Mobile development
    • Domain-specific knowledge

    A company can therefore have enough total headcount and still lack the capacity required to move specific work forward.

    Look for Queues Around Capabilities

    Ask where several teams depend on the same expertise.

    Examples:

    • All infrastructure changes wait for one DevOps engineer.
    • All automated testing improvements depend on one QA engineer.
    • All complex backend decisions require one senior architect.
    • Every security-sensitive feature depends on one specialist.
    • Several teams depend on the same data engineer.

    These are more useful signals than simply comparing developer headcount with roadmap size.

    General Capacity and Specialized Capacity Are Different

    Suppose the bottleneck is cloud infrastructure.

    Adding three frontend developers will not remove it.

    Likewise, if the constraint is automated testing, increasing backend capacity may produce more work for the already constrained QA stage.

    The new capacity should be added as close as possible to the actual constraint.

    That may mean:

    • Hiring a specialist
    • Adding temporary specialized capacity
    • Training existing engineers
    • Redistributing ownership
    • Automating part of the work

    Determine Whether the Specialist Is Doing Specialist Work

    Before adding another expert, examine how the current specialist spends time.

    A DevOps engineer might be overloaded because every developer needs them to create routine environments manually.

    A senior engineer may be overloaded because all code reviews are routed to them regardless of complexity.

    A security engineer may be overloaded because basic policy checks are not automated.

    In those situations, the solution may involve freeing specialized capacity rather than immediately duplicating the role.

    Ask:

    • Which tasks truly require this person’s expertise?
    • Which tasks could be automated?
    • Which decisions could be delegated?
    • Which knowledge could be documented?
    • Which responsibilities could other engineers learn?

    The objective is to preserve specialist attention for specialist problems.

    Treat Single Points of Expertise as a Delivery Risk

    When one person becomes essential to multiple delivery paths, the issue is larger than productivity.

    It creates operational risk.

    Vacations, incidents, turnover, and competing priorities can all stop delivery.

    Teams should therefore treat concentrated expertise as something to reduce deliberately.

    Possible responses include:

    • Pairing engineers
    • Rotating reviewers
    • Documenting decisions
    • Creating runbooks
    • Cross-training
    • Standardizing common workflows
    • Adding specialized capacity where demand remains high

    If the demand still exceeds available expertise after those improvements, then the organization has much stronger evidence that additional capacity is needed.

    Check the Delivery Infrastructure

    Some engineering bottlenecks are not caused by people or approvals.

    They come from the systems teams use to build, test, and release software.

    Common examples include:

    • Slow CI pipelines
    • Flaky automated tests
    • Unreliable development environments
    • Long deployment windows
    • Manual release steps
    • Infrastructure provisioning delays
    • Poor test environments
    • Frequent build failures

    These problems can reduce engineering efficiency even when developers themselves are working effectively.

    Slow CI/CD Creates Waiting Everywhere

    A pipeline that takes too long to provide feedback can slow several parts of the development workflow.

    Developers may:

    • Wait for tests before continuing
    • Delay reviews until checks finish
    • Batch changes together
    • Avoid running expensive pipelines frequently
    • Start unrelated work while waiting

    That increases work in progress and context switching.

    The problem is not necessarily developer productivity.

    The delivery system itself is consuming time.

    Flaky Tests Create False Bottlenecks

    Unreliable automated tests create another form of delay.

    If engineers regularly rerun pipelines because tests fail unpredictably, the team loses time investigating results that may not represent real defects.

    Over time:

    • Developers stop trusting automation.
    • Reviews take longer.
    • Releases require manual verification.
    • Failed builds become routine.

    The organization may respond by adding QA or development capacity while the actual constraint is test reliability.

    Environment Delays Matter Too

    Developers cannot deliver effectively if they regularly wait for:

    • Development environments
    • Test data
    • Cloud resources
    • Access permissions
    • Staging availability

    These delays may be less visible than a code-review queue, but they still reduce software delivery speed.

    A useful bottleneck assessment should therefore include the technical systems surrounding development, not only the engineers themselves.

    Separate Local Productivity From System Throughput

    One of the hardest engineering bottlenecks to diagnose appears when individual developers seem productive but delivery remains slow.

    For example:

    A developer may:

    • Complete several tickets
    • Write code quickly
    • Submit multiple pull requests

    while those changes wait days for review, QA, or deployment.

    From the individual’s perspective, productivity looks high.

    From the customer’s perspective, nothing has shipped.

    That is why optimizing local productivity can sometimes make system bottlenecks worse.

    If developers produce work faster than downstream stages can process it, unfinished work accumulates.

    The result is more:

    • Queues
    • Context switching
    • Merge conflicts
    • Coordination
    • Work in progress

    Improving software delivery requires looking at the entire workflow.

    Engineering Bottleneck or Capacity Problem?

    The distinction becomes easier when common symptoms are compared directly.

    What You ObservePossible Engineering BottleneckPossible Capacity Problem
    Pull requests wait for daysReview ownership or approval processToo few qualified reviewers
    Roadmap keeps slippingToo many priorities or delivery frictionSustained demand exceeds available team capacity
    QA queue growsLate testing or unstable automationToo little QA capacity
    Senior engineers are overloadedKnowledge and approval concentrated in a few peopleGenuine shortage of senior expertise
    Production support consumes the weekRecurring toil or weak reliabilityOperational demand genuinely requires more people
    Releases are slowCI/CD, approvals, or environment problemsToo little release/DevOps capacity
    Developers are constantly switching workPoor prioritizationMore prioritized work than the team can sustainably handle

    The same symptom can point to different causes.

    That is why hiring should follow diagnosis rather than precede it.

    How to Run a Simple Engineering Bottleneck Assessment

    A bottleneck assessment does not need to become a large transformation project.

    Start with a representative piece of work and follow it through the delivery process.

    Step 1: Map the Workflow

    Write down the major stages from request to production.

    For example:

    Idea
      ↓
    Requirements
      ↓
    Development
      ↓
    Code Review
      ↓
    QA
      ↓
    Approval
      ↓
    Deployment
      ↓
    Verification

    Adapt the workflow to your actual organization.

    The objective is to make waiting visible.

    Step 2: Identify Where Work Accumulates

    Ask:

    • Where are the largest queues?
    • Which tasks wait the longest?
    • Which stages regularly send work backward?
    • Which people or skills are shared across several teams?
    • Which manual steps happen repeatedly?

    Do not assume the slowest-looking team is automatically the constraint.

    Look at where unfinished work accumulates.

    Step 3: Separate Work Time From Wait Time

    For a few representative changes, compare:

    • Time actively being worked
    • Time waiting for the next stage

    This often reveals problems that ticket completion metrics hide.

    A task might require eight hours of engineering work but spend five days moving through the delivery system.

    Improving those eight hours will not solve most of the delay.

    Step 4: Identify the Constraint Type

    Classify the bottleneck.

    Is it primarily:

    • Demand
    • Process
    • Approval
    • Skill
    • Automation
    • Infrastructure
    • Operational toil
    • Actual headcount

    This matters because each constraint has a different solution.

    Step 5: Test One Improvement

    Do not immediately redesign the entire engineering organization.

    Change the constraint first.

    Examples:

    • Add automated review checks.
    • Train another reviewer.
    • Reduce active initiatives.
    • Automate one recurring operational task.
    • Improve flaky tests.
    • Clarify ownership.
    • Remove an unnecessary approval.

    Then observe whether overall delivery improves.

    If the queue simply moves to another stage, you have identified the next constraint.

    Step 6: Reassess Capacity

    After obvious bottlenecks are reduced, compare prioritized demand with sustainable engineering capacity again.

    This is where the decision becomes clearer.

    If important work still consistently exceeds what the team can deliver, the case for adding capacity becomes much stronger.

    When Hiring More Developers Actually Helps

    Hiring is the right response when the constraint is genuinely available engineering capacity.

    That may be the case when:

    • Prioritized demand consistently exceeds sustainable capacity.
    • Workflows are reasonably efficient.
    • Major queues are not primarily caused by process problems.
    • The team has already reduced avoidable toil.
    • Required work cannot simply be automated.
    • Important skills remain overloaded.
    • The demand is expected to continue.

    At that point, additional developers can increase throughput because the system has room to absorb their work.

    Hire for the Constraint, Not the Average Team Profile

    If the bottleneck is backend architecture, hire or add backend expertise.

    If it is DevOps, adding general application developers may not help.

    If QA automation is the constraint, target that capability.

    The goal is not to increase headcount as evenly as possible.

    It is to add capacity where it changes the delivery system.

    If the team has confirmed a real gap, comparing staff augmentation vs direct hiring can help determine whether the organization needs flexible engineering capacity or long-term ownership.

    Do Not Expect Instant Productivity From New Hires

    Additional developers also create short-term load.

    Existing engineers may need to spend time on:

    • Interviews
    • Onboarding
    • Documentation
    • Pairing
    • Code reviews
    • Knowledge transfer

    That means hiring can temporarily increase pressure on the same specialists who are already constrained.

    Plan for that cost.

    A team should not expect a new hire to create full additional capacity immediately.

    Measure Whether the Bottleneck Actually Improves

    After changing the process or adding capacity, return to the original queue.

    Ask:

    • Did waiting time decrease?
    • Is more work reaching production?
    • Are specialists less overloaded?
    • Is rework lower?
    • Are fewer tasks blocked?
    • Is delivery more predictable?

    The objective is not simply to show that the team became larger.

    It is to show that the delivery constraint improved.

    The Executive Takeaway

    Engineering bottlenecks are often mistaken for headcount problems because both produce the same visible result: work moves more slowly than the business expects.

    But the solution depends on what is actually limiting delivery.

    Before hiring more developers:

    • Map how work moves.
    • Find where it waits.
    • Measure rework.
    • Identify operational toil.
    • Look for concentrated skills.
    • Examine CI/CD and development infrastructure.
    • Reduce unnecessary work in progress.

    Then reassess demand.

    If the organization has improved the system and prioritized work still exceeds sustainable capacity, adding engineers becomes a much more defensible decision.

    Scaling an engineering team works best when new capacity is added to a system that can use it.

    If your team has identified a real delivery constraint and needs help adding the right technical capacity, start a conversation with TechAID.
    Related Posts