Software Project Rescue: Decide What Is Worth Saving

Software Project Rescue: Decide What Is Worth Saving

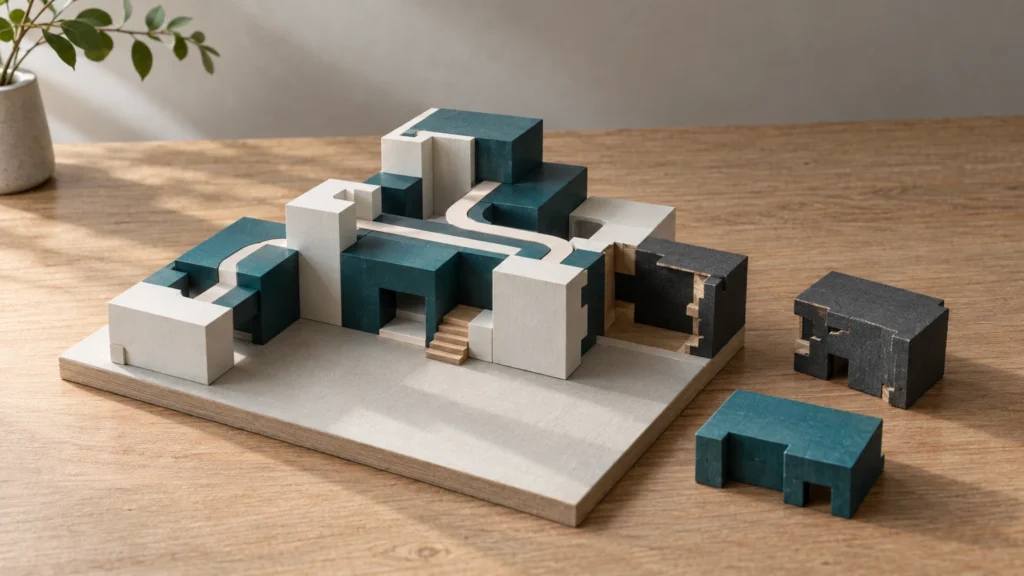
Modular model illustrating software project rescue, with a working core retained and a damaged section removed for evaluation.
A troubled project does not automatically need a rewrite or a bigger team. Use a decision-first recovery framework to compare remaining costs, commission a bounded assessment, and fund outcomes your team can verify.
Share the Post:

The launch date has moved twice. The team says the product is nearly finished, but nobody can demonstrate the complete customer workflow. Your current supplier wants another extension; a replacement supplier recommends starting over. Both proposals require more money before you know what you would actually be buying.

Software project rescue should resolve that uncertainty before it expands the delivery commitment. For a CTO, founder, or product leader, the first question is not who can write code faster. It is which remaining outcome is worth funding, what evidence makes it achievable, and who will be accountable for delivering it.

A recovery effort can preserve useful work. It can also reveal that a smaller release, selective replacement, or orderly shutdown is the better choice. The following decision framework helps you commission an assessment, compare those paths, and fund execution in increments without turning every difficult project into a rewrite.

Start software project rescue with a funding decision

Software project rescue is a bounded intervention to establish the condition of a troubled software initiative, decide whether and how to continue it, and restore delivery against explicit outcomes. It is not simply a change of supplier, a larger team, or a new delivery date.

Separate the immediate operational problem from the investment decision. If customers cannot transact or sensitive information may be exposed, activate the appropriate incident process. Stabilizing a live service does not automatically justify finishing every feature in the original roadmap.

Then name the decision the assessment must enable. For example: “Should we fund a limited customer onboarding release using the existing platform, or stop this implementation and evaluate another approach?” That question is more useful than “Please audit our code.” It tells reviewers which product flows, constraints, and uncertainties matter.

GAO’s Agile Assessment Guide describes practices for evaluating adoption, execution, and program monitoring. Although written primarily for federal oversight, its emphasis on evaluating delivery practices offers a useful discipline here: inspect how the work produces usable outcomes, not just how convincingly the team reports progress.

For software project rescue, appoint a sponsor who can change scope, authorize spending, and stop work. A recovery lead cannot solve conflicting executive commitments if nobody has authority to choose between them.

Reconstruct what is true before choosing a solution

An assessment should distinguish observed facts, reasonable interpretations, and unresolved questions. A screenshot is evidence that one screen rendered. It is not evidence that the application can be deployed reproducibly, handle failed transactions, or support a real customer.

Inspect a complete business journey

Choose one representative journey that carries meaningful business value: a customer signs up, receives the right permissions, completes an action, and sees the resulting record. Include failure and recovery behavior, not only the successful demonstration.

Ask the current team to run that journey in a controlled environment using the code and deployment process it expects to deliver. Record the version, environment, test data, and observed failures. Avoid a surprise examination: explain the objective, give people time to assemble the evidence, and keep blame out of the session.

For each part of the journey, classify the evidence as demonstrated, partially demonstrated, or not demonstrated. Do not convert those labels into a percentage complete. One missing authorization rule may matter more than twenty completed screens.

The output of this part of software project rescue is a usable inventory: capabilities that work, capabilities that need repair, and capabilities whose feasibility remains unproven. Keep the unknowns visible rather than quietly estimating them as ordinary development tasks.

Check the conditions needed to continue

  • Access and continuity: authorized access to repositories, build configuration, deployment environments, issue history, and essential third-party accounts.
  • Delivery evidence: the last reproducible build, recent test results, release history, unresolved defects, and known manual deployment steps.
  • Product decisions: the smallest valuable outcome, acceptance examples, non-negotiable constraints, and the person authorized to approve trade-offs.
  • External dependencies: integration owners, test environments, approval queues, data availability, and dates confirmed by the teams controlling them.

Use the least access required for assessment; do not casually distribute production credentials or customer data to prospective suppliers. NIST’s Secure Software Development Framework provides a common vocabulary for purchasers and suppliers to discuss secure development practices. Use that vocabulary to make security expectations explicit, rather than treating urgency as permission to bypass them.

A missing artifact is not automatically proof of poor engineering. Sometimes it reflects a handover problem, an undocumented process, or an inaccessible account. Record the consequence: can the next team reproduce the build without the original developer, and what would be needed to make that possible?

Also test the diagnosis. If work waits days for product decisions, another developer will not remove that queue. TechAID’s guide to identifying engineering bottlenecks helps distinguish a capacity shortage from blocked flow. The rescue decision goes further: it asks whether the remaining investment still makes sense.

Choose among four software project recovery paths

The assessment should compare credible alternatives, not assemble arguments for the option the reviewer prefers to sell. A software project rescue recommendation is stronger when it explains what would make its preferred path wrong.

Repair the existing implementation

Choose repair when the core business journey and architecture remain suitable, and the main problems can be bounded: defects, incomplete integration, unreliable delivery, or a specific capability gap. Ask for a small change that demonstrates the team can modify and verify the system without creating disproportionate new failures.

Repair does not mean preserving every technical choice. It means the usable parts justify the remaining effort. Require evidence that the proposed fixes address the causes of recurring failure, not just the latest symptoms.

Reduce the release to a smaller outcome

Choose a reduced release when the product still solves a worthwhile problem but the original scope exceeds the available time, budget, or organizational capacity. Define a complete, supportable journey for a narrower population or use case.

For example, defer a secondary reporting dashboard while preserving permissions, transaction integrity, and support visibility. Do not label essential security or operational controls “phase two.” A smaller product can be useful; an incomplete control environment is a different risk.

Replace a bounded component or implementation

Choose replacement when assessment evidence shows that a critical part cannot meet essential needs at an acceptable remaining cost or risk. Compare selective replacement with a full rebuild before discarding functioning components.

A replacement proposal must account for integration, transition, coexistence, and retiring the old path. Ask what the replacement removes and what new uncertainty it creates. A clean repository is not a business outcome, and a successful prototype is not proof of production readiness.

Pause or stop the initiative

Choose a pause when a specific external dependency or unresolved business decision prevents responsible continuation. State the trigger for restarting and the cost of keeping the option available. A pause without an owner or review date can become indefinite spending.

Stop when the remaining outcome no longer justifies the effort or cannot meet a hard constraint. The UK Government Service Manual explicitly recognizes stopping after discovery as a valid result when evidence does not support proceeding. Government process rules do not govern every commercial business; the useful principle is to let evidence determine whether work continues.

Include orderly closure: preserve records, identify continuing customer obligations, transfer operational responsibility, and document what can be reused. Software project rescue can succeed by preventing another unjustified commitment.

Build the next-budget case, not a defense of past spending

Compare the money and effort still required from today. Previous spending explains how the organization arrived here, but it does not by itself establish that continuing is worthwhile. Likewise, a low replacement quote is not persuasive if it excludes transition and internal effort.

For each viable path, estimate assessment, implementation, verification, internal participation, transition, and ongoing support. Show ranges and assumptions. Identify which costs are common to all paths, which are incremental, and which depend on an unresolved condition.

GAO’s Schedule Assessment Guide explains why credible cost estimates must account for schedule slippage and its effects. In a recovery proposal, that means connecting the forecast to dependencies and available people rather than choosing a date first and forcing the work to fit.

A fictional comparison

Consider a hypothetical customer portal. These figures illustrate the calculation; they are not market rates, TechAID pricing, or a forecast.

  • Repair: $90,000 in external delivery fees, $25,000 in internal effort, and $15,000 for transition and support preparation: $130,000 remaining.
  • Reduced release: $60,000 in external fees, $20,000 in internal effort, and $10,000 for transition and support preparation: $90,000 remaining, with a smaller outcome.
  • Replacement: $120,000 in external fees, $30,000 in internal effort, and $25,000 for transition and support preparation: $175,000 remaining.

Suppose all three paths also require the same $12,000 assessment. Add it consistently to each total, or show it separately as a common decision cost. Do not count it twice in one option or omit it from the approval request.

The reduced release is cheapest, but that alone does not make it best. If its narrower journey cannot serve the intended customers, it may have little value. Repair may be preferable if the assessment demonstrates that the key technical assumptions hold. Replacement may be justified if the existing implementation cannot satisfy an essential requirement.

For software project rescue, make the sensitivity visible. What happens if the integration team is unavailable for a month? What if the critical component needs replacement after all? Use named scenarios rather than an invented confidence percentage. Where a risk cannot yet be estimated responsibly, fund a test of that assumption before the larger commitment.

Do not confuse a spending ceiling with a forecast. The ceiling is what the sponsor is willing to authorize. The forecast is what the evidence suggests the work will require. A gap between them calls for a different scope, approach, or decision—not a more optimistic spreadsheet.

Choose who manages the recovery work

The delivery model follows the diagnosis. Software project rescue is not a reason to default to outsourcing, and geographic proximity does not remove the need for a clear client decision-maker.

Use nearshore staff augmentation when your leadership can manage the recovery and the main need is embedded engineering, QA, or DevOps capacity. Your team retains day-to-day priorities and delivery management. This can fit a bounded validation or remediation backlog under an effective internal lead.

Use direct hiring when the missing capability must remain a permanent part of the organization. A long-term technical owner may be important, but recruitment and onboarding should not be treated as an immediate rescue schedule. Separate the urgent recovery decision from the permanent organization you want afterward.

Use project outsourcing when you need a partner to manage execution of a defined recovery workstream or outcome. The client still owns business priorities, access decisions, and final acceptance. Before asking for a delivery commitment, establish a scope that the partner can control and dependencies it cannot.

A staged arrangement can be appropriate: assess first, agree a bounded outcome, and then authorize managed execution. Confirm commercial terms and responsibilities directly. Do not assume that an assessment is free, that the same provider must implement its recommendation, or that adding a project manager transfers every business risk.

Commission an assessment with a clear stopping point

An open-ended software project audit can produce a long defect list without helping anyone decide. Commission a decision package instead. Agree its scope, access needs, deliverables, review date, and maximum authorized effort before work starts.

Keep the request proportional. A product with several services and external integrations may need a different assessment than a small internal application. Avoid promising a universal five-day turnaround before the reviewer knows what can be inspected.

The decision package for software project rescue should contain:

  • An evidence-based current-state summary, with demonstrated capabilities separated from assumptions and unknowns.
  • A comparison of feasible paths, including reduced scope and stopping when those are credible alternatives.
  • A proposed first delivery outcome, acceptance evidence, exclusions, and dependencies requiring client action.
  • A remaining-cost and schedule range with assumptions, uncertainty drivers, and the next decision that could change it.
  • A responsibility and transition plan covering day-to-day execution, business decisions, verification, support, and handoff.

Protect the team’s ability to keep essential work moving. Request existing artifacts before demanding new presentations. Use short, focused sessions with product, engineering, QA, operations, and the current supplier where applicable. Give people a route to correct factual errors in the assessment.

If the assessment provider also wants the implementation, ask it to distinguish findings from its commercial recommendation. Have an internal technical reviewer challenge the assumptions. This is especially important when a recommendation would replace most of the system or create a long dependency on that provider.

Accept the assessment when it answers the agreed decision question—not when every defect has been catalogued. If essential access is unavailable, the valid output may be a constrained assessment explaining what cannot yet be concluded.

Fund proof milestones in your project recovery plan

Once you choose a path, turn the software project rescue plan into increments that retire specific uncertainty. “Finish the backend” is too broad to demonstrate a useful change in risk. “Complete one authorized customer workflow, including failure handling, with repeatable deployment and agreed tests” is inspectable.

A proof milestone needs an outcome, a reviewer, an environment, and an acceptance method. For a portal recovery, the first milestone might demonstrate that a newly registered customer can access only its own records, submit a valid request, recover from a rejected request, and generate an operationally visible result.

Set a decision at the end of that milestone: continue within the authorized scope, change the approach, or stop pending a named resolution. If the work fails acceptance, record the reason and its effect on the remaining forecast. Avoid silently redefining success to preserve the appearance of progress.

The weekly recovery review should make a few things easy to see:

  • Accepted outcomes and the evidence behind them, not merely tasks marked complete.
  • Unresolved blockers, their owners, their age, and the decisions required to remove them.
  • Newly discovered work and its effect on scope, cost, and the next milestone.
  • Quality and operational risks that remain, including who has authority to accept them.

Keep the original recovery baseline visible when you revise it. Otherwise, a continually moving date can make an unsuccessful plan look permanently on track. Explain changes in plain terms: a dependency arrived late, a technical assumption failed, or the sponsor approved a different outcome.

Plan handoff during execution. The receiving team should practice building, deploying, diagnosing a failure, and performing the routine operating tasks it will inherit. Completed documentation is helpful, but demonstrated ability is the stronger acceptance signal.

Evaluate a recovery partner by its willingness to bound the work

Ask prospective partners what they need to see before they estimate, which assumptions could invalidate their proposal, and how they would recommend stopping. Those answers reveal more than a confident launch promise based on a short sales call.

Request an example of the kind of assessment artifact and acceptance record they produce, with client information removed. Ask who will actually lead the work, how specialist QA and operational expertise will participate, and how findings will be reviewed with your team.

Be cautious about a fixed-price full recovery quote before the supplier has inspected the system, or an automatic rewrite recommendation that ignores transition. Equally, an indefinite time-and-materials engagement without review points leaves the sponsor unable to make informed continuation decisions.

A useful software project rescue proposal connects the work the partner controls to an outcome you can verify. It also makes client obligations explicit. Nearshore collaboration can support timely conversations, but it cannot compensate for missing access, unavailable approvers, or contradictory priorities.

Bring a decision-ready problem to TechAID

TechAID’s project outsourcing offering includes Project Recovery & Audit, project management, custom software development, QA, and DevOps. That makes a defined recovery workstream a natural conversation—not a promise that every troubled initiative should continue.

Bring the outcome you still need, the last working demonstration, the main unresolved dependencies, and the decision you need to make. Ask TechAID to discuss whether a bounded assessment and managed recovery engagement fit the situation.

The useful first commitment is clarity about what is worth saving. Execution should follow the evidence.
Key Takeaways
  • Frame software project rescue around a specific funding decision, with a sponsor empowered to change scope or stop work.

  • Assess a representative end-to-end customer journey and record demonstrated capabilities, failures, and unresolved unknowns without treating them as a completion percentage.

  • Compare repair, reduced release, selective replacement, and pause or stop using remaining costs, risks, and business value.

  • Fund execution in verifiable increments, with explicit acceptance outcomes and clear conditions for continuing or stopping.

  • The launch date has moved twice. The team says the product is nearly finished, but nobody can demonstrate the complete customer workflow. Your current supplier wants another extension; a replacement supplier recommends starting over. Both proposals require more money before you know what you would actually be buying.

    Software project rescue should resolve that uncertainty before it expands the delivery commitment. For a CTO, founder, or product leader, the first question is not who can write code faster. It is which remaining outcome is worth funding, what evidence makes it achievable, and who will be accountable for delivering it.

    A recovery effort can preserve useful work. It can also reveal that a smaller release, selective replacement, or orderly shutdown is the better choice. The following decision framework helps you commission an assessment, compare those paths, and fund execution in increments without turning every difficult project into a rewrite.

    Start software project rescue with a funding decision

    Software project rescue is a bounded intervention to establish the condition of a troubled software initiative, decide whether and how to continue it, and restore delivery against explicit outcomes. It is not simply a change of supplier, a larger team, or a new delivery date.

    Separate the immediate operational problem from the investment decision. If customers cannot transact or sensitive information may be exposed, activate the appropriate incident process. Stabilizing a live service does not automatically justify finishing every feature in the original roadmap.

    Then name the decision the assessment must enable. For example: “Should we fund a limited customer onboarding release using the existing platform, or stop this implementation and evaluate another approach?” That question is more useful than “Please audit our code.” It tells reviewers which product flows, constraints, and uncertainties matter.

    GAO’s Agile Assessment Guide describes practices for evaluating adoption, execution, and program monitoring. Although written primarily for federal oversight, its emphasis on evaluating delivery practices offers a useful discipline here: inspect how the work produces usable outcomes, not just how convincingly the team reports progress.

    For software project rescue, appoint a sponsor who can change scope, authorize spending, and stop work. A recovery lead cannot solve conflicting executive commitments if nobody has authority to choose between them.

    Reconstruct what is true before choosing a solution

    An assessment should distinguish observed facts, reasonable interpretations, and unresolved questions. A screenshot is evidence that one screen rendered. It is not evidence that the application can be deployed reproducibly, handle failed transactions, or support a real customer.

    Inspect a complete business journey

    Choose one representative journey that carries meaningful business value: a customer signs up, receives the right permissions, completes an action, and sees the resulting record. Include failure and recovery behavior, not only the successful demonstration.

    Ask the current team to run that journey in a controlled environment using the code and deployment process it expects to deliver. Record the version, environment, test data, and observed failures. Avoid a surprise examination: explain the objective, give people time to assemble the evidence, and keep blame out of the session.

    For each part of the journey, classify the evidence as demonstrated, partially demonstrated, or not demonstrated. Do not convert those labels into a percentage complete. One missing authorization rule may matter more than twenty completed screens.

    The output of this part of software project rescue is a usable inventory: capabilities that work, capabilities that need repair, and capabilities whose feasibility remains unproven. Keep the unknowns visible rather than quietly estimating them as ordinary development tasks.

    Check the conditions needed to continue

    • Access and continuity: authorized access to repositories, build configuration, deployment environments, issue history, and essential third-party accounts.
    • Delivery evidence: the last reproducible build, recent test results, release history, unresolved defects, and known manual deployment steps.
    • Product decisions: the smallest valuable outcome, acceptance examples, non-negotiable constraints, and the person authorized to approve trade-offs.
    • External dependencies: integration owners, test environments, approval queues, data availability, and dates confirmed by the teams controlling them.

    Use the least access required for assessment; do not casually distribute production credentials or customer data to prospective suppliers. NIST’s Secure Software Development Framework provides a common vocabulary for purchasers and suppliers to discuss secure development practices. Use that vocabulary to make security expectations explicit, rather than treating urgency as permission to bypass them.

    A missing artifact is not automatically proof of poor engineering. Sometimes it reflects a handover problem, an undocumented process, or an inaccessible account. Record the consequence: can the next team reproduce the build without the original developer, and what would be needed to make that possible?

    Also test the diagnosis. If work waits days for product decisions, another developer will not remove that queue. TechAID’s guide to identifying engineering bottlenecks helps distinguish a capacity shortage from blocked flow. The rescue decision goes further: it asks whether the remaining investment still makes sense.

    Choose among four software project recovery paths

    The assessment should compare credible alternatives, not assemble arguments for the option the reviewer prefers to sell. A software project rescue recommendation is stronger when it explains what would make its preferred path wrong.

    Repair the existing implementation

    Choose repair when the core business journey and architecture remain suitable, and the main problems can be bounded: defects, incomplete integration, unreliable delivery, or a specific capability gap. Ask for a small change that demonstrates the team can modify and verify the system without creating disproportionate new failures.

    Repair does not mean preserving every technical choice. It means the usable parts justify the remaining effort. Require evidence that the proposed fixes address the causes of recurring failure, not just the latest symptoms.

    Reduce the release to a smaller outcome

    Choose a reduced release when the product still solves a worthwhile problem but the original scope exceeds the available time, budget, or organizational capacity. Define a complete, supportable journey for a narrower population or use case.

    For example, defer a secondary reporting dashboard while preserving permissions, transaction integrity, and support visibility. Do not label essential security or operational controls “phase two.” A smaller product can be useful; an incomplete control environment is a different risk.

    Replace a bounded component or implementation

    Choose replacement when assessment evidence shows that a critical part cannot meet essential needs at an acceptable remaining cost or risk. Compare selective replacement with a full rebuild before discarding functioning components.

    A replacement proposal must account for integration, transition, coexistence, and retiring the old path. Ask what the replacement removes and what new uncertainty it creates. A clean repository is not a business outcome, and a successful prototype is not proof of production readiness.

    Pause or stop the initiative

    Choose a pause when a specific external dependency or unresolved business decision prevents responsible continuation. State the trigger for restarting and the cost of keeping the option available. A pause without an owner or review date can become indefinite spending.

    Stop when the remaining outcome no longer justifies the effort or cannot meet a hard constraint. The UK Government Service Manual explicitly recognizes stopping after discovery as a valid result when evidence does not support proceeding. Government process rules do not govern every commercial business; the useful principle is to let evidence determine whether work continues.

    Include orderly closure: preserve records, identify continuing customer obligations, transfer operational responsibility, and document what can be reused. Software project rescue can succeed by preventing another unjustified commitment.

    Build the next-budget case, not a defense of past spending

    Compare the money and effort still required from today. Previous spending explains how the organization arrived here, but it does not by itself establish that continuing is worthwhile. Likewise, a low replacement quote is not persuasive if it excludes transition and internal effort.

    For each viable path, estimate assessment, implementation, verification, internal participation, transition, and ongoing support. Show ranges and assumptions. Identify which costs are common to all paths, which are incremental, and which depend on an unresolved condition.

    GAO’s Schedule Assessment Guide explains why credible cost estimates must account for schedule slippage and its effects. In a recovery proposal, that means connecting the forecast to dependencies and available people rather than choosing a date first and forcing the work to fit.

    A fictional comparison

    Consider a hypothetical customer portal. These figures illustrate the calculation; they are not market rates, TechAID pricing, or a forecast.

    • Repair: $90,000 in external delivery fees, $25,000 in internal effort, and $15,000 for transition and support preparation: $130,000 remaining.
    • Reduced release: $60,000 in external fees, $20,000 in internal effort, and $10,000 for transition and support preparation: $90,000 remaining, with a smaller outcome.
    • Replacement: $120,000 in external fees, $30,000 in internal effort, and $25,000 for transition and support preparation: $175,000 remaining.

    Suppose all three paths also require the same $12,000 assessment. Add it consistently to each total, or show it separately as a common decision cost. Do not count it twice in one option or omit it from the approval request.

    The reduced release is cheapest, but that alone does not make it best. If its narrower journey cannot serve the intended customers, it may have little value. Repair may be preferable if the assessment demonstrates that the key technical assumptions hold. Replacement may be justified if the existing implementation cannot satisfy an essential requirement.

    For software project rescue, make the sensitivity visible. What happens if the integration team is unavailable for a month? What if the critical component needs replacement after all? Use named scenarios rather than an invented confidence percentage. Where a risk cannot yet be estimated responsibly, fund a test of that assumption before the larger commitment.

    Do not confuse a spending ceiling with a forecast. The ceiling is what the sponsor is willing to authorize. The forecast is what the evidence suggests the work will require. A gap between them calls for a different scope, approach, or decision—not a more optimistic spreadsheet.

    Choose who manages the recovery work

    The delivery model follows the diagnosis. Software project rescue is not a reason to default to outsourcing, and geographic proximity does not remove the need for a clear client decision-maker.

    Use nearshore staff augmentation when your leadership can manage the recovery and the main need is embedded engineering, QA, or DevOps capacity. Your team retains day-to-day priorities and delivery management. This can fit a bounded validation or remediation backlog under an effective internal lead.

    Use direct hiring when the missing capability must remain a permanent part of the organization. A long-term technical owner may be important, but recruitment and onboarding should not be treated as an immediate rescue schedule. Separate the urgent recovery decision from the permanent organization you want afterward.

    Use project outsourcing when you need a partner to manage execution of a defined recovery workstream or outcome. The client still owns business priorities, access decisions, and final acceptance. Before asking for a delivery commitment, establish a scope that the partner can control and dependencies it cannot.

    A staged arrangement can be appropriate: assess first, agree a bounded outcome, and then authorize managed execution. Confirm commercial terms and responsibilities directly. Do not assume that an assessment is free, that the same provider must implement its recommendation, or that adding a project manager transfers every business risk.

    Commission an assessment with a clear stopping point

    An open-ended software project audit can produce a long defect list without helping anyone decide. Commission a decision package instead. Agree its scope, access needs, deliverables, review date, and maximum authorized effort before work starts.

    Keep the request proportional. A product with several services and external integrations may need a different assessment than a small internal application. Avoid promising a universal five-day turnaround before the reviewer knows what can be inspected.

    The decision package for software project rescue should contain:

    • An evidence-based current-state summary, with demonstrated capabilities separated from assumptions and unknowns.
    • A comparison of feasible paths, including reduced scope and stopping when those are credible alternatives.
    • A proposed first delivery outcome, acceptance evidence, exclusions, and dependencies requiring client action.
    • A remaining-cost and schedule range with assumptions, uncertainty drivers, and the next decision that could change it.
    • A responsibility and transition plan covering day-to-day execution, business decisions, verification, support, and handoff.

    Protect the team’s ability to keep essential work moving. Request existing artifacts before demanding new presentations. Use short, focused sessions with product, engineering, QA, operations, and the current supplier where applicable. Give people a route to correct factual errors in the assessment.

    If the assessment provider also wants the implementation, ask it to distinguish findings from its commercial recommendation. Have an internal technical reviewer challenge the assumptions. This is especially important when a recommendation would replace most of the system or create a long dependency on that provider.

    Accept the assessment when it answers the agreed decision question—not when every defect has been catalogued. If essential access is unavailable, the valid output may be a constrained assessment explaining what cannot yet be concluded.

    Fund proof milestones in your project recovery plan

    Once you choose a path, turn the software project rescue plan into increments that retire specific uncertainty. “Finish the backend” is too broad to demonstrate a useful change in risk. “Complete one authorized customer workflow, including failure handling, with repeatable deployment and agreed tests” is inspectable.

    A proof milestone needs an outcome, a reviewer, an environment, and an acceptance method. For a portal recovery, the first milestone might demonstrate that a newly registered customer can access only its own records, submit a valid request, recover from a rejected request, and generate an operationally visible result.

    Set a decision at the end of that milestone: continue within the authorized scope, change the approach, or stop pending a named resolution. If the work fails acceptance, record the reason and its effect on the remaining forecast. Avoid silently redefining success to preserve the appearance of progress.

    The weekly recovery review should make a few things easy to see:

    • Accepted outcomes and the evidence behind them, not merely tasks marked complete.
    • Unresolved blockers, their owners, their age, and the decisions required to remove them.
    • Newly discovered work and its effect on scope, cost, and the next milestone.
    • Quality and operational risks that remain, including who has authority to accept them.

    Keep the original recovery baseline visible when you revise it. Otherwise, a continually moving date can make an unsuccessful plan look permanently on track. Explain changes in plain terms: a dependency arrived late, a technical assumption failed, or the sponsor approved a different outcome.

    Plan handoff during execution. The receiving team should practice building, deploying, diagnosing a failure, and performing the routine operating tasks it will inherit. Completed documentation is helpful, but demonstrated ability is the stronger acceptance signal.

    Evaluate a recovery partner by its willingness to bound the work

    Ask prospective partners what they need to see before they estimate, which assumptions could invalidate their proposal, and how they would recommend stopping. Those answers reveal more than a confident launch promise based on a short sales call.

    Request an example of the kind of assessment artifact and acceptance record they produce, with client information removed. Ask who will actually lead the work, how specialist QA and operational expertise will participate, and how findings will be reviewed with your team.

    Be cautious about a fixed-price full recovery quote before the supplier has inspected the system, or an automatic rewrite recommendation that ignores transition. Equally, an indefinite time-and-materials engagement without review points leaves the sponsor unable to make informed continuation decisions.

    A useful software project rescue proposal connects the work the partner controls to an outcome you can verify. It also makes client obligations explicit. Nearshore collaboration can support timely conversations, but it cannot compensate for missing access, unavailable approvers, or contradictory priorities.

    Bring a decision-ready problem to TechAID

    TechAID’s project outsourcing offering includes Project Recovery & Audit, project management, custom software development, QA, and DevOps. That makes a defined recovery workstream a natural conversation—not a promise that every troubled initiative should continue.

    Bring the outcome you still need, the last working demonstration, the main unresolved dependencies, and the decision you need to make. Ask TechAID to discuss whether a bounded assessment and managed recovery engagement fit the situation.

    The useful first commitment is clarity about what is worth saving. Execution should follow the evidence.
    Related Posts