A Test Data Strategy for Repeatable, Isolated Test Scenarios

A Test Data Strategy for Repeatable, Isolated Test Scenarios

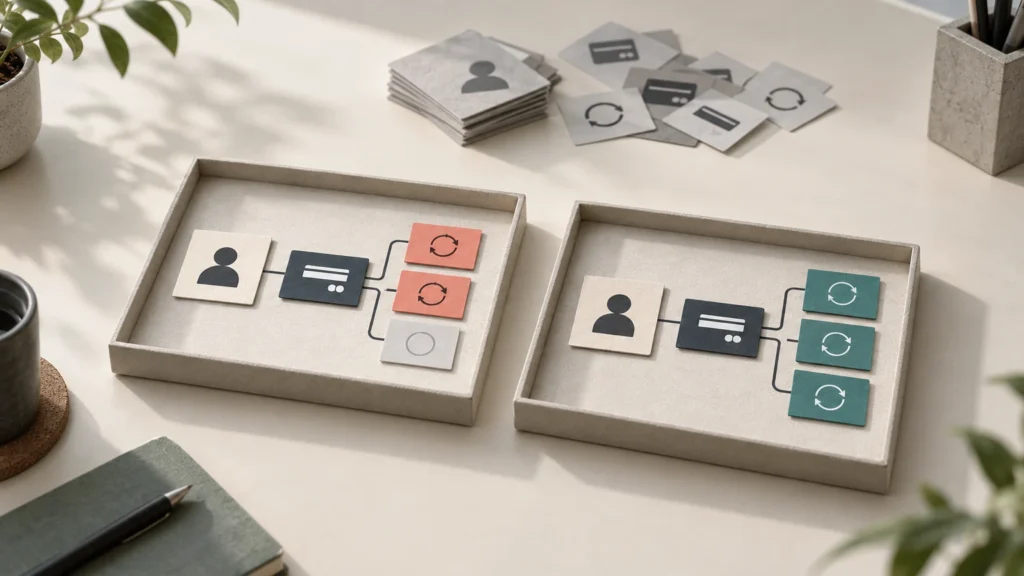
Test data strategy illustration showing two isolated refund scenarios with linked customer, payment, and refund records.
Turn fragile shared accounts and ad hoc staging copies into repeatable test scenarios. Define the state each test needs, isolate mutations, verify readiness, and give provisioning and cleanup clear engineering ownership.
Share the Post:

A refund test passes on a developer’s laptop and fails in CI. The code has not changed. Another test has already refunded the shared order, the account’s eligibility window expired overnight, or the search index has not caught up with the database. The team reruns the job and loses another hour without learning whether the product is correct.

A useful test data strategy makes those prerequisites explicit and reproducible. It defines the business state each test needs, how that state is created, who may change it, and how it is retired. The goal is not a larger staging database. It is a dependable way to obtain the right scenario.

This guide gives QA leads, automation engineers, and engineering managers six rules for building that capability. It concentrates on application-level integration and end-to-end tests in controlled non-production environments. Performance datasets, migration rehearsals, and recovery drills have different fidelity requirements and need their own plans.

What a test data strategy should deliver

A test data strategy is the operating agreement for supplying, validating, isolating, and maintaining the data used by tests. Its practical output should be a small catalog of scenarios that engineers can request and reproduce, not just a document describing where database copies come from.

The problem is not hypothetical, although its size varies by organization. Perforce’s report published June 16, 2026 says 99% of respondents waited more than one business day for a fresh full production copy of test data. Its respondent snapshot identifies 518 enterprise leaders surveyed globally with a third-party research firm. This is vendor-sponsored enterprise evidence, not a benchmark for every product team—or proof that every test needs a production copy.

The narrower engineering question is often more actionable: what is the smallest trustworthy state needed to exercise this behavior? A full copy may contain millions of customers and still lack the precise expired entitlement or partially refunded order that the next release needs to handle.

Keep this work connected to the broader automation architecture. TechAID’s QA automation strategy guide covers test layers and pipeline decisions. The deeper task here is to turn one scenario’s prerequisites into a maintained interface that those tests can consume.

1. Specify the scenario before choosing its data source

Start with an assertion and work backward. “An authorized support user can refund the remaining refundable amount” requires more than a customer and an order. It needs the correct role, tenant, payment state, previous refund history, policy version, and time boundary. Decide which of those conditions the test is actually intended to examine.

For each important scenario, write a short contract with explicit prerequisites and observable outcomes. Keep business meaning separate from storage details so a schema change does not force every test author to rediscover the requirement.

  • Purpose: the behavior under test and the failure it should detect.
  • Required state: entities, relationships, permissions, amounts, and relevant timestamps.
  • Creation path: approved API, fixture, seed script, or controlled dataset.
  • Readiness: observable checks proving the prerequisites are available.
  • Ownership and lifetime: which run may mutate the records and when they expire.
  • Expected outcome: the result and side effects that must occur—or must not occur.

This contract is the center of the test data strategy. A request for “a premium customer” is ambiguous; a request for “a tenant-scoped premium customer whose renewal is tomorrow and whose payment method has expired” is specific enough to implement and review.

Do not let the setup perform the behavior being tested. If the test checks refund creation, the setup may create a captured payment and an earlier partial refund, but it must leave the final refund action to the test. Otherwise, a convenient fixture can accidentally remove the very integration path you wanted to verify.

2. Choose the source that preserves the required evidence

Use deliberately constructed data when the relevant business state can be represented faithfully. Small, named scenarios are easier to inspect than a large anonymous dataset. A factory that creates an account, subscription, and invoices together can make relationships explicit without requiring a copy of a real customer.

Use an approved, minimized production-derived dataset when a specific characteristic cannot yet be reproduced adequately—for example, a difficult legacy record shape. Document why it is necessary, who approves access, what transformations are required, and when the copy must be removed. Do not treat a renamed customer field as evidence that the entire dataset is safe.

Your test data strategy should distinguish data realism from system fidelity. Synthetic records can exercise the same database engine used in production. Conversely, realistic-looking records in a substitute database may miss behavioral differences. Microsoft’s EF Core testing guidance explains that a database test double can differ from the production provider, including string-comparison behavior.

“Production database system” means the database technology and relevant configuration, not permission to run destructive tests against the live customer database. Use an isolated test instance. Record important differences in versions, collation, extensions, configuration, or external dependencies so passing results are not interpreted beyond their actual scope.

Prefer application APIs for setup when they establish necessary business invariants. Direct database seeding can be useful for speed or otherwise unreachable states, but it may bypass validation, events, and derived records. Make that trade-off explicit. Neither route is universally correct, and the fastest insert method is not always the most faithful setup.

Evaluate a test data management tool against the contract, not a feature checklist. Can it supply the required linked entities, preserve the approved relationships after transformation, expose readiness, and retire only the intended resources? A tool can support the test data strategy, but a successful provisioning demonstration does not prove that the resulting scenario satisfies your application’s rules.

3. Preserve relationships, time, and deliberately invalid cases

A collection of realistic names and email addresses is not a business scenario. An order must belong to the right customer, its lines must reconcile with its totals, and its payment and refund records must agree with the state you are testing. Generate related entities as a unit and validate the relationships before the main assertion runs.

Define scenario builders around domain concepts, such as an active subscription with one overdue invoice. Keep defaults small and explicit. Allow a test to override the few properties that matter without copying an entire customer object into every test file. Review changes to shared defaults because they can silently change what many tests exercise.

Time belongs in the test data strategy too. A fixed expiry date eventually becomes stale; using the current time everywhere can make boundary failures hard to reproduce. Choose a controlled reference time where the application supports it, or calculate relative dates from one recorded reference. Ensure the services involved interpret the same time zone and boundary.

A seeded random generator can help reproduce generated values, but the seed alone is not a complete replay recipe. Record the generator version, scenario definition, application build, and relevant configuration. A changed generation sequence or library version can produce different values even when the seed is unchanged.

Keep negative scenarios intentional. If a test needs a customer without an entitlement, say that explicitly and verify the absence. Do not rely on an incomplete seed script accidentally omitting it. Equally, do not “repair” every invalid record during setup when the purpose of the test is to verify rejection or safe handling of that invalid state.

Avoid using the same calculation to generate both the input and the expected result. If a builder and assertion share a faulty refund-balance function, the test can agree with itself while the behavior is wrong. Include independently reviewed examples with known outcomes in the test data strategy, especially for money, permissions, and date boundaries.

4. Make test data isolation match the mutation boundary

Browser isolation does not automatically isolate server-side data. Two fresh browser sessions can still log in to the same account and update the same order. The test data strategy must identify the resources that can collide: tenants, users, inventory, queues, external sandbox accounts, and shared caches—not just browser cookies.

Assign mutable records to a unique run and scenario. A practical identifier combines a run identifier with the worker and test instance; include an attempt identifier when retries must start fresh. Worker numbers alone may repeat across separate CI jobs, and a per-worker account can still be unsuitable when tests mutate shared state within that worker.

Playwright’s parallelism documentation demonstrates creating database users per worker. That is a useful pattern when its sharing assumptions fit your tests. Decide separately whether each test also needs its own orders, permissions, or balances, and whether concurrent pipeline runs share the same backend.

Shared read-only reference data can be efficient when its immutability is enforced. Mutable scenarios need stronger separation: independently owned records, a dedicated tenant, or a separate database or environment. Choose the smallest boundary that actually prevents interference. More infrastructure is not automatically better if it makes setup too slow to use.

Transaction rollback can isolate some database tests, but it is not a universal cleanup mechanism. Microsoft’s database-testing guidance distinguishes ordinary write tests from tests whose application code manages transactions. External messages, object uploads, or calls to another service also require explicit handling; rolling back one database transaction does not reverse every side effect.

5. Make provisioning, readiness, and cleanup observable

Treat test data provisioning as a small workflow: validate the target, create the scenario, confirm readiness, return its identifiers, execute the test, and retire the resources. Each stage should have a clear result. A setup timeout must not be reported as a passing product test or hidden inside an unexplained retry.

Readiness should reflect what the test will use. A successful database insert does not prove that an asynchronous projection, search index, or downstream service can see the record. Poll a relevant observable condition with a bounded timeout. Keep the expected condition explicit rather than sleeping for an arbitrary interval and hoping processing has finished.

Fixtures can package this lifecycle. Playwright’s fixture documentation describes colocated setup and teardown, reuse, and composition. Use that structure to return a scenario object containing only the identifiers and helpers the test needs. Keep target validation and cleanup rules in the fixture implementation, where they can be reviewed consistently.

Plan for partial creation. If the account is created but the order fails, record the account identifier immediately so cleanup can still find it. Make retirement safe to repeat, handle already-absent resources, and distinguish a successful cleanup from an attempted cleanup. Never use a broad delete or table reset against a shared environment merely because it is convenient.

A robust test data strategy also handles crashed jobs. Use an approved expiry or lease mechanism and a separate cleanup process for abandoned test-owned resources. Check ownership, environment, and active leases before deletion. Preserve minimal, access-controlled diagnostic evidence when needed, without leaving sensitive datasets or credentials in general CI logs.

6. Version the contract and give maintenance an owner

Store scenario definitions and provisioning code with a reviewable version history. Record which application or schema versions they support. A schema migration, permission change, or new business rule should trigger a review of affected scenarios, not a scramble after the nightly suite stops working.

Test the setup itself. Confirm that a known scenario can be created, read back, used by an authorized test identity, and removed. Introduce controlled setup failures in a safe environment to verify that partial resources are tracked and retired. This checks the test infrastructure; it does not replace assertions about the product.

Assign responsibilities explicitly. The application team owns business invariants. QA owns scenario coverage and expected behavior. Platform or DevOps engineers own environment boundaries and supporting automation. Security and data owners approve sensitive-data use. One named maintainer should coordinate changes to the shared scenario interface.

Measure whether the test data strategy improves the work. Track request-to-ready time, setup failures separately from product failures, collisions between runs, and abandoned-resource cleanup. Compare like-for-like suites and concurrency levels. A lower failure count is not progress if the team simply stops exercising the difficult scenarios.

Keep the first implementation small. One critical flow with a reliable lifecycle is more useful than an enterprise catalog full of unverified entries. Expand only after another engineer can request the scenario, understand its limitations, and diagnose a failure without relying on its original author.

Worked example: two refund tests share one order

Consider a hypothetical subscription platform. One API test checks a second partial refund; another checks rejection after the refundable balance reaches zero. Both currently use the same staging customer and captured payment. Each passes alone, but their results depend on execution order. This is an illustrative example, not a TechAID customer result.

The team’s test data strategy replaces the shared payment with two named scenarios. In the first, a payment of 100 units has a completed refund of 30, leaving 70 refundable. In the second, a payment of 100 has already been fully refunded. The amounts describe the test’s invented rules, not a payment provider’s universal behavior.

Define separate starting states and outcomes

For the partial-refund case, the contract requires an authorized support identity, the correct tenant, a captured payment, and the completed earlier refund. Readiness checks confirm both the payment service’s state and the application view used by the test. The action requests a refund of 20; the expected result is a remaining refundable amount of 50 and exactly one new refund record.

For the exhausted-balance case, the contract requires a different payment with no refundable amount. The action requests an additional refund; the expected result is the application’s documented rejection and no new refund side effect. It is not enough to check an error message if the backend still created a refund request.

Give every execution its own resource set

Each test receives a unique tenant-scoped customer and payment reference for its run. The provisioning helper returns those references instead of a hardcoded account name. Calls to the payment dependency use an explicitly configured sandbox or controlled substitute, and the report states which boundary was exercised.

A readiness timeout ends the attempt as a setup failure. If execution fails after resources exist, the record keeps the scenario version and identifiers needed for diagnosis. Cleanup retires only that run’s resources. Where a sandbox retains transaction history and cannot delete it, mark the resources unusable for future tests and apply the provider’s supported retention controls.

Finally, run the two scenarios concurrently, repeat them in reversed order, and start a second pipeline run against the same permitted environment. Look for identifier collisions, incorrect cleanup, and shared quotas. Passing these checks supports the chosen isolation design; it does not establish that every possible concurrency level is safe.

Turn the strategy into owned engineering work

Before buying a platform or adding more test authors, identify the missing capability. Your team may need domain-aware scenario builders, reliable provisioning, cross-service readiness checks, or cleanup automation. Those are different tasks from writing more assertions. Estimate the work and reserve capacity to maintain it as the product changes.

A test data strategy needs continuing client-side ownership of priorities, access, and business rules. TechAID’s nearshore staff augmentation model can add embedded QA or DevOps professionals under your management. Its published Verndale case describes QA leadership, tooling guidance, training, and automation adoption; it is evidence of that broader capability, not a claim of a specific test-data implementation.

Bring one blocked test scenario, its current setup process, and the maintenance work your team cannot absorb to a staffing conversation with TechAID. Ask which responsibilities an embedded specialist could own. Start with a repeatable scenario and an accountable maintainer before expanding the catalog.
Key Takeaways
  • Define each test scenario’s business prerequisites, setup path, readiness checks, ownership, and cleanup before selecting a data source.

  • Choose synthetic or approved production-derived data based on the evidence the test needs, and document fidelity limitations and privacy controls.

  • Build and validate related records as coherent scenarios, with controlled time, intentional invalid cases, and reproducible generation details.

  • Isolate mutable resources at the server-side boundary so parallel tests cannot affect one another.

  • Make provisioning, readiness verification, and cleanup explicit, observable responsibilities within the test data strategy.

  • A refund test passes on a developer’s laptop and fails in CI. The code has not changed. Another test has already refunded the shared order, the account’s eligibility window expired overnight, or the search index has not caught up with the database. The team reruns the job and loses another hour without learning whether the product is correct.

    A useful test data strategy makes those prerequisites explicit and reproducible. It defines the business state each test needs, how that state is created, who may change it, and how it is retired. The goal is not a larger staging database. It is a dependable way to obtain the right scenario.

    This guide gives QA leads, automation engineers, and engineering managers six rules for building that capability. It concentrates on application-level integration and end-to-end tests in controlled non-production environments. Performance datasets, migration rehearsals, and recovery drills have different fidelity requirements and need their own plans.

    What a test data strategy should deliver

    A test data strategy is the operating agreement for supplying, validating, isolating, and maintaining the data used by tests. Its practical output should be a small catalog of scenarios that engineers can request and reproduce, not just a document describing where database copies come from.

    The problem is not hypothetical, although its size varies by organization. Perforce’s report published June 16, 2026 says 99% of respondents waited more than one business day for a fresh full production copy of test data. Its respondent snapshot identifies 518 enterprise leaders surveyed globally with a third-party research firm. This is vendor-sponsored enterprise evidence, not a benchmark for every product team—or proof that every test needs a production copy.

    The narrower engineering question is often more actionable: what is the smallest trustworthy state needed to exercise this behavior? A full copy may contain millions of customers and still lack the precise expired entitlement or partially refunded order that the next release needs to handle.

    Keep this work connected to the broader automation architecture. TechAID’s QA automation strategy guide covers test layers and pipeline decisions. The deeper task here is to turn one scenario’s prerequisites into a maintained interface that those tests can consume.

    1. Specify the scenario before choosing its data source

    Start with an assertion and work backward. “An authorized support user can refund the remaining refundable amount” requires more than a customer and an order. It needs the correct role, tenant, payment state, previous refund history, policy version, and time boundary. Decide which of those conditions the test is actually intended to examine.

    For each important scenario, write a short contract with explicit prerequisites and observable outcomes. Keep business meaning separate from storage details so a schema change does not force every test author to rediscover the requirement.

    • Purpose: the behavior under test and the failure it should detect.
    • Required state: entities, relationships, permissions, amounts, and relevant timestamps.
    • Creation path: approved API, fixture, seed script, or controlled dataset.
    • Readiness: observable checks proving the prerequisites are available.
    • Ownership and lifetime: which run may mutate the records and when they expire.
    • Expected outcome: the result and side effects that must occur—or must not occur.

    This contract is the center of the test data strategy. A request for “a premium customer” is ambiguous; a request for “a tenant-scoped premium customer whose renewal is tomorrow and whose payment method has expired” is specific enough to implement and review.

    Do not let the setup perform the behavior being tested. If the test checks refund creation, the setup may create a captured payment and an earlier partial refund, but it must leave the final refund action to the test. Otherwise, a convenient fixture can accidentally remove the very integration path you wanted to verify.

    2. Choose the source that preserves the required evidence

    Use deliberately constructed data when the relevant business state can be represented faithfully. Small, named scenarios are easier to inspect than a large anonymous dataset. A factory that creates an account, subscription, and invoices together can make relationships explicit without requiring a copy of a real customer.

    Use an approved, minimized production-derived dataset when a specific characteristic cannot yet be reproduced adequately—for example, a difficult legacy record shape. Document why it is necessary, who approves access, what transformations are required, and when the copy must be removed. Do not treat a renamed customer field as evidence that the entire dataset is safe.

    Your test data strategy should distinguish data realism from system fidelity. Synthetic records can exercise the same database engine used in production. Conversely, realistic-looking records in a substitute database may miss behavioral differences. Microsoft’s EF Core testing guidance explains that a database test double can differ from the production provider, including string-comparison behavior.

    “Production database system” means the database technology and relevant configuration, not permission to run destructive tests against the live customer database. Use an isolated test instance. Record important differences in versions, collation, extensions, configuration, or external dependencies so passing results are not interpreted beyond their actual scope.

    Prefer application APIs for setup when they establish necessary business invariants. Direct database seeding can be useful for speed or otherwise unreachable states, but it may bypass validation, events, and derived records. Make that trade-off explicit. Neither route is universally correct, and the fastest insert method is not always the most faithful setup.

    Evaluate a test data management tool against the contract, not a feature checklist. Can it supply the required linked entities, preserve the approved relationships after transformation, expose readiness, and retire only the intended resources? A tool can support the test data strategy, but a successful provisioning demonstration does not prove that the resulting scenario satisfies your application’s rules.

    3. Preserve relationships, time, and deliberately invalid cases

    A collection of realistic names and email addresses is not a business scenario. An order must belong to the right customer, its lines must reconcile with its totals, and its payment and refund records must agree with the state you are testing. Generate related entities as a unit and validate the relationships before the main assertion runs.

    Define scenario builders around domain concepts, such as an active subscription with one overdue invoice. Keep defaults small and explicit. Allow a test to override the few properties that matter without copying an entire customer object into every test file. Review changes to shared defaults because they can silently change what many tests exercise.

    Time belongs in the test data strategy too. A fixed expiry date eventually becomes stale; using the current time everywhere can make boundary failures hard to reproduce. Choose a controlled reference time where the application supports it, or calculate relative dates from one recorded reference. Ensure the services involved interpret the same time zone and boundary.

    A seeded random generator can help reproduce generated values, but the seed alone is not a complete replay recipe. Record the generator version, scenario definition, application build, and relevant configuration. A changed generation sequence or library version can produce different values even when the seed is unchanged.

    Keep negative scenarios intentional. If a test needs a customer without an entitlement, say that explicitly and verify the absence. Do not rely on an incomplete seed script accidentally omitting it. Equally, do not “repair” every invalid record during setup when the purpose of the test is to verify rejection or safe handling of that invalid state.

    Avoid using the same calculation to generate both the input and the expected result. If a builder and assertion share a faulty refund-balance function, the test can agree with itself while the behavior is wrong. Include independently reviewed examples with known outcomes in the test data strategy, especially for money, permissions, and date boundaries.

    4. Make test data isolation match the mutation boundary

    Browser isolation does not automatically isolate server-side data. Two fresh browser sessions can still log in to the same account and update the same order. The test data strategy must identify the resources that can collide: tenants, users, inventory, queues, external sandbox accounts, and shared caches—not just browser cookies.

    Assign mutable records to a unique run and scenario. A practical identifier combines a run identifier with the worker and test instance; include an attempt identifier when retries must start fresh. Worker numbers alone may repeat across separate CI jobs, and a per-worker account can still be unsuitable when tests mutate shared state within that worker.

    Playwright’s parallelism documentation demonstrates creating database users per worker. That is a useful pattern when its sharing assumptions fit your tests. Decide separately whether each test also needs its own orders, permissions, or balances, and whether concurrent pipeline runs share the same backend.

    Shared read-only reference data can be efficient when its immutability is enforced. Mutable scenarios need stronger separation: independently owned records, a dedicated tenant, or a separate database or environment. Choose the smallest boundary that actually prevents interference. More infrastructure is not automatically better if it makes setup too slow to use.

    Transaction rollback can isolate some database tests, but it is not a universal cleanup mechanism. Microsoft’s database-testing guidance distinguishes ordinary write tests from tests whose application code manages transactions. External messages, object uploads, or calls to another service also require explicit handling; rolling back one database transaction does not reverse every side effect.

    5. Make provisioning, readiness, and cleanup observable

    Treat test data provisioning as a small workflow: validate the target, create the scenario, confirm readiness, return its identifiers, execute the test, and retire the resources. Each stage should have a clear result. A setup timeout must not be reported as a passing product test or hidden inside an unexplained retry.

    Readiness should reflect what the test will use. A successful database insert does not prove that an asynchronous projection, search index, or downstream service can see the record. Poll a relevant observable condition with a bounded timeout. Keep the expected condition explicit rather than sleeping for an arbitrary interval and hoping processing has finished.

    Fixtures can package this lifecycle. Playwright’s fixture documentation describes colocated setup and teardown, reuse, and composition. Use that structure to return a scenario object containing only the identifiers and helpers the test needs. Keep target validation and cleanup rules in the fixture implementation, where they can be reviewed consistently.

    Plan for partial creation. If the account is created but the order fails, record the account identifier immediately so cleanup can still find it. Make retirement safe to repeat, handle already-absent resources, and distinguish a successful cleanup from an attempted cleanup. Never use a broad delete or table reset against a shared environment merely because it is convenient.

    A robust test data strategy also handles crashed jobs. Use an approved expiry or lease mechanism and a separate cleanup process for abandoned test-owned resources. Check ownership, environment, and active leases before deletion. Preserve minimal, access-controlled diagnostic evidence when needed, without leaving sensitive datasets or credentials in general CI logs.

    6. Version the contract and give maintenance an owner

    Store scenario definitions and provisioning code with a reviewable version history. Record which application or schema versions they support. A schema migration, permission change, or new business rule should trigger a review of affected scenarios, not a scramble after the nightly suite stops working.

    Test the setup itself. Confirm that a known scenario can be created, read back, used by an authorized test identity, and removed. Introduce controlled setup failures in a safe environment to verify that partial resources are tracked and retired. This checks the test infrastructure; it does not replace assertions about the product.

    Assign responsibilities explicitly. The application team owns business invariants. QA owns scenario coverage and expected behavior. Platform or DevOps engineers own environment boundaries and supporting automation. Security and data owners approve sensitive-data use. One named maintainer should coordinate changes to the shared scenario interface.

    Measure whether the test data strategy improves the work. Track request-to-ready time, setup failures separately from product failures, collisions between runs, and abandoned-resource cleanup. Compare like-for-like suites and concurrency levels. A lower failure count is not progress if the team simply stops exercising the difficult scenarios.

    Keep the first implementation small. One critical flow with a reliable lifecycle is more useful than an enterprise catalog full of unverified entries. Expand only after another engineer can request the scenario, understand its limitations, and diagnose a failure without relying on its original author.

    Worked example: two refund tests share one order

    Consider a hypothetical subscription platform. One API test checks a second partial refund; another checks rejection after the refundable balance reaches zero. Both currently use the same staging customer and captured payment. Each passes alone, but their results depend on execution order. This is an illustrative example, not a TechAID customer result.

    The team’s test data strategy replaces the shared payment with two named scenarios. In the first, a payment of 100 units has a completed refund of 30, leaving 70 refundable. In the second, a payment of 100 has already been fully refunded. The amounts describe the test’s invented rules, not a payment provider’s universal behavior.

    Define separate starting states and outcomes

    For the partial-refund case, the contract requires an authorized support identity, the correct tenant, a captured payment, and the completed earlier refund. Readiness checks confirm both the payment service’s state and the application view used by the test. The action requests a refund of 20; the expected result is a remaining refundable amount of 50 and exactly one new refund record.

    For the exhausted-balance case, the contract requires a different payment with no refundable amount. The action requests an additional refund; the expected result is the application’s documented rejection and no new refund side effect. It is not enough to check an error message if the backend still created a refund request.

    Give every execution its own resource set

    Each test receives a unique tenant-scoped customer and payment reference for its run. The provisioning helper returns those references instead of a hardcoded account name. Calls to the payment dependency use an explicitly configured sandbox or controlled substitute, and the report states which boundary was exercised.

    A readiness timeout ends the attempt as a setup failure. If execution fails after resources exist, the record keeps the scenario version and identifiers needed for diagnosis. Cleanup retires only that run’s resources. Where a sandbox retains transaction history and cannot delete it, mark the resources unusable for future tests and apply the provider’s supported retention controls.

    Finally, run the two scenarios concurrently, repeat them in reversed order, and start a second pipeline run against the same permitted environment. Look for identifier collisions, incorrect cleanup, and shared quotas. Passing these checks supports the chosen isolation design; it does not establish that every possible concurrency level is safe.

    Turn the strategy into owned engineering work

    Before buying a platform or adding more test authors, identify the missing capability. Your team may need domain-aware scenario builders, reliable provisioning, cross-service readiness checks, or cleanup automation. Those are different tasks from writing more assertions. Estimate the work and reserve capacity to maintain it as the product changes.

    A test data strategy needs continuing client-side ownership of priorities, access, and business rules. TechAID’s nearshore staff augmentation model can add embedded QA or DevOps professionals under your management. Its published Verndale case describes QA leadership, tooling guidance, training, and automation adoption; it is evidence of that broader capability, not a claim of a specific test-data implementation.

    Bring one blocked test scenario, its current setup process, and the maintenance work your team cannot absorb to a staffing conversation with TechAID. Ask which responsibilities an embedded specialist could own. Start with a repeatable scenario and an accountable maintainer before expanding the catalog.
    Related Posts