Your engineering lead requests two weeks off. The calendar looks manageable until someone asks who can diagnose the order-import service, approve a risky schema change, and explain the one customer exception nobody wants to touch. Three names appear on the ownership chart. Only one person has done all three.
That is bus factor risk: the possibility that losing access to a small number of people stalls important work. It is not solved by putting another name in a spreadsheet, collecting more documentation, or hiring someone with the same programming language on their résumé.
For a CTO, the decision is where to invest in dependable coverage. Sometimes the answer is protected time for an existing engineer to learn. Sometimes it is a permanent additional owner. Temporary capacity or a bounded outsourcing engagement can help, but neither automatically creates lasting internal capability.
This guide connects the exposure you can demonstrate to the staffing decision you can defend. The goal is practical: critical work should remain possible when the usual expert is unavailable, without requiring that expert to remain permanently on call.
What bus factor risk actually measures
A bus factor of 1 means one person’s unavailability could stall the project or service being assessed. The boundary matters. Your organization might have dozens of engineers while a single person remains essential to a particular integration, release process, or operational decision.
Do not confuse the number of contributors with the number of people who can carry the work. An engineer may understand the application code but not the data repair procedure. Another may have reviewed changes without ever diagnosing a failed deployment. Familiarity is useful; it is not the same as independent capability.
The 2022 study Bus Factor In Practice surveyed 269 engineers and investigated knowledge signals beyond version-control activity, including reviews and meetings. Its findings support looking beyond commit counts; they do not provide a universal staffing ratio for every engineering team.
Measuring bus factor in software development depends on the assumptions behind it. A March 8, 2026 research preprint on computing the bus factor highlights inconsistent failure definitions and modeling assumptions across existing approaches. Treat a calculated score as an aid to investigation, not a certificate that operations are safe.
Use a concrete question instead: if the usual owner were unavailable for the period that matters to this business, which necessary tasks could the remaining team complete safely? Define that period and those tasks before assigning a risk rating.
Assess bus factor risk before counting people
Start the bus factor risk review with business capabilities rather than repositories. Order fulfillment, customer provisioning, financial reconciliation, and production recovery are useful boundaries because the business can describe what interruption would mean. A repository list alone can miss dependencies that span teams.
For each capability, separate routine work from exceptions. A second engineer who can run the normal import may still be unable to resolve a duplicate transaction, recover from a partial failure, or distinguish a safe retry from one that creates inconsistent data.
Create a short coverage record with the service owner. It should answer the following questions:
- What must remain possible? Name the task and its acceptable delay, such as restoring an interrupted integration before the next processing window.
- Who has demonstrated it? Record a recent example, not a confidence estimate or a job title.
- What conditions are required? Include permissions, decision authority, access to relevant environments, and the availability of upstream teams.
- What happens if the expert cannot help? Identify the workaround, the escalation route, and the consequence if neither works.
Keep the record at task level. Someone might be independent for routine changes, supervised for recovery, and unprepared for a sensitive data correction. Those differences are more useful than a single green cell beside their name.
Prioritize severe consequences with weak demonstrated coverage. An undocumented internal convenience tool and a customer-facing order interface should not receive equal attention simply because both have one maintainer. Business impact and the time available to recover determine where the next hour of learning belongs.
Separate knowledge gaps from access and capacity gaps
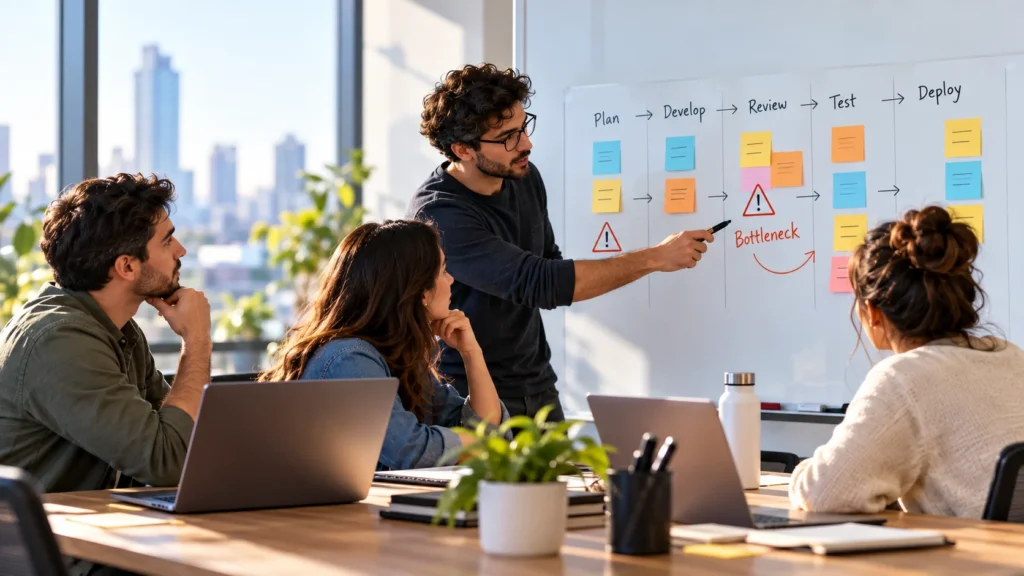
Before approving a requisition, identify what is actually preventing another person from doing the work. Bus factor risk can reflect missing expertise, missing context, missing authority, or insufficient available time. Each requires a different intervention.
Knowledge and context
Can the engineer explain the system’s important invariants, recognize an unsafe change, and identify the evidence needed before acting? Reading a runbook may teach the procedure without explaining why a tempting shortcut would be dangerous. Decision history and failure modes deserve deliberate transfer.
Access and authority
A qualified engineer who cannot obtain the appropriate access is not usable coverage during the required window. Equally, technical access does not imply permission to authorize a business-sensitive operation. Resolve approval paths while preserving least privilege and separation of duties; do not solve dependency by sharing an expert’s credentials.
Capacity and availability
Two capable people do not provide independent coverage if both are fully committed elsewhere or routinely unavailable at the same time. Check actual working-hour overlap, leave plans, escalation commitments, and the workload needed to keep knowledge current. Nearshore geography can make overlap easier to arrange, but the schedule must still be agreed.
This diagnosis keeps the response proportionate. An access bottleneck may require an approval change. A context gap may need pairing. A recurring specialist workload may justify hiring. Adding a person before distinguishing these constraints can increase onboarding demands while leaving the original exposure untouched.
Choose the smallest durable staffing response
The right bus factor risk response is the least complex option that can sustain the required capability. Compare the ongoing work, the time needed to transfer context, and the management capacity available—not just the speed at which another person could start.
Cross-train when the capability already exists
Use an existing engineer when they have the foundational skills, an ongoing reason to remain close to the system, and capacity you can genuinely protect. Remove competing commitments rather than adding knowledge transfer to an already full sprint.
Define a bounded responsibility they will retain after training. If the person returns to an unrelated backlog and never touches the system again, the coverage you created may become stale. Cross-training is an operating arrangement, not attendance at a demonstration.
Hire permanently when ownership is a continuing job
Direct hiring becomes a stronger option when the system will remain important, the work persists beyond a temporary initiative, and the current organization lacks a sustainable additional owner. The role should include maintenance, change, incident learning, and collaboration—not simply waiting to replace someone during an absence.
A permanent hire can reduce bus factor risk only if the organization funds the transition. The incumbent needs time to teach, the newcomer needs appropriate access, and both need opportunities to work across the boundary. Recruiting solves the talent acquisition problem; management still owns the distribution of knowledge.
A useful hiring requirement is therefore not “another senior backend developer.” It is an engineer who can progressively share responsibility for a named business capability, work within the necessary overlap window, and help other people understand the system as it evolves.
Augment when time is the missing resource
Staff augmentation can provide embedded capacity under your management while an internal engineer learns the critical system, or bring a specialist into a defined transition. Specify which work the augmented professional owns and which lasting capability your employees must retain.
Do not count the engagement as bus factor risk mitigation merely because the contract is signed. If the new specialist becomes the only person who understands the replacement system, the dependency has moved rather than disappeared. Include shared work, readable decision records, and an explicit handover in the operating plan.
Outsource a bounded result when it can remove the dependency
Project outsourcing may fit a clearly scoped intervention, such as replacing a fragile manual process with a maintainable workflow. Define acceptance around the result and the receiving team’s ability to operate it. The client still needs someone accountable for requirements, decisions, and acceptance.
It is a weaker fit when the problem is continuous ownership of an evolving core system and no internal person can evaluate the delivered work. A supplier-managed project can simplify a dependency, but it should not be assumed to eliminate the need for informed internal ownership.
Build the business case without invented outage economics
A credible bus factor risk business case starts with observed constraints. Bring examples of delayed decisions, work that waited for a specific person, recovery exercises that could not proceed, or leave arrangements that depended on the expert remaining reachable.
Then compare the full effort of each response. For cross-training, include both participants’ time and the work displaced. For hiring, include recruiting, onboarding, compensation, and ongoing management. For augmentation or outsourcing, include fees, coordination, acceptance, and knowledge retention after the engagement ends.
Separate expected workload from uncertain exposure. You may know that recurring ownership requires a meaningful portion of an engineer’s time. You may not know the probability of a simultaneous absence and serious incident. Present those uncertainties explicitly instead of inventing an annual failure probability to make a hiring case look precise.
Give leadership a decision they can revisit: the coverage gap to close, the proposed owner, the investment, the evidence expected, and a review date. If the workload does not support a permanent role, say so. A smaller training allocation or a scoped simplification project may be the better use of budget.
Also name the cost of inaction in operational terms. “The recovery path has never been completed without the lead engineer” is more defensible than a dramatic revenue-loss estimate without supporting data. The first statement identifies a condition management can test and improve.
Use an ownership brief, not a clone of the incumbent
When hiring is justified, translate the bus factor risk assessment into a role brief. The goal is complementary coverage, not finding someone with the same career history, personality, and undocumented habits as the person you already depend on.
Include the business capability, its current operating constraints, and the responsibilities the new hire should eventually share. Separate essential foundations from system-specific knowledge that can be learned. Specify the working-hour overlap needed for collaboration without assuming that every LATAM location follows the same schedule.
Evaluate how candidates investigate unfamiliar systems and communicate uncertainty. A discussion of a sanitized failure scenario can reveal whether they ask about invariants, observability, permissions, and rollback conditions before proposing changes. Avoid testing private production knowledge that only an existing employee could reasonably possess.
Agree on the support the organization will provide. Who will explain historical decisions? Who can approve access? Which work can be used for supervised practice? What delivery commitments will change while the incumbent helps the new colleague become effective?
TechAID’s nearshore developer onboarding playbook can help organize that initial integration. Use it as a starting point for access, context, and contribution—not as a promise that a complex service can gain an independent owner within ten days.
A role brief that answers these questions is also a better conversation with a recruiting partner. It makes the capability gap concrete and keeps candidate selection connected to the business reason the position exists.
Require evidence that knowledge transfer worked
For bus factor risk mitigation, completed documentation is an input, not the final acceptance test. The stronger evidence is another person completing representative work, explaining the decisions, and recognizing when they should stop or escalate.
Google’s SRE workbook describes training through starter projects, practical exercises, service deep dives, and incident role-play. The relevant lesson is active practice, not copying Google’s organization size or assuming its onboarding timelines apply to your team.
Build a progression that suits the system. The learner first observes a task with its rationale, then performs it with help, then leads it while the experienced owner observes. Finally, use an appropriate controlled exercise to test whether the learner can proceed without step-by-step prompting.
Record what the evidence actually shows. A successful routine deployment does not establish readiness to recover corrupted data. A tabletop discussion can test decisions and escalation logic but cannot prove that a restore works. Match the exercise to the claim you want to make.
Plan exercises safely. Prefer non-production environments, representative data, and bounded changes with a clear abort condition. Any production exercise needs the normal authorization and operational safeguards. The purpose is to reveal gaps without exposing customers to avoidable failure.
A useful bus factor mitigation plan makes independent ownership collaborative. A prepared engineer should know when to involve security, product, infrastructure, or another specialist. Independence means operating within agreed boundaries and escalating appropriately, not acting alone regardless of consequences.
A worked example: cover the order-import service
Consider a hypothetical software company with one engineer who understands a critical order-import service. Several teammates can modify the surrounding application, but only the owner knows how to diagnose partial imports and decide whether a retry is safe. This is an illustrative scenario, not a TechAID client result.
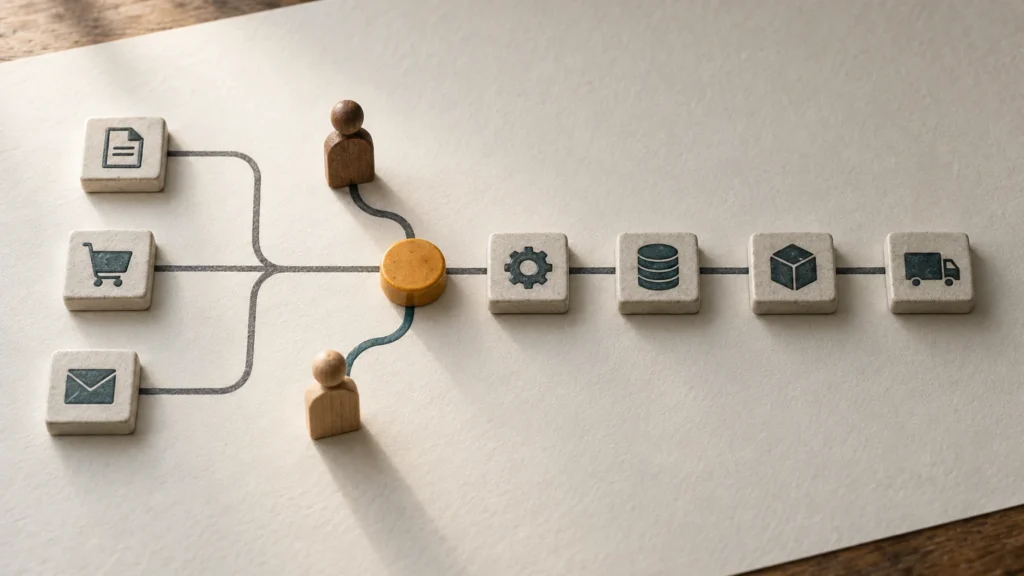
The first bus factor risk review separates three tasks: routine configuration changes, diagnosing a failed batch, and correcting inconsistent records. A teammate can already perform the first task. The second requires system context. The third also requires a business approval path that is not documented.
Management initially proposes hiring another developer. The assessment shows two separate actions are needed: clarify who can approve sensitive corrections, and create sustainable technical coverage. Hiring alone would not fix the authorization gap.
Next, the team estimates ongoing work. If the service is stable and an existing engineer can own its recurring changes, protected cross-training may be sufficient. If the integration is expanding and both maintenance and new development require lasting capacity, a permanent role has a clearer purpose.
Suppose the continuing workload supports that role. The hiring brief prioritizes integration experience, failure diagnosis, careful handling of retries, and communication of operational decisions. It does not demand prior knowledge of this company’s private system.
The coverage claim changes only after evidence improves: a second engineer diagnoses a representative partial failure, explains the safe recovery choices, follows the approval path, and updates the runbook where it was ambiguous. The team then schedules continuing work so that capability does not disappear through disuse.
Keep coverage current without creating a surveillance program
Bus factor risk is not a ranking of which employees are most replaceable. Present the work as protecting people’s ability to take leave, change responsibilities, and contribute without becoming a permanent escalation point. Avoid publishing personal dependency scores as performance judgments.
Review critical coverage when the system changes materially, responsibilities move, an engagement ends, or planned leave exposes an availability gap. A fixed review cadence can help, but a calendar reminder should not substitute for responding to a significant architecture or ownership change.
Track a few operational signals:
- Critical tasks with a current, demonstrated backup—not merely an assigned backup.
- Work delayed because only one person could explain, approve, or complete it.
- Open gaps discovered during exercises, with an owner and a retest condition.
- Whether the original expert is still being interrupted for work the team considers transferred.
Do not reward a higher score by encouraging superficial rotations or unnecessary privileged access. Keep evidence specific, minimize personal data collection, and discuss gaps with the people who do the work. The organization is accountable for providing time, training, and sensible boundaries.
Make the next hiring conversation about durable ownership
Reducing bus factor risk is ultimately a design decision about work and responsibility. Identify the capability that must survive an absence, demonstrate where coverage is weak, and choose an intervention that the organization can sustain.
If the need is lasting, hiring a permanent LATAM engineer can be a practical way to build additional ownership. That decision should come with a realistic learning path and evidence of shared capability, not an expectation that a new hire will absorb years of context immediately.
TechAID supports permanent technical roles through its Direct Hiring model. If your assessment points to a continuing ownership gap, bring one critical system, its recurring workload, and the coverage you need to a direct hiring conversation with TechAID. Those inputs can help define the role before you begin comparing candidate profiles.