Dependency Updates: A 7-Step Workflow Beyond Green CI

Dependency Updates: A 7-Step Workflow Beyond Green CI

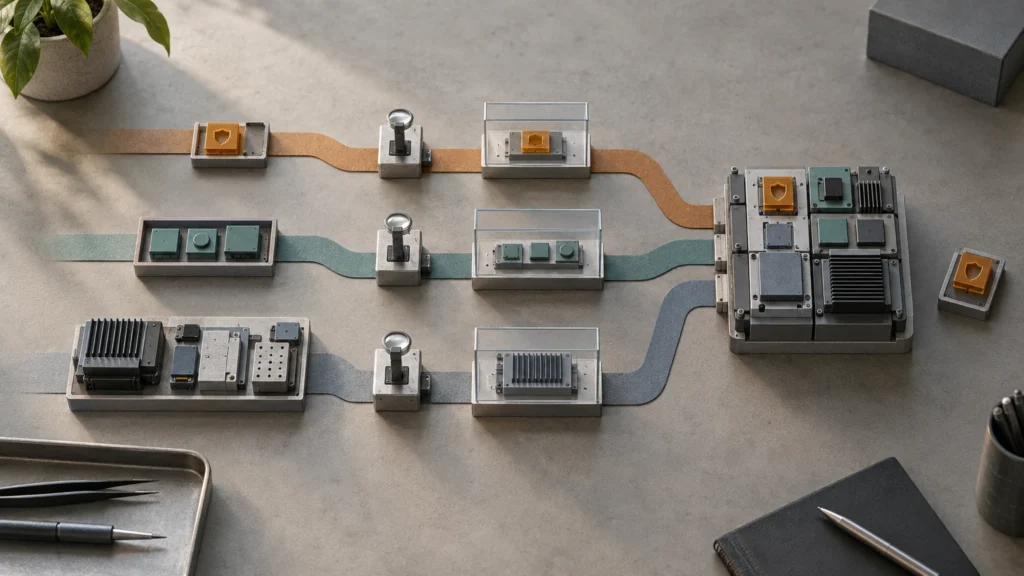
Editorial illustration of dependency updates taking separate review and testing paths before staged deployment.
A dependency bot can open a pull request, but it cannot own your release decision. Use a seven-step workflow to prioritize upgrades, collect useful evidence, verify deployment, and identify where added engineering capacity would help.
Share the Post:

The dependency bot is working. Your team has a growing list of pull requests, several security alerts, and a framework upgrade nobody wants to start before the next release. What you do not have is a reliable way to decide what moves first, what evidence makes it safe enough to ship, and who closes the loop after deployment.

Dependency updates need an operating workflow, not just another automation rule. A useful workflow separates urgency from implementation difficulty, keeps changes reviewable, and treats production verification as part of the job. It also makes a staffing decision clearer: do you need more implementation capacity, or are existing engineers waiting for decisions only your team can make?

The seven steps below are a practical starting point for application teams. They are proposed operating practices, not a universal security standard or a promise that every upgrade can be automated. Adapt the controls to your application, package ecosystem, release process, and risk requirements.

1. Give dependency updates a service-level owner

Begin with deployed services, not a spreadsheet of package names. For each service, identify its accountable engineering owner, supported runtime, package manifests and lockfiles, deployment path, and the person who can approve a production change. Include shared libraries and build tooling when they affect how that service is delivered.

An inventory is useful only if it connects a finding to work. A scanner may identify a vulnerable package in a repository that no longer ships, while an old container image continues running elsewhere. Record where the affected version is actually used, including scheduled jobs, background workers, and supported release branches. Do not assume the default branch represents production.

Track related dependency updates under one change objective and connect their pull requests. A useful record contains:

  • Affected service and dependency path, including whether the package is direct or transitive.
  • Current deployed version, proposed target, and the reason for changing it.
  • Risk owner, implementation owner, reviewer, and release approver.
  • Required evidence, deployment route, and recovery or mitigation plan.
  • Next decision date and the condition that will count as completion.

A single engineer can fill several roles in a small team. The point is explicit responsibility, not administrative complexity. When a shared package affects several services, nominate a coordinating owner while leaving each service owner responsible for its release.

This distinction matters because patching does not end at installation instructions. NIST’s enterprise patch-management guidance includes verifying installation and frames patching as preventive maintenance. For an application team, the practical implication is straightforward: a merged pull request is an intermediate state, not proof that the running system changed.

2. Separate urgency from upgrade effort

A small patch can be urgent. A major upgrade can be important without being today’s incident. Treat those as separate questions instead of using the version number as your entire prioritization policy.

For dependency updates, create three work lanes with different scheduling rules. Keep all three visible in the same planning process so that urgent work does not permanently hide routine maintenance.

Urgent remediation

Use this lane when the security or service owner determines that the current exposure requires accelerated action. Assess the affected version, actual usage, exposure, available mitigations, and credible information about exploitation. If you cannot establish exposure quickly, escalate the uncertainty rather than treating missing evidence as evidence of safety.

Agree on a response deadline appropriate to the risk. There is no responsible universal promise that every vulnerability must be patched within the same number of hours. When no viable patch exists, assign a mitigation or replacement decision, an accountable owner, and a review date. A blocked upgrade still needs active ownership.

Routine maintenance

Use a scheduled review window for non-urgent changes that fit the existing architecture. Reserve capacity for these dependency updates instead of making them compete informally with every feature request. A weekly queue review can be a useful starting policy, but it is not a reason to delay urgent remediation until that meeting.

Planned migration

Put changes here when they require application rewrites, runtime coordination, data changes, or substantial integration testing. Give the work explicit milestones and an owner. If a security fix requires a migration, it remains security work; the implementation difficulty does not downgrade its urgency.

Semantic Versioning describes how compatible fixes, compatible additions, and incompatible API changes should be signaled. It also treats versions below 1.0 as unstable. Use those signals to estimate review effort, not as a substitute for examining the change. A patch-level label does not prove that your application, deployment scripts, or business workflows remain unaffected.

3. Configure automation around the lanes

Automated dependency updates are valuable when they prepare actionable work. They become noise when every new release creates an equally urgent request with no reviewer, no grouping policy, and no connection to deployment.

Document the behavior you want before changing bot settings. Decide which repositories and manifests are covered, who receives review requests, when routine changes are proposed, and which conditions prevent automatic merging. Test automated dependency updates on a representative repository before extending the configuration across the estate.

GitHub’s Dependabot version-update documentation distinguishes routine version updates from security updates. As checked on October 12, 2026, it documents a default three-day cooldown for version updates and explicitly excludes security updates from that default. Verify the settings that apply to your repositories rather than assuming one delay governs both paths.

A cooldown is a release-age filter, not a security review or a guarantee that a package is trustworthy. Waiting can give maintainers time to discover problems, but age alone does not establish safety. Conversely, a routine waiting period should not silently become your response policy for an urgent vulnerability.

Make exceptions visible. If a team delays a package because of an unresolved compatibility issue, record the reason, owner, and next review date. Avoid permanent ignore rules that hide a dependency until someone rediscovers it during an incident.

Keep automation permissions proportionate to its job. A bot that prepares a change does not automatically need the authority to approve it or deploy it. Preserve your normal access controls and approval boundaries, especially when update workflows can execute build scripts.

Dependency update automation should also fail visibly. A missing pull request may reflect an unsupported configuration, an inaccessible registry, or an unresolved dependency graph. Review those failures as work items. “The bot did not open anything” is not a reliable statement about the health of the application.

4. Group changes by how you will validate them

Grouping dependency updates can reduce review overhead, but a smaller pull-request count is not the objective. The objective is a change that one reviewer can understand and one release process can validate.

Group packages when they genuinely move together: a framework and its tightly coupled plugins, for example, or a small collection of development tools with the same checks and owner. Separate unrelated runtime changes if combining them would make failures difficult to diagnose.

Before approving a group, ask three questions. Does it have one coherent reason to change? Can the affected behavior be tested together? If a check fails, can the team isolate the cause without reconstructing a large, unrelated batch?

Do not bury urgent dependency updates inside an optional upgrade bundle. The bundle may wait for a migration decision while the security change could have shipped independently. Similarly, do not split a tightly coupled upgrade into individually green pull requests if the intermediate deployed combinations are unsupported.

For transitive dependencies, inspect the resolution path. The safe change may require upgrading the parent package, adjusting a supported constraint, or removing an unused dependency. A forced override can produce a version combination the parent package was never designed to use. Treat overrides as deliberate exceptions with compatibility evidence and an exit plan.

Keep the proposed version change connected to the generated lockfile and the resulting build. Review unexpected additions, removals, or registry changes rather than checking only the one package named in the pull-request title. A narrow title can conceal a much larger resolved change.

5. Require evidence beyond a green build

For dependency updates, a passing pipeline answers only the questions that pipeline actually asks. It might verify compilation and unit behavior without exercising authentication, billing retries, background jobs, or a partner API affected by the upgrade.

Start with the business behavior most likely to change. If the package handles serialization, exercise representative payloads and compatibility boundaries. If it handles database access, inspect queries, connection behavior, and transaction paths. If it changes a build tool, verify the artifact and packaging process, not just source-level tests.

A practical evidence packet should let the reviewer understand both what was checked and what remains uncertain. Keep it with the change rather than in a separate document that quickly becomes stale.

  • Change understanding: release notes reviewed, relevant behavior identified, and application impact explained.
  • Build evidence: the target revision builds with the intended resolved versions and produces the expected artifact.
  • Behavior evidence: relevant unit, integration, contract, or end-to-end checks cover the affected path.
  • Operational evidence: the team has a deployment plan, useful health signals, and a viable recovery or mitigation action.
  • Decision record: the reviewer names any accepted uncertainty and the person authorized to accept it.

Do not turn that packet into a requirement to run every expensive test for every package. Match the depth to the change and the consequence of failure. A formatting-tool update and a payment-library upgrade should not receive identical validation simply because both arrived through the same bot.

Equally, a “development dependency” label is not automatic permission to skip review. Build tools can affect generated assets, packaging, and the execution environment. Explain why a lighter path is appropriate instead of relying on the category alone.

GitHub’s documentation on Dependabot compatibility scores says they are calculated from CI runs in other public repositories. That can provide context, but it is not evidence that your own application has passed its critical workflows.

When unreliable tests prevent a decision, name that limitation. Repeatedly rerunning a failed job until it passes does not explain whether the upgrade introduced a regression. Fix or isolate the unreliable signal, and document any additional validation required before release.

If your team lacks a clear testing foundation, TechAID’s QA automation strategy for CI/CD provides a related framework for test placement and ownership. The dependency-specific task is narrower: show why the checks selected for this change are sufficient to support the release decision.

6. Close the work at verified deployment

Track dependency updates through distinct states: merged, released, deployed, and verified. Teams do not need a heavyweight approval system to preserve those distinctions; clear fields in the existing work item may be enough.

Before deployment, identify the artifact or release that contains the update and the environments that still run the affected version. Decide what you will observe, who will observe it, and what condition requires intervention. Use staged rollout where your architecture supports it, but do not describe a canary as protection against every possible defect.

Choose signals that reflect the changed behavior. A healthy web-process check may miss a background worker that has stopped consuming jobs. An unchanged average response time may hide a failure limited to a particular integration or customer path.

Recovery deserves its own review. Reverting code may not reverse a schema change, restore overwritten data, or make an older runtime compatible with a new artifact. For dependency security updates, reverting to the vulnerable version can also reintroduce the original exposure. Plan that trade-off with the risk owner; sometimes mitigation or a forward fix is the appropriate response.

Close dependency updates only when the intended environments are verified, or explicitly record the environments still outstanding. Attach the deployed version or artifact identity and the relevant verification result. If an alert disappears after a merge, that is useful repository evidence—not a substitute for checking what is running.

For services with separate release branches, repeat the closure check for each supported branch that needs the fix. Avoid declaring the application remediated when only the next unreleased version contains the change.

7. Measure the queue before adding capacity

A backlog count alone cannot tell you whether more engineers will help. Separate active implementation from time waiting for ownership, review, environment access, or release approval.

Track dependency updates with a small set of operational measures:

  • Time from triage to verified deployment, separated by work lane.
  • Age of unresolved urgent items and the documented reason each remains open.
  • Waiting time by cause: implementation, review, testing, access, or release.
  • Failed changes, recovery actions, and repeat failures caused by the same missing check.
  • Exceptions past their review date and services without an accountable owner.

Use your own baseline before setting improvement targets. A team may close many low-impact bot requests while one exposed service remains unchanged. Another may temporarily close fewer requests because it is repairing the test infrastructure that will make future work safer.

Count successful changes against the original risk or maintenance objective, not the number of generated pull requests. Closing duplicates or suppressing alerts may improve queue hygiene, but it is not the same as deploying a required update.

Review the measures with the people who can remove the constraint. If implementation is consistently waiting for a designated reviewer, adding more authors can increase the queue. If decisions are timely but approved work exceeds available engineering hours, added capacity has a clearer purpose.

This is where embedded engineering support can fit naturally. Define work such as preparing reviewable upgrades, extending affected-path tests, resolving bot failures, and collecting deployment evidence. Your service owners should retain prioritization, architectural decisions, risk acceptance, and release authority.

Do not hand an outside engineer an unfiltered alert list and call the outcome ownership. Give them repository context, least-privilege access, a named internal reviewer, and a definition of done. Reserve internal review time as part of the capacity plan. Otherwise, the new contributor can become another person waiting for the same unanswered decisions.

A worked example: three changes, three different decisions

Consider a fictional B2B application with a web API, an asynchronous worker, and a customer integration. Its team has three proposed changes: a vulnerable parser used by the API, a non-urgent linting-tool update, and a major framework upgrade that changes integration behavior.

The parser goes through urgent triage. The service owner confirms where it runs, the security owner assesses the exposure, and an engineer identifies a viable fixed version. Tests cover representative inputs and error handling. The deployment record includes both API instances and any worker that uses the same package.

The linting change enters the routine window. The reviewer checks configuration differences, generated changes, and build output. It does not need the parser’s exposure analysis, but it still needs a reasoned validation path.

The framework upgrade becomes planned migration work. The team identifies changed interfaces, tests the customer integration, and defines intermediate milestones. It does not bundle that project into the parser fix merely because both touch the same manifest.

If the parser’s only viable fix requires the new framework, the decisions change: the migration becomes part of urgent remediation planning, with explicit mitigation while it is incomplete. The lanes organize work; they do not override the facts.

The example illustrates a decision process, not a benchmark or a TechAID customer result. The same three changes could require different treatment in another application.

Turn the workflow into a useful engineering brief

Start by applying this workflow for dependency updates to one representative service. Map its ownership, classify its outstanding changes, and take one update all the way through verified deployment. Use what you learn to refine the evidence packet and remove a real source of delay before expanding the process.

If that exercise shows a sustained implementation gap, discuss nearshore staff augmentation with TechAID. Bring a sample update backlog, your review and release constraints, and the skills the work requires. That creates a concrete conversation about embedded engineering capacity under your management—not a promise that staffing alone will solve unclear ownership or weak release controls.
Key Takeaways
  • Assign each dependency update to a service owner and verify the change in the deployed system.

  • Separate urgent remediation, routine maintenance, and planned migrations so risk—not effort alone—sets priority.

  • Configure dependency bots to create actionable, reviewable changes without bypassing approval controls.

  • Group updates only when they share a validation path, and keep urgent fixes distinct from optional upgrades.

  • Make deployment verification, recovery planning, and follow-up ownership part of the update workflow.

  • The dependency bot is working. Your team has a growing list of pull requests, several security alerts, and a framework upgrade nobody wants to start before the next release. What you do not have is a reliable way to decide what moves first, what evidence makes it safe enough to ship, and who closes the loop after deployment.

    Dependency updates need an operating workflow, not just another automation rule. A useful workflow separates urgency from implementation difficulty, keeps changes reviewable, and treats production verification as part of the job. It also makes a staffing decision clearer: do you need more implementation capacity, or are existing engineers waiting for decisions only your team can make?

    The seven steps below are a practical starting point for application teams. They are proposed operating practices, not a universal security standard or a promise that every upgrade can be automated. Adapt the controls to your application, package ecosystem, release process, and risk requirements.

    1. Give dependency updates a service-level owner

    Begin with deployed services, not a spreadsheet of package names. For each service, identify its accountable engineering owner, supported runtime, package manifests and lockfiles, deployment path, and the person who can approve a production change. Include shared libraries and build tooling when they affect how that service is delivered.

    An inventory is useful only if it connects a finding to work. A scanner may identify a vulnerable package in a repository that no longer ships, while an old container image continues running elsewhere. Record where the affected version is actually used, including scheduled jobs, background workers, and supported release branches. Do not assume the default branch represents production.

    Track related dependency updates under one change objective and connect their pull requests. A useful record contains:

    • Affected service and dependency path, including whether the package is direct or transitive.
    • Current deployed version, proposed target, and the reason for changing it.
    • Risk owner, implementation owner, reviewer, and release approver.
    • Required evidence, deployment route, and recovery or mitigation plan.
    • Next decision date and the condition that will count as completion.

    A single engineer can fill several roles in a small team. The point is explicit responsibility, not administrative complexity. When a shared package affects several services, nominate a coordinating owner while leaving each service owner responsible for its release.

    This distinction matters because patching does not end at installation instructions. NIST’s enterprise patch-management guidance includes verifying installation and frames patching as preventive maintenance. For an application team, the practical implication is straightforward: a merged pull request is an intermediate state, not proof that the running system changed.

    2. Separate urgency from upgrade effort

    A small patch can be urgent. A major upgrade can be important without being today’s incident. Treat those as separate questions instead of using the version number as your entire prioritization policy.

    For dependency updates, create three work lanes with different scheduling rules. Keep all three visible in the same planning process so that urgent work does not permanently hide routine maintenance.

    Urgent remediation

    Use this lane when the security or service owner determines that the current exposure requires accelerated action. Assess the affected version, actual usage, exposure, available mitigations, and credible information about exploitation. If you cannot establish exposure quickly, escalate the uncertainty rather than treating missing evidence as evidence of safety.

    Agree on a response deadline appropriate to the risk. There is no responsible universal promise that every vulnerability must be patched within the same number of hours. When no viable patch exists, assign a mitigation or replacement decision, an accountable owner, and a review date. A blocked upgrade still needs active ownership.

    Routine maintenance

    Use a scheduled review window for non-urgent changes that fit the existing architecture. Reserve capacity for these dependency updates instead of making them compete informally with every feature request. A weekly queue review can be a useful starting policy, but it is not a reason to delay urgent remediation until that meeting.

    Planned migration

    Put changes here when they require application rewrites, runtime coordination, data changes, or substantial integration testing. Give the work explicit milestones and an owner. If a security fix requires a migration, it remains security work; the implementation difficulty does not downgrade its urgency.

    Semantic Versioning describes how compatible fixes, compatible additions, and incompatible API changes should be signaled. It also treats versions below 1.0 as unstable. Use those signals to estimate review effort, not as a substitute for examining the change. A patch-level label does not prove that your application, deployment scripts, or business workflows remain unaffected.

    3. Configure automation around the lanes

    Automated dependency updates are valuable when they prepare actionable work. They become noise when every new release creates an equally urgent request with no reviewer, no grouping policy, and no connection to deployment.

    Document the behavior you want before changing bot settings. Decide which repositories and manifests are covered, who receives review requests, when routine changes are proposed, and which conditions prevent automatic merging. Test automated dependency updates on a representative repository before extending the configuration across the estate.

    GitHub’s Dependabot version-update documentation distinguishes routine version updates from security updates. As checked on October 12, 2026, it documents a default three-day cooldown for version updates and explicitly excludes security updates from that default. Verify the settings that apply to your repositories rather than assuming one delay governs both paths.

    A cooldown is a release-age filter, not a security review or a guarantee that a package is trustworthy. Waiting can give maintainers time to discover problems, but age alone does not establish safety. Conversely, a routine waiting period should not silently become your response policy for an urgent vulnerability.

    Make exceptions visible. If a team delays a package because of an unresolved compatibility issue, record the reason, owner, and next review date. Avoid permanent ignore rules that hide a dependency until someone rediscovers it during an incident.

    Keep automation permissions proportionate to its job. A bot that prepares a change does not automatically need the authority to approve it or deploy it. Preserve your normal access controls and approval boundaries, especially when update workflows can execute build scripts.

    Dependency update automation should also fail visibly. A missing pull request may reflect an unsupported configuration, an inaccessible registry, or an unresolved dependency graph. Review those failures as work items. “The bot did not open anything” is not a reliable statement about the health of the application.

    4. Group changes by how you will validate them

    Grouping dependency updates can reduce review overhead, but a smaller pull-request count is not the objective. The objective is a change that one reviewer can understand and one release process can validate.

    Group packages when they genuinely move together: a framework and its tightly coupled plugins, for example, or a small collection of development tools with the same checks and owner. Separate unrelated runtime changes if combining them would make failures difficult to diagnose.

    Before approving a group, ask three questions. Does it have one coherent reason to change? Can the affected behavior be tested together? If a check fails, can the team isolate the cause without reconstructing a large, unrelated batch?

    Do not bury urgent dependency updates inside an optional upgrade bundle. The bundle may wait for a migration decision while the security change could have shipped independently. Similarly, do not split a tightly coupled upgrade into individually green pull requests if the intermediate deployed combinations are unsupported.

    For transitive dependencies, inspect the resolution path. The safe change may require upgrading the parent package, adjusting a supported constraint, or removing an unused dependency. A forced override can produce a version combination the parent package was never designed to use. Treat overrides as deliberate exceptions with compatibility evidence and an exit plan.

    Keep the proposed version change connected to the generated lockfile and the resulting build. Review unexpected additions, removals, or registry changes rather than checking only the one package named in the pull-request title. A narrow title can conceal a much larger resolved change.

    5. Require evidence beyond a green build

    For dependency updates, a passing pipeline answers only the questions that pipeline actually asks. It might verify compilation and unit behavior without exercising authentication, billing retries, background jobs, or a partner API affected by the upgrade.

    Start with the business behavior most likely to change. If the package handles serialization, exercise representative payloads and compatibility boundaries. If it handles database access, inspect queries, connection behavior, and transaction paths. If it changes a build tool, verify the artifact and packaging process, not just source-level tests.

    A practical evidence packet should let the reviewer understand both what was checked and what remains uncertain. Keep it with the change rather than in a separate document that quickly becomes stale.

    • Change understanding: release notes reviewed, relevant behavior identified, and application impact explained.
    • Build evidence: the target revision builds with the intended resolved versions and produces the expected artifact.
    • Behavior evidence: relevant unit, integration, contract, or end-to-end checks cover the affected path.
    • Operational evidence: the team has a deployment plan, useful health signals, and a viable recovery or mitigation action.
    • Decision record: the reviewer names any accepted uncertainty and the person authorized to accept it.

    Do not turn that packet into a requirement to run every expensive test for every package. Match the depth to the change and the consequence of failure. A formatting-tool update and a payment-library upgrade should not receive identical validation simply because both arrived through the same bot.

    Equally, a “development dependency” label is not automatic permission to skip review. Build tools can affect generated assets, packaging, and the execution environment. Explain why a lighter path is appropriate instead of relying on the category alone.

    GitHub’s documentation on Dependabot compatibility scores says they are calculated from CI runs in other public repositories. That can provide context, but it is not evidence that your own application has passed its critical workflows.

    When unreliable tests prevent a decision, name that limitation. Repeatedly rerunning a failed job until it passes does not explain whether the upgrade introduced a regression. Fix or isolate the unreliable signal, and document any additional validation required before release.

    If your team lacks a clear testing foundation, TechAID’s QA automation strategy for CI/CD provides a related framework for test placement and ownership. The dependency-specific task is narrower: show why the checks selected for this change are sufficient to support the release decision.

    6. Close the work at verified deployment

    Track dependency updates through distinct states: merged, released, deployed, and verified. Teams do not need a heavyweight approval system to preserve those distinctions; clear fields in the existing work item may be enough.

    Before deployment, identify the artifact or release that contains the update and the environments that still run the affected version. Decide what you will observe, who will observe it, and what condition requires intervention. Use staged rollout where your architecture supports it, but do not describe a canary as protection against every possible defect.

    Choose signals that reflect the changed behavior. A healthy web-process check may miss a background worker that has stopped consuming jobs. An unchanged average response time may hide a failure limited to a particular integration or customer path.

    Recovery deserves its own review. Reverting code may not reverse a schema change, restore overwritten data, or make an older runtime compatible with a new artifact. For dependency security updates, reverting to the vulnerable version can also reintroduce the original exposure. Plan that trade-off with the risk owner; sometimes mitigation or a forward fix is the appropriate response.

    Close dependency updates only when the intended environments are verified, or explicitly record the environments still outstanding. Attach the deployed version or artifact identity and the relevant verification result. If an alert disappears after a merge, that is useful repository evidence—not a substitute for checking what is running.

    For services with separate release branches, repeat the closure check for each supported branch that needs the fix. Avoid declaring the application remediated when only the next unreleased version contains the change.

    7. Measure the queue before adding capacity

    A backlog count alone cannot tell you whether more engineers will help. Separate active implementation from time waiting for ownership, review, environment access, or release approval.

    Track dependency updates with a small set of operational measures:

    • Time from triage to verified deployment, separated by work lane.
    • Age of unresolved urgent items and the documented reason each remains open.
    • Waiting time by cause: implementation, review, testing, access, or release.
    • Failed changes, recovery actions, and repeat failures caused by the same missing check.
    • Exceptions past their review date and services without an accountable owner.

    Use your own baseline before setting improvement targets. A team may close many low-impact bot requests while one exposed service remains unchanged. Another may temporarily close fewer requests because it is repairing the test infrastructure that will make future work safer.

    Count successful changes against the original risk or maintenance objective, not the number of generated pull requests. Closing duplicates or suppressing alerts may improve queue hygiene, but it is not the same as deploying a required update.

    Review the measures with the people who can remove the constraint. If implementation is consistently waiting for a designated reviewer, adding more authors can increase the queue. If decisions are timely but approved work exceeds available engineering hours, added capacity has a clearer purpose.

    This is where embedded engineering support can fit naturally. Define work such as preparing reviewable upgrades, extending affected-path tests, resolving bot failures, and collecting deployment evidence. Your service owners should retain prioritization, architectural decisions, risk acceptance, and release authority.

    Do not hand an outside engineer an unfiltered alert list and call the outcome ownership. Give them repository context, least-privilege access, a named internal reviewer, and a definition of done. Reserve internal review time as part of the capacity plan. Otherwise, the new contributor can become another person waiting for the same unanswered decisions.

    A worked example: three changes, three different decisions

    Consider a fictional B2B application with a web API, an asynchronous worker, and a customer integration. Its team has three proposed changes: a vulnerable parser used by the API, a non-urgent linting-tool update, and a major framework upgrade that changes integration behavior.

    The parser goes through urgent triage. The service owner confirms where it runs, the security owner assesses the exposure, and an engineer identifies a viable fixed version. Tests cover representative inputs and error handling. The deployment record includes both API instances and any worker that uses the same package.

    The linting change enters the routine window. The reviewer checks configuration differences, generated changes, and build output. It does not need the parser’s exposure analysis, but it still needs a reasoned validation path.

    The framework upgrade becomes planned migration work. The team identifies changed interfaces, tests the customer integration, and defines intermediate milestones. It does not bundle that project into the parser fix merely because both touch the same manifest.

    If the parser’s only viable fix requires the new framework, the decisions change: the migration becomes part of urgent remediation planning, with explicit mitigation while it is incomplete. The lanes organize work; they do not override the facts.

    The example illustrates a decision process, not a benchmark or a TechAID customer result. The same three changes could require different treatment in another application.

    Turn the workflow into a useful engineering brief

    Start by applying this workflow for dependency updates to one representative service. Map its ownership, classify its outstanding changes, and take one update all the way through verified deployment. Use what you learn to refine the evidence packet and remove a real source of delay before expanding the process.

    If that exercise shows a sustained implementation gap, discuss nearshore staff augmentation with TechAID. Bring a sample update backlog, your review and release constraints, and the skills the work requires. That creates a concrete conversation about embedded engineering capacity under your management—not a promise that staffing alone will solve unclear ownership or weak release controls.
    Related Posts