Top DevOps Skills Companies Need in 2026

Top DevOps Skills Companies Need in 2026

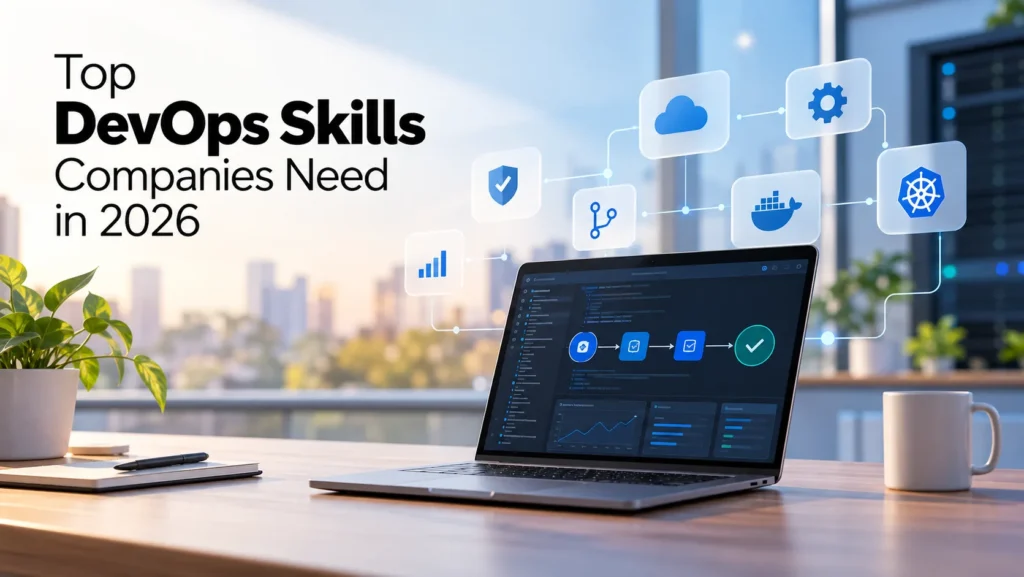
DevOps skills for 2026 illustrated with CI/CD, cloud, containers, security, monitoring, and Kubernetes around a modern engineering dashboard.
The DevOps skillset companies need in 2026 goes beyond knowing individual tools. This guide covers the automation, cloud infrastructure, CI/CD, observability, security, platform engineering, reliability, and collaboration skills modern engineering teams increasingly depend on.
Share the Post:

The DevOps skillset companies need in 2026 looks different from a traditional checklist of tools.

Knowing how to use Terraform, Kubernetes, GitHub Actions, or a cloud platform can be valuable, but companies increasingly need engineers who understand how those capabilities work together across the software delivery lifecycle.

A strong DevOps engineer should be able to connect:

Code → infrastructure → testing → deployment → security → observability → reliability

That requires both technical depth and the ability to understand how a change moves from development into production.

Google’s DORA DevOps capabilities reinforce this broader view. Rather than defining DevOps around individual products, DORA focuses on capabilities such as cloud infrastructure, continuous integration, continuous delivery, deployment automation, testing, and loosely coupled architecture.

The same shift is visible in cloud-native development.

CNCF’s State of Cloud Native Development Q1 2026 found that cloud infrastructure is now deeply embedded in modern software development, while platform engineering and standardized development environments are changing how engineers interact with that infrastructure.

For companies hiring or developing DevOps talent, the important question is therefore not:

“Which tools does this engineer know?”

It is:

“Can this person help us build a delivery system that is repeatable, secure, observable, and reliable?”

What Does a DevOps Skillset Look Like in 2026?

DevOps responsibilities vary significantly between organizations.

In one company, a DevOps engineer may spend most of the week improving CI/CD pipelines.

In another, the same title may involve:

  • Cloud infrastructure
  • Kubernetes
  • Infrastructure as Code
  • Security automation
  • Observability
  • Incident response
  • Developer platforms
  • Cost optimization
  • Release engineering

That is why hiring solely from a list of technologies can be misleading.

The underlying capabilities matter more.

A company running a relatively simple cloud application may not need deep Kubernetes expertise.

A large engineering organization operating hundreds of services may consider container orchestration, platform engineering, observability, and policy automation essential.

The right DevOps skillset should therefore reflect the environment the engineer will operate, the problems the team needs to solve, and the level of ownership the role will carry.

1. Infrastructure as Code and Automation

Infrastructure as Code remains one of the foundational DevOps engineer skills.

The goal is not simply to know Terraform syntax.

The engineer should understand how to make infrastructure:

  • Repeatable
  • Reviewable
  • Version controlled
  • Testable
  • Recoverable
  • Consistent across environments

Infrastructure changes should follow many of the same engineering disciplines as application code.

That includes:

  • Pull-request review
  • Version control
  • Automated validation
  • Approval controls
  • Change history
  • Clear ownership

An engineer should also understand what happens when the automation does not behave as expected.

For example:

  • What infrastructure will be replaced?
  • What permissions are changing?
  • Does the change affect production dependencies?
  • What happens if execution only partially succeeds?
  • Who approves high-risk changes?
  • What is the recovery path?

That distinction matters because automation reduces manual work, but it does not eliminate operational risk.

For teams using Terraform, a structured Terraform code review process can help reviewers evaluate the operational impact of infrastructure changes before they reach production.

IaC Skills Companies Should Look For

Depending on the environment, useful capabilities may include:

  • Terraform or another Infrastructure as Code framework
  • Reusable modules
  • State management
  • Environment separation
  • Infrastructure testing
  • Policy enforcement
  • Secrets handling
  • Change review
  • Cloud permissions
  • Automation scripting

The specific tool may change.

The more durable skill is understanding how to turn infrastructure changes into a controlled engineering process.

2. CI/CD and Release Engineering

A DevOps engineer should understand how software moves safely from a developer’s machine into production.

That means knowing more than how to configure a pipeline.

The engineer should understand the entire flow:

Commit → build → test → security checks → artifact creation → approval → deployment → verification

Google DORA identifies continuous integration and continuous delivery as core technical capabilities associated with software delivery performance.

The important skill is designing that flow so teams can release frequently without turning every deployment into a high-risk event.

Continuous Integration Skills

A strong CI process should provide fast evidence about whether a change is ready to move forward.

Useful skills include:

  • Build automation
  • Automated testing
  • Static analysis
  • Dependency checks
  • Branch and merge practices
  • Artifact creation
  • Pipeline troubleshooting

Engineers should also understand how to keep feedback fast enough that developers actually use it.

A pipeline that takes hours to provide basic feedback can slow development even if it eventually catches the right problems.

Continuous Delivery Skills

Continuous delivery adds another set of responsibilities.

The engineer needs to think about:

  • Deployment automation
  • Environment configuration
  • Approval gates
  • Rollback
  • Feature flags
  • Release strategies
  • Production verification

The objective is not simply to automate deployment.

It is to create a release process that teams trust.

Pipeline Reliability Matters Too

CI/CD infrastructure is production infrastructure.

If every deployment depends on the pipeline, then unreliable pipelines become a delivery bottleneck.

DevOps engineers should therefore be able to diagnose:

  • Flaky pipeline steps
  • Credential problems
  • Environment inconsistencies
  • Slow builds
  • Failed deployments
  • Broken dependencies

They should also know when a pipeline needs a human decision rather than another automated check.

3. Cloud and Container Infrastructure

Cloud infrastructure remains another core part of the modern DevOps skillset.

But companies should avoid turning “cloud experience” into a simple checklist of AWS, Azure, or Google Cloud services.

A stronger engineer understands the infrastructure concepts underneath those platforms.

That includes:

  • Compute
  • Networking
  • Storage
  • Identity and access
  • Load balancing
  • Scaling
  • Availability
  • Resource isolation
  • Backup and recovery

Those concepts transfer more effectively between cloud providers than memorizing individual service names.

Containers and Kubernetes

Containers are now common across modern delivery environments, but not every DevOps position requires deep Kubernetes specialization.

The skill level should match the organization’s architecture.

A team using a simple managed application platform may need basic container knowledge.

A company operating many distributed services may need engineers who understand:

  • Kubernetes workloads
  • Networking
  • Service discovery
  • Ingress
  • Configuration
  • Secrets
  • Resource limits
  • Autoscaling
  • Cluster security
  • Troubleshooting

CNCF’s 2026 cloud-native research shows that cloud-native technologies have become widely embedded in software development, while developers increasingly interact with that complexity through standardized environments and platform engineering.

That creates an important shift in the DevOps skillset.

The best engineer is not necessarily the person who exposes every infrastructure detail to developers.

Increasingly, the valuable skill is knowing which complexity should be automated or abstracted so product teams can work safely without becoming infrastructure experts.

Understand the Infrastructure, Even When It Is Abstracted

Platform engineering and managed cloud services can hide much of the underlying complexity.

That is useful.

But DevOps engineers still need enough understanding to troubleshoot what happens underneath those abstractions.

When a deployment fails, an engineer may need to determine whether the problem comes from:

  • Application code
  • Container configuration
  • Networking
  • Identity
  • Infrastructure capacity
  • Cloud services
  • The deployment platform

The ability to follow a problem across those layers is more valuable than knowing a long list of commands.

That systems-level understanding becomes increasingly important as the infrastructure stack grows more complex.

4. Observability and Production Troubleshooting

Deploying software is only part of the DevOps responsibility.

Engineers also need to understand what happens after the change reaches production.

That makes observability and troubleshooting core DevOps engineer skills.

A DevOps engineer should be comfortable working with:

  • Logs
  • Metrics
  • Traces
  • Alerts
  • Service dependencies
  • Infrastructure signals
  • Deployment events
  • Application behavior

The objective is not simply to collect more telemetry.

It is to use that evidence to answer practical questions:

  • What changed?
  • Which service is affected?
  • When did the problem begin?
  • Is the issue in the application or infrastructure?
  • Are users being affected?
  • Which dependency is failing?
  • Did a recent deployment introduce the problem?

The OpenTelemetry observability primer describes logs, metrics, and traces as signals that help teams understand system behavior and investigate problems they may not have predicted in advance.

Troubleshooting Across Layers

Modern production problems rarely stay inside one technical layer.

A slow application may actually be caused by:

  • Database latency
  • Network configuration
  • Resource limits
  • Container scheduling
  • Cloud capacity
  • A downstream API
  • A deployment configuration change

Strong DevOps engineers need enough systems knowledge to follow a problem across those boundaries.

That does not mean being the deepest expert in every technology.

It means knowing how to gather evidence, narrow the problem, involve the right owner, and avoid guessing.

Alerts Should Lead to Action

More alerts do not necessarily create better reliability.

Teams should understand:

  • What the alert means
  • Which service or capability it affects
  • Who owns the response
  • What evidence should be checked first
  • When escalation is necessary

An alert that nobody trusts becomes noise.

An alert connected to clear ownership and useful telemetry becomes an operational tool.

Observability Should Support Incident Response

Observability becomes especially valuable during incidents.

Engineers need to move from:

Alert → evidence → hypothesis → action → verification

rather than jumping directly from an alert to a production change.

That same principle becomes even more important as teams introduce AI into operations. Our guide to AI-assisted incident response looks at how AI can help investigate incidents while keeping evidence, approval, rollback, and production accountability explicit.

5. DevSecOps and Policy as Code

Security is no longer a separate step that happens after software is ready to deploy.

Modern DevOps skillsets increasingly include the ability to integrate security controls directly into development and delivery workflows.

That can include:

  • Identity and access management
  • Secrets management
  • Vulnerability scanning
  • Dependency checks
  • Container security
  • Infrastructure policy
  • Supply-chain controls
  • Compliance checks
  • Security gates in CI/CD

The goal is not to turn every DevOps engineer into a security specialist.

It is to ensure that delivery systems enforce important security expectations consistently.

Build Security Into the Workflow

A good delivery process should help engineers identify security problems before production.

For example, a pipeline may detect:

  • An infrastructure configuration that exposes a resource publicly
  • A dependency with a known vulnerability
  • A container running with unnecessary privileges
  • A secret committed to source control
  • An Infrastructure as Code change that violates an organizational policy

The important skill is understanding where automation is appropriate and where human judgment is still required.

A security scanner can identify a condition.

Someone still needs to understand whether the finding is relevant, what risk it creates, and how the issue should be resolved.

Understand Identity and Access

Permissions are one of the areas where DevOps and security responsibilities frequently intersect.

Engineers should understand concepts such as:

  • Least privilege
  • Service identities
  • Temporary credentials
  • Role-based access
  • Secret rotation
  • Environment separation
  • Production access controls

A deployment pipeline should not have unlimited access simply because automation needs credentials.

Likewise, developers should not need broad production access just to perform routine delivery tasks.

The ability to design automation without creating unnecessary privilege is an important DevOps skill.

Policy as Code

Policy as code turns organizational rules into automated, repeatable checks.

Examples may include:

  • Production resources cannot be publicly exposed without approval.
  • Certain cloud regions cannot be used.
  • Required ownership metadata must exist.
  • Critical infrastructure cannot be deleted without additional review.
  • Approved container sources must be used.

CNCF’s 2026 Technology Radar specifically evaluates security and policy management alongside workflow orchestration and application delivery, reflecting how closely these areas now operate inside cloud-native platforms.

Policy as code is valuable because it can make expectations consistent.

But companies should avoid creating hundreds of controls that nobody understands.

A useful policy should have:

  • A clear purpose
  • An owner
  • Defined exceptions
  • Test cases
  • A process for updating it

Security automation works best when teams trust the rules they are being asked to follow.

DevSecOps Requires Communication Too

Some security problems cannot be solved entirely in a pipeline.

Engineers still need to communicate with:

  • Security teams
  • Developers
  • Infrastructure owners
  • Compliance teams
  • Engineering leadership

A DevOps engineer should be able to explain why a control exists, what risk it reduces, and what trade-off an exception creates.

That ability is often more valuable than simply knowing how to configure another security tool.

6. Platform Engineering and Developer Experience

Platform engineering is becoming increasingly relevant to the DevOps skillset because companies are trying to reduce how much infrastructure knowledge every product developer needs to carry.

Instead of asking every engineering team to build its own:

  • CI/CD configuration
  • Cloud provisioning
  • Monitoring
  • Security checks
  • Deployment process
  • Environment setup

platform teams can turn common capabilities into reusable internal services.

CNCF’s 2026 research on platform engineering tools describes growing interest in technologies that reduce operational friction and standardize application delivery across internal platforms.

That changes what companies may expect from senior DevOps engineers.

The role increasingly includes thinking about the developer experience, not only infrastructure operation.

Build Reusable Paths Instead of Repeating Work

A platform-oriented DevOps engineer asks:

“Why are ten teams solving this same problem independently?”

Common capabilities can often be standardized.

Examples include:

  • Service templates
  • Deployment workflows
  • Infrastructure modules
  • Monitoring defaults
  • Security policies
  • Environment provisioning
  • CI/CD components

This allows teams to reuse a proven path instead of designing the same delivery process repeatedly.

Understand Self-Service Infrastructure

A mature internal platform should reduce unnecessary tickets between developers and infrastructure teams.

For routine tasks, a developer may be able to:

  • Create an environment
  • Provision a database
  • Deploy a service
  • Request standard cloud resources
  • Configure monitoring

without waiting for a DevOps engineer to perform each step manually.

The CNCF Platform Engineering Technical Community Group describes internal developer platforms around this idea of self-service infrastructure with consistency, security, and governance.

Self-service does not mean unlimited access.

The platform should provide safe boundaries, useful defaults, and clear escape paths for cases that need specialist review.

Learn to Think in Golden Paths

A golden path is a recommended way to perform a common engineering task.

For example, a company might provide a standard path for launching a new service that automatically includes:

  • Repository structure
  • CI/CD
  • Infrastructure
  • Monitoring
  • Security checks
  • Ownership information

Developers can then focus more on the application and less on rebuilding delivery infrastructure.

In 2026, CNCF’s platform engineering guidance increasingly emphasizes the move from collections of tools toward self-service platform interfaces.

That makes an important distinction for DevOps professionals:

The job is not always to do more infrastructure work for developers.

Sometimes the higher-value skill is building a system that allows developers to complete routine work safely without needing the platform team at all.

Developer Experience Is an Operational Concern

A technically powerful platform can still fail if developers cannot use it.

DevOps and platform engineers should therefore pay attention to questions such as:

  • Is the workflow understandable?
  • Can developers discover available capabilities?
  • How much documentation is required?
  • How long does it take to create a new service?
  • How many tickets are needed for routine infrastructure?
  • What happens when a team needs something outside the standard path?

Developer experience does not mean removing every technical constraint.

It means reducing unnecessary friction while keeping the controls that protect reliability, security, and maintainability.

Platform Engineering Does Not Replace DevOps

Platform engineering and DevOps overlap, but they are not identical.

DevOps is broader.

It includes the culture, practices, automation, delivery, and operational responsibilities that connect development and production.

Platform engineering applies many of those ideas to create reusable internal capabilities for engineering teams.

For companies with a small development organization, a dedicated platform may be unnecessary.

For larger organizations with many teams repeating the same infrastructure work, platform thinking can become an important DevOps capability.

The skill is knowing when standardization will reduce friction and when it will simply introduce another layer the organization has to maintain.

7. Reliability and Incident Response

DevOps engineers do not only help software reach production.

They also help keep it working once it gets there.

That makes reliability and incident response important parts of the DevOps skillset, especially for teams operating customer-facing systems.

Useful capabilities include:

  • Incident investigation
  • Production troubleshooting
  • Rollback and recovery
  • Change management
  • Service ownership
  • Runbooks
  • Post-incident analysis
  • Capacity planning
  • Reliability monitoring

The goal is not to prevent every failure.

Modern systems will fail.

The important skill is building systems and operating practices that help teams detect problems quickly, understand their impact, recover safely, and learn from what happened.

Understand the Difference Between a Symptom and a Cause

During an incident, the first alert may not identify the real problem.

For example, an API latency alert could result from:

  • A database issue
  • A failed deployment
  • Network degradation
  • An overloaded dependency
  • Cloud capacity
  • Incorrect configuration
  • A downstream service

A strong DevOps engineer should be able to gather evidence before changing production.

That means moving through a process such as:

Alert → evidence → hypothesis → mitigation → verification

rather than:

Alert → immediate change

The distinction becomes especially important when the system is complex and multiple teams are involved.

Recovery Is Part of Delivery

Teams often spend significant effort designing deployment automation but much less time planning what happens when deployment does not produce the expected result.

DevOps engineers should understand:

  • When rollback is safe
  • When rollback may create additional problems
  • How to restore service
  • How to validate recovery
  • What data may have changed
  • Who has authority to approve emergency actions

A successful deployment pipeline should therefore support both delivery and recovery.

Learn From Incidents

Incident response should not end when service is restored.

Teams should capture useful information about:

  • What happened
  • What signals identified the problem
  • What delayed diagnosis
  • Which controls worked
  • Which controls failed
  • What manual work could be automated
  • Whether ownership was clear

The objective is not to assign blame.

It is to reduce the likelihood that the same operational weakness creates the same problem again.

8. AI-Assisted DevOps Without Losing Control

AI is becoming another tool inside DevOps and SRE workflows.

But “AI skills” in DevOps should not simply mean knowing how to prompt a chatbot.

The more valuable capability is understanding where AI can accelerate operational work and where human judgment must remain in control.

Google has described how its SRE teams are using agentic AI in operational workflows for tasks such as investigation and incident analysis while maintaining established operational safeguards.

Potential DevOps use cases include:

  • Summarizing logs and alerts
  • Generating troubleshooting queries
  • Correlating incident evidence
  • Explaining configuration
  • Reviewing infrastructure changes
  • Drafting runbooks
  • Identifying possible root causes
  • Summarizing post-incident information

These capabilities can reduce repetitive work.

But they also create a new skill requirement:

Engineers need to know how to verify AI output.

Treat AI Output as Evidence to Review

An AI-generated explanation can sound convincing while still being wrong.

That means DevOps engineers should ask:

  • What evidence supports this conclusion?
  • Which logs or metrics confirm it?
  • Is the recommendation appropriate for this environment?
  • What could happen if this change is wrong?
  • Can the action be rolled back?
  • Does someone need to approve it?

AI should help accelerate investigation.

It should not automatically become production authority.

Our human-in-the-loop AI incident response runbook explores this approach in more detail, including evidence gathering, approvals, rollback, and verification.

Be Especially Careful With Production Changes

There is a significant difference between asking AI:

“Explain this error.”

and asking an automated system to:

“Fix production.”

The second request can affect customers, data, security, and service availability.

Companies adopting AI-assisted DevOps should therefore define boundaries around:

  • Read-only investigation
  • Recommendations
  • Change generation
  • Approval
  • Execution
  • Verification

Higher-impact actions should have stronger controls.

The skill companies increasingly need is not unrestricted automation.

It is controlled automation.

AI Does Not Replace Operational Foundations

AI can help teams investigate complex systems faster, but it does not remove the need for:

  • Observability
  • Documentation
  • Clear ownership
  • Reliable CI/CD
  • Infrastructure controls
  • Incident procedures
  • Security boundaries

In fact, AI is more useful when those foundations already exist.

An AI assistant cannot reliably explain a service if logs are incomplete, ownership is unclear, and deployment history is unavailable.

The quality of the operational system still determines the quality of the evidence available.

9. Communication, Ownership, and Systems Thinking

Some of the most important DevOps skills are not tied to a specific technology.

DevOps engineers operate between teams.

They regularly work with:

  • Software developers
  • Platform engineers
  • Security teams
  • QA engineers
  • SRE teams
  • Product teams
  • Engineering leadership

That means communication and ownership are not optional soft skills.

They are part of operating technical systems effectively.

Google DORA includes both technical and cultural capabilities in its DevOps research framework, emphasizing that software delivery performance depends on how teams work together as well as the technologies they use.

Explain Technical Risk Clearly

DevOps engineers often need to translate technical information into operational decisions.

For example:

Instead of:

“The Kubernetes ingress configuration is wrong.”

A useful explanation might be:

“This change would expose the service outside the private network, so it needs to be corrected before production deployment.”

The second explanation connects the technical issue to the actual risk.

That communication becomes especially important during:

  • Production incidents
  • Security reviews
  • Architecture decisions
  • Infrastructure changes
  • Release planning
  • Cost discussions

Engineers do not need to remove technical detail.

They need to make the consequence understandable.

Understand Ownership

Many DevOps problems are actually ownership problems.

For example:

  • Nobody owns a failing pipeline.
  • Several teams assume someone else maintains the Terraform modules.
  • Security expects the platform team to manage a control while the platform team expects application teams to manage it.
  • Everyone can deploy a service, but nobody owns its reliability.

Strong DevOps engineers help make those responsibilities explicit.

For each important system, teams should understand:

  • Who owns it
  • Who can change it
  • Who approves high-risk changes
  • Who responds when it fails
  • Who maintains the automation
  • Who decides when the system needs redesign

Clear ownership reduces operational ambiguity.

Develop Systems Thinking

DevOps engineers rarely work with isolated components.

A change in one place can affect several others.

For example:

A CI/CD change might affect security.

A network change might affect application performance.

A new cloud service might change cost and recovery requirements.

A Kubernetes configuration might affect both reliability and developer experience.

Systems thinking means understanding those connections instead of optimizing one component while creating problems elsewhere.

That requires asking:

  • What depends on this?
  • Who uses it?
  • What happens if it fails?
  • What changes operationally?
  • What new responsibility does this create?

These questions are often more important than knowing another command-line tool.

DevOps Engineer Skills vs DevOps Manager Skills

Companies should also distinguish between the skills needed to perform DevOps engineering work and the skills needed to lead the function.

There is significant overlap, but the responsibilities are different.

AreaDevOps EngineerDevOps Manager
AutomationBuilds and improves automationPrioritizes automation investments and standards
CI/CDImplements and troubleshoots pipelinesDefines delivery strategy and governance
Cloud infrastructureBuilds and operates infrastructurePlans capability, ownership, cost, and risk
ObservabilityImplements telemetry and investigates issuesDefines monitoring expectations and ownership
ReliabilityResponds to and prevents operational failuresEstablishes reliability priorities and processes
SecurityImplements delivery and infrastructure controlsCoordinates security expectations and accountability
Platform engineeringBuilds reusable capabilitiesDecides where platform investment creates value
Incident responseInvestigates and mitigates incidentsClarifies roles, escalation, and organizational response
Team developmentShares knowledge and collaboratesDevelops skills, staffing, and ownership across the team

Technical Depth Still Matters for DevOps Managers

Management responsibility does not eliminate the need to understand the technical environment.

A DevOps manager does not necessarily need to be the person writing every Terraform module or debugging every Kubernetes problem.

But they should understand enough to evaluate:

  • Delivery risk
  • Architecture trade-offs
  • Platform investment
  • Security requirements
  • Reliability priorities
  • Team capacity
  • Technical debt

Without that context, it becomes difficult to distinguish a tooling problem from an organizational problem.

Engineers Need Business Context Too

The opposite is also true.

A technically strong DevOps engineer should understand why the organization is building a particular capability.

For example:

The goal of faster CI/CD is not to maximize deployment count.

It is to help teams deliver useful changes more safely and efficiently.

The goal of platform engineering is not to build the most sophisticated internal platform.

It is to reduce repetitive work and make software delivery easier to operate.

The goal of observability is not to collect more telemetry.

It is to help teams understand and maintain production systems.

Connecting technical work to those outcomes is an increasingly important part of the DevOps skillset.

Which DevOps Skills Should Companies Prioritize?

Not every company needs the same DevOps skillset.

The right priorities depend on:

  • Engineering team size
  • Application architecture
  • Cloud complexity
  • Deployment frequency
  • Security requirements
  • Reliability expectations
  • Existing platform maturity
  • How much infrastructure product teams manage directly

A company should therefore define the problem before defining the job description.

“Need a DevOps engineer” is too broad.

A stronger starting point is:

“We need someone who can standardize infrastructure provisioning, improve CI/CD reliability, and reduce deployment risk across three product teams.”

That makes it easier to identify which skills actually matter.

Priorities for Smaller Engineering Teams

Smaller companies usually benefit from DevOps engineers with broad skills across the delivery lifecycle.

The role may need to cover:

  • Cloud infrastructure
  • Infrastructure as Code
  • CI/CD
  • Basic observability
  • Security fundamentals
  • Troubleshooting
  • Automation

Specialization may be less useful when one engineer needs to support several parts of the delivery system.

In this environment, companies should prioritize engineers who can simplify operations rather than introduce unnecessary complexity.

For example, a small team may benefit more from a reliable deployment pipeline and well-managed cloud infrastructure than from building a sophisticated internal developer platform.

The strongest DevOps engineer for that organization may be the person who knows when not to add another tool.

Priorities for Growing Engineering Organizations

As the number of developers and services increases, DevOps priorities begin to shift.

Growing organizations often need stronger capabilities in:

  • Reusable Infrastructure as Code
  • CI/CD standardization
  • Observability
  • Security automation
  • Container infrastructure
  • Reliability
  • Environment management
  • Developer self-service

At this stage, repeated operational work becomes easier to see.

Several teams may be:

  • Building similar pipelines
  • Creating similar infrastructure
  • Solving the same access problems
  • Configuring monitoring independently
  • Maintaining slightly different deployment processes

That is where platform engineering skills can start becoming more valuable.

The goal is not necessarily to create a dedicated platform team immediately.

It is to identify which repeated capabilities should become reusable and standardized.

Priorities for Larger Engineering Organizations

Larger organizations typically need greater specialization and stronger governance.

Important skills may include:

  • Platform engineering
  • Kubernetes and container orchestration
  • Advanced observability
  • Reliability engineering
  • Policy as code
  • Cloud governance
  • Cost management
  • Service ownership
  • Incident management
  • Security automation

The challenge becomes balancing autonomy and standardization.

Product teams need enough freedom to deliver independently, but the organization also needs shared expectations around:

  • Security
  • Deployment
  • Monitoring
  • Infrastructure
  • Reliability
  • Ownership

Senior DevOps and platform engineers increasingly help define those boundaries.

Match Skills to the Architecture

Architecture also changes the type of DevOps expertise a company needs.

A monolithic application with one engineering team may require:

  • Reliable CI/CD
  • Infrastructure automation
  • Cloud administration
  • Basic monitoring
  • Strong troubleshooting

A distributed microservices environment may require much deeper expertise in:

  • Service observability
  • Kubernetes
  • Distributed networking
  • Deployment strategies
  • Platform engineering
  • Service ownership
  • Incident response

Companies evaluating this trade-off can also review our guide to monolith vs microservices for scaling engineering teams to understand how architecture affects delivery and operational complexity.

The key point is that DevOps hiring should follow the operating model.

The operating model should not be designed around whichever tools appear most frequently in DevOps job descriptions.

How to Evaluate a DevOps Skillset

A resume can show technologies.

It does not always show whether the engineer understands how those technologies work together.

Companies should evaluate DevOps engineers through scenarios that reflect the environment they will actually operate.

For example:

Infrastructure Scenario

Ask:

“A Terraform plan unexpectedly shows that a production resource will be replaced. What do you review before approving it?”

A strong answer should go beyond syntax.

The engineer may discuss:

  • Why the replacement appeared
  • Data or service dependencies
  • Recovery
  • Application impact
  • Approval
  • Testing

CI/CD Scenario

Ask:

“A deployment pipeline is becoming slower and less reliable as the team grows. How would you investigate it?”

Useful answers may consider:

  • Build time
  • Test reliability
  • Pipeline architecture
  • Dependencies
  • Artifact handling
  • Security checks
  • Environment consistency
  • Failure history

Incident Scenario

Ask:

“An application becomes slow immediately after deployment, but infrastructure dashboards look healthy. What do you do next?”

The objective is not to hear one correct command.

It is to understand how the engineer:

  • Gathers evidence
  • Forms hypotheses
  • Uses observability
  • Communicates with other teams
  • Controls production changes
  • Verifies recovery

Platform Scenario

Ask:

“Five development teams maintain nearly identical deployment pipelines. What would you standardize, and what would you leave configurable?”

This reveals whether the candidate understands the difference between useful standardization and unnecessary centralization.

Evaluate Judgment, Not Trivia

Technical depth matters.

But interviews should avoid becoming memory tests for command syntax or obscure configuration options unless those details are genuinely essential to the role.

A strong DevOps engineer should demonstrate:

  • Technical reasoning
  • Operational judgment
  • Understanding of trade-offs
  • Clear communication
  • Ownership
  • Ability to investigate uncertainty

Tools can be learned.

Weak judgment in production environments is harder to compensate for.

Basic DevOps Skills Still Matter

Newer areas such as AI-assisted operations and platform engineering should not distract from the fundamentals.

The DevOps basic skills companies still need include:

  • Linux and operating-system fundamentals
  • Networking
  • Git and version control
  • Scripting
  • Cloud fundamentals
  • Infrastructure automation
  • CI/CD
  • Monitoring
  • Security basics
  • Troubleshooting

These foundational skills help engineers understand what automation is actually doing.

Without them, tools can become black boxes.

An engineer who understands networking can troubleshoot a failed service connection more effectively than someone who only knows how to redeploy the workload.

An engineer who understands operating systems can investigate resource problems rather than immediately increasing capacity.

The tools evolve.

The underlying systems knowledge remains valuable.

DevOps Agile Skills Are Also About Flow

DevOps and Agile overlap around the goal of improving how quickly and safely teams deliver value.

Useful DevOps agile skills include:

  • Working in small increments
  • Reducing manual handoffs
  • Shortening feedback loops
  • Collaborating across functions
  • Making work visible
  • Continuously improving the delivery process

DevOps should not create another silo between development and operations.

The objective is to improve the entire delivery flow.

That means asking:

  • Where does work wait?
  • Which approvals add value?
  • Which steps are repetitive?
  • Where does feedback arrive too late?
  • Which responsibilities are unclear?
  • What can be automated safely?

The answers are often more valuable than introducing another DevOps platform.

The Skills Matter More Than the Tool List

DevOps tools change quickly.

A hiring strategy built entirely around today’s tool names can become outdated faster than the underlying responsibilities.

The more durable DevOps skillset combines:

  • Automation
  • Infrastructure knowledge
  • CI/CD
  • Cloud
  • Observability
  • Security
  • Reliability
  • Platform thinking
  • Communication
  • Systems thinking

Tools sit underneath those capabilities.

Terraform may be used for infrastructure.

Kubernetes may be used for orchestration.

GitHub Actions, GitLab CI, Jenkins, or another platform may support delivery.

Prometheus, OpenTelemetry, or commercial platforms may support observability.

The specific stack depends on the company.

The engineering problem does not.

Companies should therefore start with the outcomes they need and then determine which tools support them.

The DevOps Skillset in 2026 Is About End-to-End Ownership

The strongest DevOps professionals increasingly understand more than one isolated part of the software lifecycle.

They can see how:

Infrastructure affects delivery.

Delivery affects security.

Security affects developer workflows.

Observability affects incident response.

Platform decisions affect engineering productivity.

Reliability affects customers.

That ability to connect systems, teams, and operational outcomes is what makes the DevOps skillset valuable.

Companies do not need every DevOps engineer to be an expert in every technology.

They need the right combination of skills for the systems they operate and the problems they are trying to solve.

Before opening another role with a long list of tools, define what the engineer needs to improve.

Then hire for the capabilities required to produce that outcome.

If your team needs additional DevOps, cloud, platform, or infrastructure capacity, start a conversation with TechAID.
Key Takeaways
  • The DevOps skillset companies need in 2026 goes beyond individual tools and includes automation, cloud infrastructure, CI/CD, observability, security, reliability, and platform engineering.

  • Companies should prioritize DevOps skills based on their architecture, team size, operational maturity, and the problems they need to solve rather than copying generic tool lists.


  • Platform engineering and AI-assisted operations are becoming increasingly relevant, but they do not replace foundational skills such as networking, cloud, troubleshooting, Infrastructure as Code, and CI/CD.

  • Strong DevOps professionals combine technical depth with ownership, communication, and systems thinking across the full software delivery lifecycle.

  • The DevOps skillset companies need in 2026 looks different from a traditional checklist of tools.

    Knowing how to use Terraform, Kubernetes, GitHub Actions, or a cloud platform can be valuable, but companies increasingly need engineers who understand how those capabilities work together across the software delivery lifecycle.

    A strong DevOps engineer should be able to connect:

    Code → infrastructure → testing → deployment → security → observability → reliability

    That requires both technical depth and the ability to understand how a change moves from development into production.

    Google’s DORA DevOps capabilities reinforce this broader view. Rather than defining DevOps around individual products, DORA focuses on capabilities such as cloud infrastructure, continuous integration, continuous delivery, deployment automation, testing, and loosely coupled architecture.

    The same shift is visible in cloud-native development.

    CNCF’s State of Cloud Native Development Q1 2026 found that cloud infrastructure is now deeply embedded in modern software development, while platform engineering and standardized development environments are changing how engineers interact with that infrastructure.

    For companies hiring or developing DevOps talent, the important question is therefore not:

    “Which tools does this engineer know?”

    It is:

    “Can this person help us build a delivery system that is repeatable, secure, observable, and reliable?”

    What Does a DevOps Skillset Look Like in 2026?

    DevOps responsibilities vary significantly between organizations.

    In one company, a DevOps engineer may spend most of the week improving CI/CD pipelines.

    In another, the same title may involve:

    • Cloud infrastructure
    • Kubernetes
    • Infrastructure as Code
    • Security automation
    • Observability
    • Incident response
    • Developer platforms
    • Cost optimization
    • Release engineering

    That is why hiring solely from a list of technologies can be misleading.

    The underlying capabilities matter more.

    A company running a relatively simple cloud application may not need deep Kubernetes expertise.

    A large engineering organization operating hundreds of services may consider container orchestration, platform engineering, observability, and policy automation essential.

    The right DevOps skillset should therefore reflect the environment the engineer will operate, the problems the team needs to solve, and the level of ownership the role will carry.

    1. Infrastructure as Code and Automation

    Infrastructure as Code remains one of the foundational DevOps engineer skills.

    The goal is not simply to know Terraform syntax.

    The engineer should understand how to make infrastructure:

    • Repeatable
    • Reviewable
    • Version controlled
    • Testable
    • Recoverable
    • Consistent across environments

    Infrastructure changes should follow many of the same engineering disciplines as application code.

    That includes:

    • Pull-request review
    • Version control
    • Automated validation
    • Approval controls
    • Change history
    • Clear ownership

    An engineer should also understand what happens when the automation does not behave as expected.

    For example:

    • What infrastructure will be replaced?
    • What permissions are changing?
    • Does the change affect production dependencies?
    • What happens if execution only partially succeeds?
    • Who approves high-risk changes?
    • What is the recovery path?

    That distinction matters because automation reduces manual work, but it does not eliminate operational risk.

    For teams using Terraform, a structured Terraform code review process can help reviewers evaluate the operational impact of infrastructure changes before they reach production.

    IaC Skills Companies Should Look For

    Depending on the environment, useful capabilities may include:

    • Terraform or another Infrastructure as Code framework
    • Reusable modules
    • State management
    • Environment separation
    • Infrastructure testing
    • Policy enforcement
    • Secrets handling
    • Change review
    • Cloud permissions
    • Automation scripting

    The specific tool may change.

    The more durable skill is understanding how to turn infrastructure changes into a controlled engineering process.

    2. CI/CD and Release Engineering

    A DevOps engineer should understand how software moves safely from a developer’s machine into production.

    That means knowing more than how to configure a pipeline.

    The engineer should understand the entire flow:

    Commit → build → test → security checks → artifact creation → approval → deployment → verification

    Google DORA identifies continuous integration and continuous delivery as core technical capabilities associated with software delivery performance.

    The important skill is designing that flow so teams can release frequently without turning every deployment into a high-risk event.

    Continuous Integration Skills

    A strong CI process should provide fast evidence about whether a change is ready to move forward.

    Useful skills include:

    • Build automation
    • Automated testing
    • Static analysis
    • Dependency checks
    • Branch and merge practices
    • Artifact creation
    • Pipeline troubleshooting

    Engineers should also understand how to keep feedback fast enough that developers actually use it.

    A pipeline that takes hours to provide basic feedback can slow development even if it eventually catches the right problems.

    Continuous Delivery Skills

    Continuous delivery adds another set of responsibilities.

    The engineer needs to think about:

    • Deployment automation
    • Environment configuration
    • Approval gates
    • Rollback
    • Feature flags
    • Release strategies
    • Production verification

    The objective is not simply to automate deployment.

    It is to create a release process that teams trust.

    Pipeline Reliability Matters Too

    CI/CD infrastructure is production infrastructure.

    If every deployment depends on the pipeline, then unreliable pipelines become a delivery bottleneck.

    DevOps engineers should therefore be able to diagnose:

    • Flaky pipeline steps
    • Credential problems
    • Environment inconsistencies
    • Slow builds
    • Failed deployments
    • Broken dependencies

    They should also know when a pipeline needs a human decision rather than another automated check.

    3. Cloud and Container Infrastructure

    Cloud infrastructure remains another core part of the modern DevOps skillset.

    But companies should avoid turning “cloud experience” into a simple checklist of AWS, Azure, or Google Cloud services.

    A stronger engineer understands the infrastructure concepts underneath those platforms.

    That includes:

    • Compute
    • Networking
    • Storage
    • Identity and access
    • Load balancing
    • Scaling
    • Availability
    • Resource isolation
    • Backup and recovery

    Those concepts transfer more effectively between cloud providers than memorizing individual service names.

    Containers and Kubernetes

    Containers are now common across modern delivery environments, but not every DevOps position requires deep Kubernetes specialization.

    The skill level should match the organization’s architecture.

    A team using a simple managed application platform may need basic container knowledge.

    A company operating many distributed services may need engineers who understand:

    • Kubernetes workloads
    • Networking
    • Service discovery
    • Ingress
    • Configuration
    • Secrets
    • Resource limits
    • Autoscaling
    • Cluster security
    • Troubleshooting

    CNCF’s 2026 cloud-native research shows that cloud-native technologies have become widely embedded in software development, while developers increasingly interact with that complexity through standardized environments and platform engineering.

    That creates an important shift in the DevOps skillset.

    The best engineer is not necessarily the person who exposes every infrastructure detail to developers.

    Increasingly, the valuable skill is knowing which complexity should be automated or abstracted so product teams can work safely without becoming infrastructure experts.

    Understand the Infrastructure, Even When It Is Abstracted

    Platform engineering and managed cloud services can hide much of the underlying complexity.

    That is useful.

    But DevOps engineers still need enough understanding to troubleshoot what happens underneath those abstractions.

    When a deployment fails, an engineer may need to determine whether the problem comes from:

    • Application code
    • Container configuration
    • Networking
    • Identity
    • Infrastructure capacity
    • Cloud services
    • The deployment platform

    The ability to follow a problem across those layers is more valuable than knowing a long list of commands.

    That systems-level understanding becomes increasingly important as the infrastructure stack grows more complex.

    4. Observability and Production Troubleshooting

    Deploying software is only part of the DevOps responsibility.

    Engineers also need to understand what happens after the change reaches production.

    That makes observability and troubleshooting core DevOps engineer skills.

    A DevOps engineer should be comfortable working with:

    • Logs
    • Metrics
    • Traces
    • Alerts
    • Service dependencies
    • Infrastructure signals
    • Deployment events
    • Application behavior

    The objective is not simply to collect more telemetry.

    It is to use that evidence to answer practical questions:

    • What changed?
    • Which service is affected?
    • When did the problem begin?
    • Is the issue in the application or infrastructure?
    • Are users being affected?
    • Which dependency is failing?
    • Did a recent deployment introduce the problem?

    The OpenTelemetry observability primer describes logs, metrics, and traces as signals that help teams understand system behavior and investigate problems they may not have predicted in advance.

    Troubleshooting Across Layers

    Modern production problems rarely stay inside one technical layer.

    A slow application may actually be caused by:

    • Database latency
    • Network configuration
    • Resource limits
    • Container scheduling
    • Cloud capacity
    • A downstream API
    • A deployment configuration change

    Strong DevOps engineers need enough systems knowledge to follow a problem across those boundaries.

    That does not mean being the deepest expert in every technology.

    It means knowing how to gather evidence, narrow the problem, involve the right owner, and avoid guessing.

    Alerts Should Lead to Action

    More alerts do not necessarily create better reliability.

    Teams should understand:

    • What the alert means
    • Which service or capability it affects
    • Who owns the response
    • What evidence should be checked first
    • When escalation is necessary

    An alert that nobody trusts becomes noise.

    An alert connected to clear ownership and useful telemetry becomes an operational tool.

    Observability Should Support Incident Response

    Observability becomes especially valuable during incidents.

    Engineers need to move from:

    Alert → evidence → hypothesis → action → verification

    rather than jumping directly from an alert to a production change.

    That same principle becomes even more important as teams introduce AI into operations. Our guide to AI-assisted incident response looks at how AI can help investigate incidents while keeping evidence, approval, rollback, and production accountability explicit.

    5. DevSecOps and Policy as Code

    Security is no longer a separate step that happens after software is ready to deploy.

    Modern DevOps skillsets increasingly include the ability to integrate security controls directly into development and delivery workflows.

    That can include:

    • Identity and access management
    • Secrets management
    • Vulnerability scanning
    • Dependency checks
    • Container security
    • Infrastructure policy
    • Supply-chain controls
    • Compliance checks
    • Security gates in CI/CD

    The goal is not to turn every DevOps engineer into a security specialist.

    It is to ensure that delivery systems enforce important security expectations consistently.

    Build Security Into the Workflow

    A good delivery process should help engineers identify security problems before production.

    For example, a pipeline may detect:

    • An infrastructure configuration that exposes a resource publicly
    • A dependency with a known vulnerability
    • A container running with unnecessary privileges
    • A secret committed to source control
    • An Infrastructure as Code change that violates an organizational policy

    The important skill is understanding where automation is appropriate and where human judgment is still required.

    A security scanner can identify a condition.

    Someone still needs to understand whether the finding is relevant, what risk it creates, and how the issue should be resolved.

    Understand Identity and Access

    Permissions are one of the areas where DevOps and security responsibilities frequently intersect.

    Engineers should understand concepts such as:

    • Least privilege
    • Service identities
    • Temporary credentials
    • Role-based access
    • Secret rotation
    • Environment separation
    • Production access controls

    A deployment pipeline should not have unlimited access simply because automation needs credentials.

    Likewise, developers should not need broad production access just to perform routine delivery tasks.

    The ability to design automation without creating unnecessary privilege is an important DevOps skill.

    Policy as Code

    Policy as code turns organizational rules into automated, repeatable checks.

    Examples may include:

    • Production resources cannot be publicly exposed without approval.
    • Certain cloud regions cannot be used.
    • Required ownership metadata must exist.
    • Critical infrastructure cannot be deleted without additional review.
    • Approved container sources must be used.

    CNCF’s 2026 Technology Radar specifically evaluates security and policy management alongside workflow orchestration and application delivery, reflecting how closely these areas now operate inside cloud-native platforms.

    Policy as code is valuable because it can make expectations consistent.

    But companies should avoid creating hundreds of controls that nobody understands.

    A useful policy should have:

    • A clear purpose
    • An owner
    • Defined exceptions
    • Test cases
    • A process for updating it

    Security automation works best when teams trust the rules they are being asked to follow.

    DevSecOps Requires Communication Too

    Some security problems cannot be solved entirely in a pipeline.

    Engineers still need to communicate with:

    • Security teams
    • Developers
    • Infrastructure owners
    • Compliance teams
    • Engineering leadership

    A DevOps engineer should be able to explain why a control exists, what risk it reduces, and what trade-off an exception creates.

    That ability is often more valuable than simply knowing how to configure another security tool.

    6. Platform Engineering and Developer Experience

    Platform engineering is becoming increasingly relevant to the DevOps skillset because companies are trying to reduce how much infrastructure knowledge every product developer needs to carry.

    Instead of asking every engineering team to build its own:

    • CI/CD configuration
    • Cloud provisioning
    • Monitoring
    • Security checks
    • Deployment process
    • Environment setup

    platform teams can turn common capabilities into reusable internal services.

    CNCF’s 2026 research on platform engineering tools describes growing interest in technologies that reduce operational friction and standardize application delivery across internal platforms.

    That changes what companies may expect from senior DevOps engineers.

    The role increasingly includes thinking about the developer experience, not only infrastructure operation.

    Build Reusable Paths Instead of Repeating Work

    A platform-oriented DevOps engineer asks:

    “Why are ten teams solving this same problem independently?”

    Common capabilities can often be standardized.

    Examples include:

    • Service templates
    • Deployment workflows
    • Infrastructure modules
    • Monitoring defaults
    • Security policies
    • Environment provisioning
    • CI/CD components

    This allows teams to reuse a proven path instead of designing the same delivery process repeatedly.

    Understand Self-Service Infrastructure

    A mature internal platform should reduce unnecessary tickets between developers and infrastructure teams.

    For routine tasks, a developer may be able to:

    • Create an environment
    • Provision a database
    • Deploy a service
    • Request standard cloud resources
    • Configure monitoring

    without waiting for a DevOps engineer to perform each step manually.

    The CNCF Platform Engineering Technical Community Group describes internal developer platforms around this idea of self-service infrastructure with consistency, security, and governance.

    Self-service does not mean unlimited access.

    The platform should provide safe boundaries, useful defaults, and clear escape paths for cases that need specialist review.

    Learn to Think in Golden Paths

    A golden path is a recommended way to perform a common engineering task.

    For example, a company might provide a standard path for launching a new service that automatically includes:

    • Repository structure
    • CI/CD
    • Infrastructure
    • Monitoring
    • Security checks
    • Ownership information

    Developers can then focus more on the application and less on rebuilding delivery infrastructure.

    In 2026, CNCF’s platform engineering guidance increasingly emphasizes the move from collections of tools toward self-service platform interfaces.

    That makes an important distinction for DevOps professionals:

    The job is not always to do more infrastructure work for developers.

    Sometimes the higher-value skill is building a system that allows developers to complete routine work safely without needing the platform team at all.

    Developer Experience Is an Operational Concern

    A technically powerful platform can still fail if developers cannot use it.

    DevOps and platform engineers should therefore pay attention to questions such as:

    • Is the workflow understandable?
    • Can developers discover available capabilities?
    • How much documentation is required?
    • How long does it take to create a new service?
    • How many tickets are needed for routine infrastructure?
    • What happens when a team needs something outside the standard path?

    Developer experience does not mean removing every technical constraint.

    It means reducing unnecessary friction while keeping the controls that protect reliability, security, and maintainability.

    Platform Engineering Does Not Replace DevOps

    Platform engineering and DevOps overlap, but they are not identical.

    DevOps is broader.

    It includes the culture, practices, automation, delivery, and operational responsibilities that connect development and production.

    Platform engineering applies many of those ideas to create reusable internal capabilities for engineering teams.

    For companies with a small development organization, a dedicated platform may be unnecessary.

    For larger organizations with many teams repeating the same infrastructure work, platform thinking can become an important DevOps capability.

    The skill is knowing when standardization will reduce friction and when it will simply introduce another layer the organization has to maintain.

    7. Reliability and Incident Response

    DevOps engineers do not only help software reach production.

    They also help keep it working once it gets there.

    That makes reliability and incident response important parts of the DevOps skillset, especially for teams operating customer-facing systems.

    Useful capabilities include:

    • Incident investigation
    • Production troubleshooting
    • Rollback and recovery
    • Change management
    • Service ownership
    • Runbooks
    • Post-incident analysis
    • Capacity planning
    • Reliability monitoring

    The goal is not to prevent every failure.

    Modern systems will fail.

    The important skill is building systems and operating practices that help teams detect problems quickly, understand their impact, recover safely, and learn from what happened.

    Understand the Difference Between a Symptom and a Cause

    During an incident, the first alert may not identify the real problem.

    For example, an API latency alert could result from:

    • A database issue
    • A failed deployment
    • Network degradation
    • An overloaded dependency
    • Cloud capacity
    • Incorrect configuration
    • A downstream service

    A strong DevOps engineer should be able to gather evidence before changing production.

    That means moving through a process such as:

    Alert → evidence → hypothesis → mitigation → verification

    rather than:

    Alert → immediate change

    The distinction becomes especially important when the system is complex and multiple teams are involved.

    Recovery Is Part of Delivery

    Teams often spend significant effort designing deployment automation but much less time planning what happens when deployment does not produce the expected result.

    DevOps engineers should understand:

    • When rollback is safe
    • When rollback may create additional problems
    • How to restore service
    • How to validate recovery
    • What data may have changed
    • Who has authority to approve emergency actions

    A successful deployment pipeline should therefore support both delivery and recovery.

    Learn From Incidents

    Incident response should not end when service is restored.

    Teams should capture useful information about:

    • What happened
    • What signals identified the problem
    • What delayed diagnosis
    • Which controls worked
    • Which controls failed
    • What manual work could be automated
    • Whether ownership was clear

    The objective is not to assign blame.

    It is to reduce the likelihood that the same operational weakness creates the same problem again.

    8. AI-Assisted DevOps Without Losing Control

    AI is becoming another tool inside DevOps and SRE workflows.

    But “AI skills” in DevOps should not simply mean knowing how to prompt a chatbot.

    The more valuable capability is understanding where AI can accelerate operational work and where human judgment must remain in control.

    Google has described how its SRE teams are using agentic AI in operational workflows for tasks such as investigation and incident analysis while maintaining established operational safeguards.

    Potential DevOps use cases include:

    • Summarizing logs and alerts
    • Generating troubleshooting queries
    • Correlating incident evidence
    • Explaining configuration
    • Reviewing infrastructure changes
    • Drafting runbooks
    • Identifying possible root causes
    • Summarizing post-incident information

    These capabilities can reduce repetitive work.

    But they also create a new skill requirement:

    Engineers need to know how to verify AI output.

    Treat AI Output as Evidence to Review

    An AI-generated explanation can sound convincing while still being wrong.

    That means DevOps engineers should ask:

    • What evidence supports this conclusion?
    • Which logs or metrics confirm it?
    • Is the recommendation appropriate for this environment?
    • What could happen if this change is wrong?
    • Can the action be rolled back?
    • Does someone need to approve it?

    AI should help accelerate investigation.

    It should not automatically become production authority.

    Our human-in-the-loop AI incident response runbook explores this approach in more detail, including evidence gathering, approvals, rollback, and verification.

    Be Especially Careful With Production Changes

    There is a significant difference between asking AI:

    “Explain this error.”

    and asking an automated system to:

    “Fix production.”

    The second request can affect customers, data, security, and service availability.

    Companies adopting AI-assisted DevOps should therefore define boundaries around:

    • Read-only investigation
    • Recommendations
    • Change generation
    • Approval
    • Execution
    • Verification

    Higher-impact actions should have stronger controls.

    The skill companies increasingly need is not unrestricted automation.

    It is controlled automation.

    AI Does Not Replace Operational Foundations

    AI can help teams investigate complex systems faster, but it does not remove the need for:

    • Observability
    • Documentation
    • Clear ownership
    • Reliable CI/CD
    • Infrastructure controls
    • Incident procedures
    • Security boundaries

    In fact, AI is more useful when those foundations already exist.

    An AI assistant cannot reliably explain a service if logs are incomplete, ownership is unclear, and deployment history is unavailable.

    The quality of the operational system still determines the quality of the evidence available.

    9. Communication, Ownership, and Systems Thinking

    Some of the most important DevOps skills are not tied to a specific technology.

    DevOps engineers operate between teams.

    They regularly work with:

    • Software developers
    • Platform engineers
    • Security teams
    • QA engineers
    • SRE teams
    • Product teams
    • Engineering leadership

    That means communication and ownership are not optional soft skills.

    They are part of operating technical systems effectively.

    Google DORA includes both technical and cultural capabilities in its DevOps research framework, emphasizing that software delivery performance depends on how teams work together as well as the technologies they use.

    Explain Technical Risk Clearly

    DevOps engineers often need to translate technical information into operational decisions.

    For example:

    Instead of:

    “The Kubernetes ingress configuration is wrong.”

    A useful explanation might be:

    “This change would expose the service outside the private network, so it needs to be corrected before production deployment.”

    The second explanation connects the technical issue to the actual risk.

    That communication becomes especially important during:

    • Production incidents
    • Security reviews
    • Architecture decisions
    • Infrastructure changes
    • Release planning
    • Cost discussions

    Engineers do not need to remove technical detail.

    They need to make the consequence understandable.

    Understand Ownership

    Many DevOps problems are actually ownership problems.

    For example:

    • Nobody owns a failing pipeline.
    • Several teams assume someone else maintains the Terraform modules.
    • Security expects the platform team to manage a control while the platform team expects application teams to manage it.
    • Everyone can deploy a service, but nobody owns its reliability.

    Strong DevOps engineers help make those responsibilities explicit.

    For each important system, teams should understand:

    • Who owns it
    • Who can change it
    • Who approves high-risk changes
    • Who responds when it fails
    • Who maintains the automation
    • Who decides when the system needs redesign

    Clear ownership reduces operational ambiguity.

    Develop Systems Thinking

    DevOps engineers rarely work with isolated components.

    A change in one place can affect several others.

    For example:

    A CI/CD change might affect security.

    A network change might affect application performance.

    A new cloud service might change cost and recovery requirements.

    A Kubernetes configuration might affect both reliability and developer experience.

    Systems thinking means understanding those connections instead of optimizing one component while creating problems elsewhere.

    That requires asking:

    • What depends on this?
    • Who uses it?
    • What happens if it fails?
    • What changes operationally?
    • What new responsibility does this create?

    These questions are often more important than knowing another command-line tool.

    DevOps Engineer Skills vs DevOps Manager Skills

    Companies should also distinguish between the skills needed to perform DevOps engineering work and the skills needed to lead the function.

    There is significant overlap, but the responsibilities are different.

    AreaDevOps EngineerDevOps Manager
    AutomationBuilds and improves automationPrioritizes automation investments and standards
    CI/CDImplements and troubleshoots pipelinesDefines delivery strategy and governance
    Cloud infrastructureBuilds and operates infrastructurePlans capability, ownership, cost, and risk
    ObservabilityImplements telemetry and investigates issuesDefines monitoring expectations and ownership
    ReliabilityResponds to and prevents operational failuresEstablishes reliability priorities and processes
    SecurityImplements delivery and infrastructure controlsCoordinates security expectations and accountability
    Platform engineeringBuilds reusable capabilitiesDecides where platform investment creates value
    Incident responseInvestigates and mitigates incidentsClarifies roles, escalation, and organizational response
    Team developmentShares knowledge and collaboratesDevelops skills, staffing, and ownership across the team

    Technical Depth Still Matters for DevOps Managers

    Management responsibility does not eliminate the need to understand the technical environment.

    A DevOps manager does not necessarily need to be the person writing every Terraform module or debugging every Kubernetes problem.

    But they should understand enough to evaluate:

    • Delivery risk
    • Architecture trade-offs
    • Platform investment
    • Security requirements
    • Reliability priorities
    • Team capacity
    • Technical debt

    Without that context, it becomes difficult to distinguish a tooling problem from an organizational problem.

    Engineers Need Business Context Too

    The opposite is also true.

    A technically strong DevOps engineer should understand why the organization is building a particular capability.

    For example:

    The goal of faster CI/CD is not to maximize deployment count.

    It is to help teams deliver useful changes more safely and efficiently.

    The goal of platform engineering is not to build the most sophisticated internal platform.

    It is to reduce repetitive work and make software delivery easier to operate.

    The goal of observability is not to collect more telemetry.

    It is to help teams understand and maintain production systems.

    Connecting technical work to those outcomes is an increasingly important part of the DevOps skillset.

    Which DevOps Skills Should Companies Prioritize?

    Not every company needs the same DevOps skillset.

    The right priorities depend on:

    • Engineering team size
    • Application architecture
    • Cloud complexity
    • Deployment frequency
    • Security requirements
    • Reliability expectations
    • Existing platform maturity
    • How much infrastructure product teams manage directly

    A company should therefore define the problem before defining the job description.

    “Need a DevOps engineer” is too broad.

    A stronger starting point is:

    “We need someone who can standardize infrastructure provisioning, improve CI/CD reliability, and reduce deployment risk across three product teams.”

    That makes it easier to identify which skills actually matter.

    Priorities for Smaller Engineering Teams

    Smaller companies usually benefit from DevOps engineers with broad skills across the delivery lifecycle.

    The role may need to cover:

    • Cloud infrastructure
    • Infrastructure as Code
    • CI/CD
    • Basic observability
    • Security fundamentals
    • Troubleshooting
    • Automation

    Specialization may be less useful when one engineer needs to support several parts of the delivery system.

    In this environment, companies should prioritize engineers who can simplify operations rather than introduce unnecessary complexity.

    For example, a small team may benefit more from a reliable deployment pipeline and well-managed cloud infrastructure than from building a sophisticated internal developer platform.

    The strongest DevOps engineer for that organization may be the person who knows when not to add another tool.

    Priorities for Growing Engineering Organizations

    As the number of developers and services increases, DevOps priorities begin to shift.

    Growing organizations often need stronger capabilities in:

    • Reusable Infrastructure as Code
    • CI/CD standardization
    • Observability
    • Security automation
    • Container infrastructure
    • Reliability
    • Environment management
    • Developer self-service

    At this stage, repeated operational work becomes easier to see.

    Several teams may be:

    • Building similar pipelines
    • Creating similar infrastructure
    • Solving the same access problems
    • Configuring monitoring independently
    • Maintaining slightly different deployment processes

    That is where platform engineering skills can start becoming more valuable.

    The goal is not necessarily to create a dedicated platform team immediately.

    It is to identify which repeated capabilities should become reusable and standardized.

    Priorities for Larger Engineering Organizations

    Larger organizations typically need greater specialization and stronger governance.

    Important skills may include:

    • Platform engineering
    • Kubernetes and container orchestration
    • Advanced observability
    • Reliability engineering
    • Policy as code
    • Cloud governance
    • Cost management
    • Service ownership
    • Incident management
    • Security automation

    The challenge becomes balancing autonomy and standardization.

    Product teams need enough freedom to deliver independently, but the organization also needs shared expectations around:

    • Security
    • Deployment
    • Monitoring
    • Infrastructure
    • Reliability
    • Ownership

    Senior DevOps and platform engineers increasingly help define those boundaries.

    Match Skills to the Architecture

    Architecture also changes the type of DevOps expertise a company needs.

    A monolithic application with one engineering team may require:

    • Reliable CI/CD
    • Infrastructure automation
    • Cloud administration
    • Basic monitoring
    • Strong troubleshooting

    A distributed microservices environment may require much deeper expertise in:

    • Service observability
    • Kubernetes
    • Distributed networking
    • Deployment strategies
    • Platform engineering
    • Service ownership
    • Incident response

    Companies evaluating this trade-off can also review our guide to monolith vs microservices for scaling engineering teams to understand how architecture affects delivery and operational complexity.

    The key point is that DevOps hiring should follow the operating model.

    The operating model should not be designed around whichever tools appear most frequently in DevOps job descriptions.

    How to Evaluate a DevOps Skillset

    A resume can show technologies.

    It does not always show whether the engineer understands how those technologies work together.

    Companies should evaluate DevOps engineers through scenarios that reflect the environment they will actually operate.

    For example:

    Infrastructure Scenario

    Ask:

    “A Terraform plan unexpectedly shows that a production resource will be replaced. What do you review before approving it?”

    A strong answer should go beyond syntax.

    The engineer may discuss:

    • Why the replacement appeared
    • Data or service dependencies
    • Recovery
    • Application impact
    • Approval
    • Testing

    CI/CD Scenario

    Ask:

    “A deployment pipeline is becoming slower and less reliable as the team grows. How would you investigate it?”

    Useful answers may consider:

    • Build time
    • Test reliability
    • Pipeline architecture
    • Dependencies
    • Artifact handling
    • Security checks
    • Environment consistency
    • Failure history

    Incident Scenario

    Ask:

    “An application becomes slow immediately after deployment, but infrastructure dashboards look healthy. What do you do next?”

    The objective is not to hear one correct command.

    It is to understand how the engineer:

    • Gathers evidence
    • Forms hypotheses
    • Uses observability
    • Communicates with other teams
    • Controls production changes
    • Verifies recovery

    Platform Scenario

    Ask:

    “Five development teams maintain nearly identical deployment pipelines. What would you standardize, and what would you leave configurable?”

    This reveals whether the candidate understands the difference between useful standardization and unnecessary centralization.

    Evaluate Judgment, Not Trivia

    Technical depth matters.

    But interviews should avoid becoming memory tests for command syntax or obscure configuration options unless those details are genuinely essential to the role.

    A strong DevOps engineer should demonstrate:

    • Technical reasoning
    • Operational judgment
    • Understanding of trade-offs
    • Clear communication
    • Ownership
    • Ability to investigate uncertainty

    Tools can be learned.

    Weak judgment in production environments is harder to compensate for.

    Basic DevOps Skills Still Matter

    Newer areas such as AI-assisted operations and platform engineering should not distract from the fundamentals.

    The DevOps basic skills companies still need include:

    • Linux and operating-system fundamentals
    • Networking
    • Git and version control
    • Scripting
    • Cloud fundamentals
    • Infrastructure automation
    • CI/CD
    • Monitoring
    • Security basics
    • Troubleshooting

    These foundational skills help engineers understand what automation is actually doing.

    Without them, tools can become black boxes.

    An engineer who understands networking can troubleshoot a failed service connection more effectively than someone who only knows how to redeploy the workload.

    An engineer who understands operating systems can investigate resource problems rather than immediately increasing capacity.

    The tools evolve.

    The underlying systems knowledge remains valuable.

    DevOps Agile Skills Are Also About Flow

    DevOps and Agile overlap around the goal of improving how quickly and safely teams deliver value.

    Useful DevOps agile skills include:

    • Working in small increments
    • Reducing manual handoffs
    • Shortening feedback loops
    • Collaborating across functions
    • Making work visible
    • Continuously improving the delivery process

    DevOps should not create another silo between development and operations.

    The objective is to improve the entire delivery flow.

    That means asking:

    • Where does work wait?
    • Which approvals add value?
    • Which steps are repetitive?
    • Where does feedback arrive too late?
    • Which responsibilities are unclear?
    • What can be automated safely?

    The answers are often more valuable than introducing another DevOps platform.

    The Skills Matter More Than the Tool List

    DevOps tools change quickly.

    A hiring strategy built entirely around today’s tool names can become outdated faster than the underlying responsibilities.

    The more durable DevOps skillset combines:

    • Automation
    • Infrastructure knowledge
    • CI/CD
    • Cloud
    • Observability
    • Security
    • Reliability
    • Platform thinking
    • Communication
    • Systems thinking

    Tools sit underneath those capabilities.

    Terraform may be used for infrastructure.

    Kubernetes may be used for orchestration.

    GitHub Actions, GitLab CI, Jenkins, or another platform may support delivery.

    Prometheus, OpenTelemetry, or commercial platforms may support observability.

    The specific stack depends on the company.

    The engineering problem does not.

    Companies should therefore start with the outcomes they need and then determine which tools support them.

    The DevOps Skillset in 2026 Is About End-to-End Ownership

    The strongest DevOps professionals increasingly understand more than one isolated part of the software lifecycle.

    They can see how:

    Infrastructure affects delivery.

    Delivery affects security.

    Security affects developer workflows.

    Observability affects incident response.

    Platform decisions affect engineering productivity.

    Reliability affects customers.

    That ability to connect systems, teams, and operational outcomes is what makes the DevOps skillset valuable.

    Companies do not need every DevOps engineer to be an expert in every technology.

    They need the right combination of skills for the systems they operate and the problems they are trying to solve.

    Before opening another role with a long list of tools, define what the engineer needs to improve.

    Then hire for the capabilities required to produce that outcome.

    If your team needs additional DevOps, cloud, platform, or infrastructure capacity, start a conversation with TechAID.
    Related Posts